The Programmer’s Guide to Hating AI – Part 6: The Age of the Poser Programmer

Introduction

We can’t just throw code together until it appears to work; we must concern ourselves with the structure of code. Paradoxically, concerns for structure and “quality of code” are often the fastest ways of getting something to work. When programming is done well, such concerns minimize the need for the most frustrating part of programming: debugging; that is, good program structure during development can minimize the number of mistakes made and the time needed to search for such errors and remove them.

…It is very tempting to dash ahead, focusing on the parts of programming that… are concrete and immediately useful and to ignore the “softer”, more conceptual parts of the art of software development. However, good programmers and system designers know (often having learned it the hard way) that concerns about structure lie at the heart of good software and that ignoring structure leads to expensive messes. Without structure, you are (metaphorically speaking) building with mud bricks. It can be done, but you’ll never get to the tenth floor (classical mud bricks lack the structural strength for that). If you have the ambition to build something reasonably permanent or something large, you pay attention to matters of code structure and organization along the way, rather than having to come back and learn them after failures.

Bjarne Stroustrup – Programming: Principles and Practices Using C++ (Third Ed.)

In the last part, I analyzed the folly of programmers delegating coding. Now it’s time to wrap up the series with why programmers are interested in doing that in the first place.

“Learn to code” was a mistake.

Remember that? It was a popular retort in the late 10s, eventually becoming a sarcastic taunt aimed at recently laid off people by their adversaries. Somewhere in the last 15-20 years of so, the “hot career” that everyone wanted to get into because the day-to-day work was comfortable and it guaranteed good pay and job security became computer programming. It used to be professionally degreed and licensed fields, such as doctors and lawyers. But that requires not just going to years of expensive school (4 years of undergrad, usually 2 years for the professional degree, and often years of some kind of residency after that) but being a good enough student to make it through all the certifications. Ideally those filters are in place to properly remove the people who are simply not qualified to do the job (they aren’t “smart” enough, or able or willing to pay enough attention to detail, or memorize enough source material, etc.).

The whole point of making professionals do all of that is to filter out most candidates. Obviously everyone would love to make a doctor’s or lawyer’s salary for work that’s entirely in an office. That means it attracts lots and lots of people who only care about money and, to be honest, would like to be lazy and avoid any strenuous labor. So we decided we need to filter those people out, which ends up being the vast majority of people who try to enter the field, in order to prevent people from abusing the career. Unfortunately the real world isn’t so neat. School has gotten so absurdly expensive people are now questioning if doctors/lawyers are even financially secure (they may make >$200k/year but have to pay off enormous student loans for most of their working years), and people have increasingly noticed for decades that universities tend to produce a specific type of obedient walking encyclopedia (basically a “meat LLM”) rather than genuinely intelligent, capable and invested graduates. This can end up filtering out some of the best people, but especially filters in a lot of the kind you don’t want and crowds out the good ones.

And then there’s computer programming, which is unique in two ways. First, there is no hard requirement for school. There is no licensure, no professional degree (the closest thing is a bachelor’s degree in computer science) and a lot of HR departments at corporations only require some bachelor’s degree (or even a lesser college degree like an associate’s), if they have a hard requirement at all. A lot of them only require this for candidates with no professional experience, which sounds like a Catch 22 for people without degrees, but startups, paid internships, etc. are opportunities to gain professional experience without that requirement, and then once you have a couple years, whether you have a degree or not (and what it’s in) stops mattering.

Here I am, 15 years into a software engineering career, and I have a bachelor’s degree in physics. I took two courses from the computer science department and nearly flunked one of them (also, I had written code to mod video games for years and was trying to build a video game console emulator as a side project).

Second, it is a 100% desk job. Doctors and lawyers often have to do things that go beyond just sitting in their offices, working on documents and talking to people. But this is all programmers do. They just work at computers all day. This not only makes it the pinnacle of a cushy “white collar” job, it also means it can done entirely remotely, which led to programming jobs starting to go remote even before the COVID pandemic. The job is similar to other types of engineering in that way (all engineers just produce design documents), although engineers in other fields may need to go “on site” if their designs are driving manufacturing. But those fields have harder requirements for engineering degrees (which, unlike computer science, are not part of the Arts & Sciences schools at universities, you have to decide to enter the engineering school).

So computer programming is basically the only option for people who are either too old or don’t have the time or money to spare to go back to school and earn a new degree, and start making good money working 100% at a desk either in an office or more likely from home. Especially to anyone who doesn’t actually know what programmers do (there’s a reason it’s a high paying job), this sounds like a fantasy come true, so a lot of people who otherwise have absolutely no interest in computer science, programming or even computers at all, but just want this nice career, decided to enter the field… and the main filter to try to screen out unqualified or even fraudulent candidates is mostly technical interviews, which people have put considerable effort into gaming.

The problem is programming as a job is basically a full time job of solving complex logic puzzles and math problems. Does getting paid a lot to sit in front of a computer compared to working in service or construction sound nice? Well, what if I told you it’s going to be like you’re back in school, but your classes are 8 hours long, it’s all math class (no English or history or art, etc.), and you have people breathing down your neck to correctly solve it yesterday please? For most people I’ve met, who readily volunteer to me they hate math, I can assure you “this is the most comfy job ever, you’ll love it!” would be a Faustian deal worthy of a Twilight Zone episode that ends with them screaming, “NOOOOOO!!!!” as the twisted irony settles in.

In the 10s, an industry arose specifically to facilitate this career switch, in the form of “coding bootcamps”: short, intensive training programs for people with no background in coding to quickly get up to speed enough to perform at an entry level programming job. Unlike professions like doctors or lawyers, where concern with quality and correctness have consistently trumped concerns with quantity (healthcare and legal representation are famously expensive, often ruinously, so there’s a clear supply issue, but we’ve all decided opening up the field to shoddy practitioners to drop the price isn’t a good idea), there was a huge demand for more programmers, so quickly training a lot of people seemed like a good idea and the companies who employ programmers supported it. They were struggling to find people.

What’s going on now with “AI Programming”, which doesn’t mean programmers adding AI to their tool belts and pulling it out on occasion when a particular task calls for it, but rather a revolutionary overhaul of the field to something entirely new (to the point corporations whose executives have full blown AI psychosis are retitling their software developers, no longer calling them “engineers” or “developers” but some new word, to indicate everything they do is now completely changed) that involves no “programming” in the traditional sense (“coding”), is a completely inevitable and predictable consequence of this rush (or, if you’re less charitable, invasion) of warm bodies into the field of programming whose only reason to be there is to get paid highly to sit in front of a computer for 40 hours/week.

People have been noticing the degradation of the software development field for a long time, and this has led to throwing out the word “gatekeeping” as an attack on any attempt to defend against or reverse it. Well, I’m a gatekeeper. I’m sorry, but everyone shouldn’t be a professional programmer, and I think a pretty good litmus test for that is if someone so intensely hates coding that he will do literally anything (including build elaborate Rube Goldberg machines out of expensive and unreliable “AI agents”) to avoid doing it as much as possible. Someone who feels that way about coding making himself do it for a full time job sounds like torture. I don’t think I’m being “mean” by telling those guys, “hey man, I don’t think this job is well suited for you”. The issue is they don’t have any other career options, and that’s the real problem that’s becoming a crisis in our society. Ironically, the “AI Revolution” would solve that, so it’s quite unfortunate that revolution is fake.

AI Programming Is the Latest Version of “Code Quality Doesn’t Matter”

When AI programmers are confronted about the quality of code that chatbot-driven coding produces, on rare occasion they will insist chatbots write high quality code that outdoes anything human programmers could do. The things are just geniuses. But more importantly, however good the code they write today is, it will be even better in six months (“just one more model, bro”). I remember one of them said something like, “just wait until AI is writing code more optimized than John Carmack’s Doom engine code”. So this is just AI cultists who think AI is God the App and it’s going to “wake up” any day and tell us all the secrets of the universe. They never present any examples or explain why they think this is true, it’s just the same “AI is AI, it’s magical and will just keep getting better” psychosis as “it’s going to replace all office work and usher in a post-scarcity utopia, unless it’s the bad kind and it turns us all into paperclips”.

The much more common response is rather: “okay maybe it writes sloppy code, but have you seen the code humans write? It’s a bunch of slop too!” That argumentative strategy tells us everything we need to know. Contained within it is two implications:

  • Either all, or the vast majority, of computer programmers write low quality slop code
  • It doesn’t matter and isn’t a problem that most code is low quality slop

The first point is curious because whenever someone argues this, you should ask them: does that include you? Their answer either has to be “yes, therefore I’m an incompetent programmer”, or “no, I’m a very special and rare talent that rises above almost everyone else”. Neither one of these are a claim they’re probably excited to make out loud and stick to. The second one is at least reasonable but it requires evidence, and we all know the irony of Dunning-Kruger that everyone thinks they’re a rare genius, but if everyone thinks that, obviously it’s not a rare belief, so the vast majority of them must be delusional about themselves.

The mostly likely reply you’ll get from an AI coder is the first: “yes I’m incompetent”. They have this really weird tendency to denigrate themselves in order to praise the AI God. When they show you some completely wrong, useless pile of slop the chatbot blurted out and you tell them it’s wrong and useless, they will reflexively reply with, “well that’s my fault for not knowing how to prompt it better!” (as Pivot to AI‘s logo says, “it can’t be that stupid, you must be prompting it wrong”), as if the whole point of their existence is to lower themselves at the feet of AI and say “I’m not worthy”. In case you still don’t think this is some kind of weird religion…

But the first point isn’t the important part. It’s the second point. If switching from human coding to AI coding is merely preserving the low code quality but doing it faster or cheaper, then apparently code quality doesn’t matter, or at best it matters but is less of a concern than being fast and cheap, and that implies that code quality is independent of how quickly and cheaply development work can be done.

AI coders are coders who believe code quality isn’t what determines the speed, cost and efficiency of managing a software product.

They readily admit chatbots are not somehow solving the low code quality problem (which they concede is not only a problem but a ubiquitous problem), at best they are sidestepping it by removing the humans who are the only ones slowed down by low quality code. This is the critical point we need to understand: AI coders think improving code quality is either not a priority or actively distracting and a waste of time.

This is not new (how often do I say that!). A subset of people who either do programming professionally, as part of open source projects, or as a hobby in personal projects, have always believed that code quality is an irrelevant distraction and burden on programming that just slows it down and overcomplicates it. They like to say things like, “just make it work” or “it doesn’t matter how pretty it is”. If they believed this in 2022, they still believe it in 2026 and love that AI has finally and officially freed us from ever having to talk or worry about code quality, which it does by making “coding dead” and then “code reviewing dead”. You can’t possibly worry about code quality if you’re never even glancing at the code!

(As I explained in the last part, no that’s not true, the problem of quality and design just reemerges in the “agentic coding” artifacts that people do write and review themselves, i.e. the prompts, skill files, spec files, etc.)

The point is this isn’t something that AI caused. AI just revealed or (since it was already revealed to those of us in the field paying attention to it) amplified it. The programmers arguing that code quality doesn’t matter have had to debate programmers like me who argue the opposite this whole time, and since they haven’t changed our minds, they do what salespeople always do and “throw mud at the wall and see what sticks”, just trying every possible avenue that leads to the foregone conclusion to see if we find that one persuasive. So when AI showed up, this just provided a new avenue to argue this point. They already believed the conclusion, they just see this as hopefully an opportunity to get those of us who don’t believe it to either start believing it, or at least shut up about it.

Also, they now have product departments and executives backing them, which has given them confidence to argue against more senior and lead engineers knowing they have the grace of the people who are all the engineers’ bosses. This didn’t change their minds about anything, it just made them louder and bolder. And it created a feedback loop where product people/executives latched onto these types of programmers, who told them what they want to hear (that maintenance and long-term investment into software isn’t a thing, and being ultra-shortsighted and shoving in features as fast as possible to max out next quarter earnings is actually the best way to do run a sustainable business… in this way it’s just continuing what Agile Inc. consultants started), and then went onto LinkedIn or to conferences and repeated it, and further emboldened programmers who already felt that way to start being louder.

Yes, Code Quality Does In Fact Matter

As I stated, I am one of the programmers these guys have to argue with. I couldn’t summarize my perspective on software engineering more succinctly than “code quality is everything”. I really shouldn’t have to argue this. I have heard some variation of the phrase, “the problem with programmers is they care too much about the code, when it’s the product that matters” more times than I can count. This is an astounding thing to utter and I don’t think I even fully appreciate how incredible it is.

Programmers saying “code quality doesn’t matter” is like:

  • Chefs saying recipe quality doesn’t matter
  • Home builders saying architecture doesn’t matter
  • Lawyers saying the accuracy of their legal case doesn’t matter
  • Doctors saying how carefully they listen to their patients doesn’t matter

“All that matters is that it works” is a thought-terminating cliche. It’s an empty tautology, because “matters” and “works” are essentially synonyms. Yeah, sure, the goal of making things is to make things that do what the thing is supposed to do. You understand there is no insight in that whatsoever, right? It’s like saying the Law of Identity (A is A) like it’s some kind of profound bombshell revelation about the world.

If a chef uses bad recipes, his food will suck. It won’t “work”. If home builders use bad architectural designs, their homes will suck. They won’t “work”. If lawyers make cases with bad arguments, they will lose cases. It won’t “work”. If doctors don’t listen to their patients, they’ll miss symptom details and misdiagnose them (and then mistreat them). It won’t “work”.

If you write low quality code, your software will suck. Software is rapidly iterative and incrementally modified, so that very often takes the form of “you got the first iteration out the door, but now you can’t increment on it”. “Works” in software doesn’t mean you delivered version 1.0. Your work isn’t done at that point. And when it comes time to deliver version 1.1, you have to go back into the code you wrote for version 1.0, and suddenly it matters not just that version 1.0 code satisfies the requirements of version 1.0, but that it can be easily and safely modified to satisfy the new requirements for version 1.1. So “works” is not the same thing as “satisfies today’s requirements”.

The belief that code quality doesn’t matter is plainly absurd to anyone who has worked enough in this industry to see what’s going on. I have worked for several large corporations who own large, old (10-20 years) gigantic piles of low quality spaghetti code, and the low quality of that code is a constant source of anxiety and frustration at every one of these companies (I mean for the business guys, not the coders). They all have growing backlogs of bugs that keep coming back (“regressions”). They regularly schedule “bug bashes” where they halt all forward progress on the system for a period to have the entire (meaning dozens to hundreds of programmers) organization do nothing but try to fix these bugs. This always backfires.

The attempts to rapidly fix a bunch of bugs inevitably causes more bugs, and the backlog of bugs ends up larger after every “bug bash”. Feature work proceeds at a snail’s pace. It’s very difficult to make changes (“adding a button will take a month”), and very risky because it will probably introduce a lot more bugs. Companies hire expensive consultants specifically to deal with low code quality and teach the organization how to deal with it. Even if said consultants are incompetent and just make it worse, the fact an attempt was made at all to deal with it tells you the business takes it very seriously.

In fact, what a lot of these big companies are doing is trying to rewrite their flagship products from scratch. Why would you do this!? Why would you waste so much time and effort recreating what you already have!? The answer is because the business is sick of trying to do any work on the systems they have and want to just wave away all the tech debt they’ve accumulated. They get further misled by rewrites because they proceed very quickly and smoothly at the beginning, encouraging the belief that this is just how things will be in the rewritten product once it is production ready.

They don’t understand that it was their corporate culture and practices that caused such a drop in quality in the first place, and since the rewrite is expensive to develop, serves zero customers (and thus makes zero revenue) and will not serve any until it reaches “parity”, it is very urgent to get it to parity, so guess what? It gets rushed! Developers are pushed to do things as fast as possible, under even more pressure than they were under the first time they did it. The result is an even worse product with even lower quality as it starts to approach parity, and once the reality that work on this product is even slower and more unstable than the live one becomes clear, the most likely fate is for it to be cancelled, making the entire effort a waste of time. Even worse, if they try releasing it to a few customers, they still realize it will never replace the original product, but they don’t want to cut off those customers so now they have to maintain both! And since they deliberately didn’t reuse any code from the original system (that would be polluting the new thing with all that old tech debt), they have two copies of all their business logic to try to keep in sync!

Software companies being either unable or unwilling to produce decent quality code is not “fine”. The fact it’s what most of them have been doing for decades (i.e. that it is normal) is not the same as it being okay. Yes, it’s normal. Low quality code is the typical case. And so is everyone inside these companies running around like chickens with their heads cut off, talking about how things are “on fire” all the time, wishcasting ridiculous deadlines without involving engineers at all (because they know what the engineers will tell them), and blowing massive amounts of money on attempts (that usually fail) to do something about it.

In fact, and this is the ultimate irony here, the reason why software executives are so obsessed with AI is because they think that’s their magic wand to wave this all away. The narrative being presented inside of software companies that are “embracing AI” and insist it’s “the future” isn’t some super-optimistic vision about making ultra-fancy futuristic software that people will be amazed by. No, the narrative is what we’ve been doing isn’t working and we need to change. I’ve even heard, direct quote, “the human software development lifecycle doesn’t work”. The reason they want the chatbots so badly to save them is because they have something to be saved from. Their businesses are slowly failing, they’re losing customers, it’s too expensive to keep their systems alive, much less do active development on them, and this is all because the quality of their codebases is so bad!

So if adopting AI coding is going to do nothing to solve the quality issue but just speed up the pace at which low quality code (i.e. tech debt) is produced, it’s just going to accelerate the decline of these systems! I believe this is the most likely fate of companies who do this for too long. They will throw chatbots at their legacy slop codebases, which will ensloppify them so much more that they become unusably unstable. Whether that makes all the customers leave or not depends on the competition, and the competitors are probably all doing the same right now, but SaaS is always competing with Excel spreadsheets, so it’s a matter of whether all the options get so bad it’s genuinely worse than just doing it all with Excel (hopefully Excel isn’t being ensloppified too).

To whatever extent these products are still going when everyone wakes up from this bender with a throbbing headache, the need for highly skilled “AI slop cleanup” programming shops will skyrocket. The best way to make it obvious how important code quality is, is for everyone to ruin the quality of their code to the point it causes a calamity, so… I guess there’s a silver lining to this.

The Equivocation of Passion and Vanity

By repeating the “what matters is it works” empty tautology every time they get into this debate, these guys are implying people like me who argue code quality does matter don’t care about software working. They’re arguing we care about something else. They think our fixation on code quality is an aesthetic indulgence or fetish, like we just open code editors and stare at “high quality” code, getting some kind of thrill or titillation out of just looking at it, and all code quality does is tickle our fancies.

The accusation that programmers who care about code quality just have a “fetish” for “pretty” code is much more significant than I think people realize. They will even call the belief that code quality matters programmer vanity. They claim we’re just using code quality to congratulate ourselves for being so smart and talented at programming (and better than other programmers) instead of caring about the companies who employ us, their software products or the customers who use those software products. So, we’re just selfish, self-indulgent, arrogant weirdos with a sexual attraction to “pretty code” and we want to turn the profession of programming into a self-serving way to get paid to indulge our weird fetish and feel good about ourselves.

When you say all this out loud, it really begs the question: are these guys sure this isn’t just a silly, ignorant and rather unfair straw man? Because it sure sounds like it when it’s all laid out plainly.

This isn’t just about programming. This is a general characterization of passion as vanity. The equivocation of these two behavioral traits is astounding, and once you realize that’s what this is, it quickly follows that a more likely explanation is this is what impassive and disinterested people think of people with passion. The idea that people being passionate (highly motivated and enthusiastic) about doing certain types of work causes them to poorly execute that work (and instead get distracted with aspects of it that don’t matter) is very bizarre. It’s like saying Isaac Newton being so weirdly obsessed with physics he was thinking about gravity while sitting under an apple tree relaxing would cause him to never reach any genuine insights in physics and instead just write a bunch of pretty equations down, stare at them and touch himself.

No, most of us understand the people who get that weirdly enthusiastic about things the rest of us consider to be tedious schoolwork we couldn’t wait to get done with are exactly the ones you want to pay to just sit around and follow that passion all day, because they’re the most likely ones to discover the next breakthrough. And also, that making the people who find the subject uninspiring, uninteresting and a chore to work on are not likely to do good work in the area. They are rather likely to just phone it in and do the least amount of work to check the box and free themselves of having to be further burdened by it (since, after all, they consider working on it to be a burden).

I mean, does the idea that some nerd can’t sleep at night because he’s stuck on the math problem he’s trying to solve and can’t let go of it because he’s so passionately obsessed with math thwarts his ability to eventually solve that problem, compared to the guy who “hates math” and couldn’t be happier to be out of school and never have to do it again, really make sense to anyone? Is this really what people are trying to argue, here?

To whatever extent programmers who really do enjoy and get obsessed with the craft of software development get some kind of emotional satisfaction out of authoring high quality, well-designed code, this is a consequence of their passion for the work. But why are they passionate about it? Or rather, what exactly are they passionate about? Why does “high quality” code tickle their fancy but “low quality” code doesn’t? They derive satisfaction from code being “high quality” because high quality code is valuable. It does the job, it accomplishes what software development seeks to accomplish, which is build working software, so effectively. It is this feature of code, so effectively and powerfully doing its job, that provides the “beauty” programmers find so desirable.

Math nerds don’t think wrong proofs are “beautiful” because the symbols are arranged in highly patterned ways. Whatever “beauty” might emerge from the patterns suddenly and completely disappears if it’s incorrect. And the reason why a succinct and patterned proof is more “beautiful” than a convoluted and meandering one is because it expresses the underlying truth more directly and thoroughly. It is never about viewing the positions or shapes of symbols as graphically pleasing like it’s a painting or something. That might be what people who “don’t get” being passionate about math think it is, but that’s only because they don’t get it.

Also, it is a blatant mischaracterization of passionate nerds to say they’re vain and just doing it to market themselves as smart and talented. This is exactly what I would expect people who LARP as passionate nerds to say as a “confession as accusation”: that’s what they’re doing by pretending to be passionate nerds, so they assume everyone else presenting an outward appearance of passionate nerddom must be doing the same. No, my friend, you underestimate just how weird passionate nerds really are. They’re not insecure people who just want to be popular and respected (a basic and widely shared human condition that “normal” people all understand and experience) and figured pretending to be passionate about technical fields is a way to achieve that. They really are, genuinely in the bottom of their hearts, obsessed with the thing. Math nerds are actually obsessed with math and think about it all the time. They’re not thinking about what you think of them all the time. They really, truly are thinking about math while they’re standing alone at the party sipping a drink. Yes, they’re that weird.

They aren’t staying up until 2am working on a problem so they can tell you about it later and make you think “wow, that guy’s really passionate about stuff, that makes him interesting”. It isn’t vanity. Yes, people who are very vain will LARP as passionate nerds, so now we have a problem of a bunch of imposters warping the perception of what passion even is, but that’s a problem because it warps the perception. Passion is about the thing you’re passionate about, not you. If it was always about you and not the thing, that was never passion, it was vanity. These are not only different, they’re almost opposites. We might say vanity is self-passion (being obsessed with and enthusiastic about one’s own reputation or value as a human being), which means it is specifically not a passion about things outside oneself.

The fact software company executives have been harassing (in many cases explicitly threatening to chase out, although I don’t think they really follow up on these threats) the subset of programmers on their payroll who are passionately obsessed with coding and lie awake at night thinking about how to improve the design of their products’ codebases to let it go, stop caring and just prompt chatbots all day is so bizarrely self-defeating. I can’t imagine a more incompetent attitude for an executive to hold. This is like a restaurant telling the head chef who’s passionate about cooking to get lost, or a movie director telling the artists who love drawing and were doing it as 8 year olds and have a bunch of side projects they do in their free time to get lost.

The comments on YouTube videos about what’s happening in programming have been filled all through 2026 with depressed coders talking not about how they were fired, they’re still employed, but they have been forced to stop investing into their work and just phone it in with chatbots instead, and this makes their job boring and unfulfilling (the term they’ve coined for what they now are is “meat proxy”). Congratulations, tech executives! Not only have you destroyed the talent pipeline for your own industry for years to come, you’re killing the passion in your most enthusiastic employees who actually got obsessed with your products and don’t just come in, move JIRA tickets around and take your money. I couldn’t sabotage a software company more effectively if you paid me an executive’s salary to try.

This equivocation of passion with vanity is about as reliable as an indicator of LARPing I can think of. Anyone who argues this either has no passions and doesn’t understand what it means to have one, or (more likely I think) he is a vain person who can’t imagine why people would exhibit behaviors for any reason except for self-congratulation. This is evident from the fact people who argue this are doing so (and this is certainly the case with the loudest AI boosters) in an attempt to sell themselves as better in some way, usually as more productive and efficient (i.e. “10x productivity”) than all those self-obsessed people who just like staring at their own creations.

This is a problem in programming because so many people joined the profession for no other reason than to make money, so they’re practically commanded to LARP as people who care about programming and what it takes to do it well. They don’t actually care about any of that, they just want to take the paycheck and go home, but they can’t say that out loud because then they destroy their own career prospects. They have to pretend to care, and this takes the form of arguing “caring actually means not caring and just half-assing all the work, since quality isn’t even really a thing here”.

“Code quality doesn’t matter, just make it work” is the calling card of the poser programmer. It is the confession that they don’t care about their craft, they’re checked out and just want to put in the minimum effort to get paid. Turning the highly technical and cognitively demanding job of computer programming into babysitting chatbots is just the logical conclusion of what poser programmers have always been out to achieve: to be called programmers and get paid as programmers without ever doing any programming.

Does AI Programming Somehow Force Quality to Improve?

Some proponents of handing the coding part of programming off to chatbots will pay lip service to code quality still being a concern. Funny enough, their argument usually works by badmouthing AI: basically chatbots are uncontrollable overpowered tools, like a machine gun with no mount but that fires so fast the recoil makes it impossible for someone to aim it, so the only thing you can do with it is “spray and pray”. On its own this is quite useless: such chatbots will write tons of code, some of it will be what you want, and much more of it will be what you don’t want.

But it can be made useful if you install a filter, usually in the form of an exhaustive suite of automated tests (see the graphic from the last part that shows how “testing” grows to replace “implementation”), but also if you robustly design a system with lots of compile time guardrails that will trip if something is broken. Then you can run a loop where the chatbot does something, it fails one of these tests, you discard it and feed the error back into the chatbot, and eventually it will converge to something that passes all the tests, and then you accept that. Since this is fully automated, the fact the chatbot has to make, who knows? 3? 10? 100 failed attempts before it finally succeeds is fine, because it’s still going to go faster than humans, can be parallelized, etc.

Well, that’s actually a terrible idea when you remember how expensive AI tokens are (all of the improvements in “coding harnesses” in 2025 and 2026 worked this way, the LLMs themselves peaked in early 2025, the harnesses try to define feedback loops like compiler errors, automated tests, analysis scripts, etc., and run operations in loops like this… it can work, pretty well if the guardrails really are robust, at the cost of an enormous amount of LLM inference). But regardless, the real question here is: how much effort would it take to write exhaustive automated tests for modern software (and I mean really exhaustive), and if you can do that, how much work would be left to implement it yourself?

I won’t get too into this here, but the short answer is: there is no such thing as exhaustive tests (especially once GUIs are involved, which the industry has widely decided are “not testable”, certainly not exhaustively) for modern software, so this is all moot. Whatever test suite you have, it definitely has gaps, and your “spray and pray” coding chatbot is going to very effectively find and exploit the gaps in it the same way they can “break out of” sandboxes and hack into other systems (brute force stochastic algorithms with megawatts of GPUs behind them always work this way).

But more importantly, I’ve also noticed the guys who argue this deal with the fact none of the large codebases they want to do this on have tests (or strong compile time guarantees) in the first place by using a chatbot to write all the tests! That makes the whole thing circular and pointless (the tests don’t have tests so you’re just spraying and praying the construction of your guardrails with no guardrails), but the fact writing tons of tests (which aren’t part of production code) is the strategy to make it work is still a concession the quality of the production code is going to tank. You can’t make the chatbot care about quality or architecture (you can try and beg it to care with skill files, but those are prompts, not guardrails), and the whole point of code quality is it’s a variation of code while holding the behavior it produces constant. The tests verify the behavior, not the quality. Installing guardrails in this way is a strategy specifically aimed at producing production code that is correct in terms of behavior as quickly as possible, with no concern whatsoever for its quality.

If you care about quality, you’re either going to have to write the code yourself (that’s literally what writing code means! It means thinking about and deciding what quality code is, and expressing that decision by writing it down), or describe the code you want so exactly (down to design and architectural details) to a chatbot that you’re using AI as an expensive and unreliable keyboard. There is no way to reconcile “I don’t write and don’t even read the code!” with “but the quality of that code is still important!”.

Conclusion

I don’t think people need to be programmers to be valuable as human beings or deserve to be paid high wages. That’s a bigger social problem we have to deal with: the growing class conflict between “blue” and “white” collar workers with an unjustifiable pay gap between them, that really boiled over during the COVID pandemic when most of the blue collar workers were either fired and left to starve while being told to not go outside, or told they’re “essential” and overworked while being exposed to what they were told was a virus so deadly it required shutting down society, and white collar workers sat at home getting food delivered to them and paid more than the people exposing themselves to the virus to be on their laptops. This created a huge amount of resentment that is now being expressed by gleeful excitement that knowledge workers are finally being torn down and humiliated by AI.

I empathize with people who became poser programmers. My intention is not to spread more resentment and ill will. Society puts way too much emphasis on intelligence as the most (only?) important measure of human worth (how fitting that it is now worshipping artificial intelligence) and this predictably encourages people to pretend to be highly intelligent. I have to deal with annoying people at work who make nonsense arguments about my craft and tell me the future of it is babysitting chatbots. But that’s a lot less of a tribulation than what a lot of people are dealing with these days (since the AI Revolution is fake, the economy is in poor shape and people are struggling to make ends meet). It would be absurd for me to call myself a victim of this and quite unhelpful to dress other people down with no attempt to understand their behavior. I can’t imagine having to pose as a programmer as a full time job is anything less than panic inducing, but apparently that’s less unpleasant than the alternative of working a different job.

My point is to commit to the truth. The wider social issues about financial insecurity, inequality and class conflicts are what is driving this, and we need to correctly understand that because degrading the meaning of software development down to the point anyone who doesn’t care about it and would hate to solve logic problems all day can do “it” isn’t going to solve any of those problems. Dismissing quality as a centrally important problem of all production and business is not helping anyone. We all work jobs and earn money so we can spend that money on goods and services. If everyone is phoning it in churning out low effort slop, we all suffer from it. This isn’t a world we should be helping to create.

The clear trend through 2026 is a growing disgust with AI among the public. This is hardly surprising. The experience most people have with AI is: as consumers it’s a gimmicky product that doesn’t really improve their lives, gets shoved into products they buy in unhelpful ways, and degrades the quality of things they buy by turning it into low effort slop, they’re forced to use it at work under threat of termination even if they think it doesn’t help, their bosses think it’s an excuse to compress deadlines and dump even more work on them with no extra pay, the news keeps telling them it’s going to take their job and career away entirely in just a short matter of time, and it’s powered by noisy, polluting and resource guzzling data centers that will ruin their local communities. Was this reaction really that hard to predict?

This is what committing to low quality, phoned in slop work gets you: it makes you a pariah. Don’t do it. Quality is what people want. Quality is what creates passion, which makes people enjoy their work. Quality is what gives a brand a good reputation and customer loyalty. Quality is what gives you long-term job security from a personal reputation of doing good work, even if one particular sweatshop fires you for not helping them churn out slop as fast as possible.

Quality is everything.

The Programmer’s Guide to Hating AI – Part 5: The Absurdity of “Coding Assistants”

Introduction

The virtue of formal texts is that their manipulations, in order to be legitimate, need to satisfy only a few simple rules; they are, when you come to think of it, an amazingly effective tool for ruling out all sorts of nonsense that, when we use our native tongues, are almost impossible to avoid.

E.W. Dijkstra – On the Foolishness of Natural Language Programming

In the previous part I went over the history of “coding is dead” movements and why, on a conceptual level, any attempt to remove or reduce coding from computer software is confused and doomed to fail.

In this part, I want to really dig into what using a “coding assistant”, or delegating the coding part of programming, does or even could really look like, and why it is, too, a confused concept that emerges from the confused base of coding being something that even could be eliminated or reduced from software development. This is, of course, about “AI Programming”, but that is just a specific manifestation of the general idea. Recall that I believe AI is computerized charlatanism, but even if I believed AI was closer to what it promises to be (a “genie in a laptop”), it wouldn’t change the fact that using it to “do the coding part for you” is a nonsensical idea.

Either you are the programmer (software engineer), and then it’s your job to carefully author code, or this software engineering role has been entirely delegated to the genie in the laptop, and then you are not an “AI Programmer”, you’re a product owner in an organization whose engineering department is a bunch of clankers. The latter is exactly what your product owners, managers and especially executives think is either already happening or just a few months away (after AI gets good enough and/or you finish building your robot replacement and then can be fired), but “AI Programmers” obviously don’t think their entire career prospects have gone up in smoke. They think their future is in this new “agentic engineering” role where they are still needed to do the software engineering part, but they just hand the coding part off to a sort of automated script. This is a schizophrenic concept. Sort of like “we can now create general purpose software without code” is “trying to have your cake and eat it too”, this idea of “AI programming” is a self-contradicting “foot both in and out the door” idea. Are you still a software engineer or not?

To be clear, since I believe generative AI is computerized charlatanism, I cannot even seriously entertain the idea that it will ever become a software engineer itself, so I’ve never even been slightly “worried” this is going to happen (what’s to “worry” about anyways, that we’re about to live in Star Trek replicator heaven?). Nothing that the software industry has wasted its time with in 2025 or 2026 even slightly suggests this is happening. The Rube Goldberg machines of “agentic software development” are rather desperate attempts to cancel out the bullsh*tting nature of token transformers and get them to act as some kind of generic scripting language, albeit one where you have to repeatedly explain to (as some people would describe it, beg) it to follow instructions. If you actually look at what programmers are doing here, you’ll see they’re writing tons of automated tests to try to “steer” the “agents” toward producing code that satisfies the requirements. You’ll see graphics illustrate this, e.g.:

Notice what’s the same?

This, amusingly, illustrates that AI literally made no difference. The length of the entire pipeline didn’t change at all, it just shifted the most time spent from writing mostly correct code to begging the chatbot to please write correct code (“context engineering”) and finding all the problems with the code it didn’t write correctly (“testing and verification”, which exists to begin with because there are mistakes in the execution of previous steps). This was probably not the intention of whoever created this graphic, but that makes it even funnier that it accidentally makes that point.

When you look at graphics like this, what you see is not people trying to make software development more efficient or productive, but rather people who work in software development but hate coding doing everything they can to minimize how much of their day-to-day job involves coding (this is very important and the subject of the next part of the series).

This kind of stuff is, indeed, nothing like AI being a genie in a laptop that can just take your request to build a software system and do all the engineering involved to build it. It’s engineers still doing the engineering but adding a bunch of complicated steps to the process.

This isn’t “coding is dead”. It’s still programmers typing instructions into their laptops all day, they’re just typing different instructions in different formats and languages. Coding is not dead, it is different, and so we need to have a conversation that I find very odd no one seems to have been having for the last year: is this new form of code actually better that the old form of code, and why?

Natural Language Is the Worst Choice for Code

What, in broad terms, is the difference between “AI/agentic” programming and “manual” programming? Referring to the “old fashioned” process as “manual” is already misleading, as if there is any less “on hands” process with AI than before. Like I said, programmers are still typing instructions on their keyboards into programs running on their development laptops just like they were before. This is no less “manual” than typing “code” directly was. Automation doesn’t necessarily make things less manual. We can imagine a machine that “automatically” performs a task, but the number of “manual” input steps required to prepare the machine to perform the task is actually greater than the number of “manual” steps needed to perform the task directly. The machine isn’t making it any easier, it’s just adding an unnecessary complication to the process.

The primary, though not only, difference, comes down to the language: “old fashioned” programming is writing instructions in a programming language like C, Java, C#, TypeScript, etc. AI/agentic programming is writing instructions in plain English, in the form of prompts and various additional artifacts that are consumed by coding harnesses that eventually become parts of prompts (AGENTS.md, skill files, spec files, etc.). These all have no structure except the rudimentary formatting provided by the markdown format. Unstructured English is, indeed, very different as a language for describing precise instructions for software than industry programming languages…

…and in every possible way it is worse for this task. In fact plain, unstructured natural language is just about as bad of a choice for writing precise instructions as you could possibly make. It is worse than machine code.

To understand why, you can start by reading the above-quoted piece by Dijkstra, On the Foolishness of Natural Language Programming. Dijkstra wrote this in 1978! So, once again, nothing is new under the sun, and if anyone thinks “we can finally make software by just talking in English!” is a new concept that has not been analyzed to death by computer scientists, they only confirm their ignorance of history.

Following an analogy he presents, imagine if we applied this same reasoning to algebra. Finally we can do algebra without using symbols! No + or =, no vertical stacks separated by bars (fractions), no parentheses, and certainly not letters like x to denote unknown values, instead we just describe equations in plain English! Doesn’t that sound great!?

Uhh… NO!!! No it does not sound great. It sounds downright awful, actually. Algebra would be nearly impossible without the symbols created specifically to efficiently and concisely express algebraic concepts. It’s not like these symbols were forced on us. Humans invented them specifically to avoid the tedium of talking about such things in natural language.

The big problem here is everyone outside the engineering department (who otherwise loves to talk about the technical details of computer programming), and a depressingly high number of people inside the engineering department, have no understanding of why programming languages work the way they do. They think programming languages are some kind of compromise we made with computers to converse in a way that’s kind-of nice for both us and the computer but not ideal for either. So they think finally unlocking the ability to talk to computers (including for the purpose of describing software to them) in our native languages is this big win that we’ve simply not had sufficient technology to achieve until now.

This is completely confused and backward in almost every way.

Parsing natural language is not some cognitively intractable problem that takes black box machine learning “don’t try to work out the algorithm, just tune it to a huge set of precomputed correct answers” techniques to crack. It’s not like computer vision (trying to reduce the construction of 3D scenery from pixels is such a problem, no one’s been able to crack the algorithm and they managed to sidestep this by just tuning a generic input/output function with known correct answers, a.k.a. “deep learning”). Languages have precise, well-defined grammars and dictionaries. This was problem was solved algorithmically, no “AI” required, decades ago. It’s how Microsoft Word was able to flag spelling mistakes in your document since the 80s, and grammatical mistakes since the 90s.

The problem is not syntactical but semantic, and this is not a technology problem, it is a problem with language itself. As I briefly discussed in the last part, natural language does not just express instructions. It expresses declarations about the world, emotions, wishes, predictions, questions, etc., and it supports vagueness, which it must, because thoughts, declarations, predictions, etc. are often vague and we need a way to communicate them faithfully. Natural language does much, much more than provide a way to express precise instructions, and the line between language that provides precise instructions and either provides vague, non-actionable instructions (clarification is required to make it actionable) or no instructions at all (it’s a poem or something) is very blurry and complicated to delineate.

A correctly functioning “compiler” or “interpreter” for natural language would reject anything that is not fully exact and exhaustive instructions as erroneous input, the same way a C compiler rejects a call to a function that doesn’t exist. The point is that we already built compilers that do this! The first major difference between high level programming languages and natural language is that they are highly constrained. The vast majority of valid English sentences are not valid Java statements. Syntactic minutiae like separating tokens by dots instead of spaces are irrelevant. The point is that the grammar of a language like Java is the subset of English that restricts it to exact and exhaustive instructions, rejecting anything else (declarations about the world, questions, exclamations, vague instructions, non-actionable instructions, instructions a computer system would not be able to perform, etc.) as syntactically invalid.

We’ve already done the work to carve out the subset of natural language that is valid for describing computer programs. They’re called programming languages.

Another type of input that a compiler/interpreter needs to reject as invalid input is instructions that violate the stated rules of the software system being built. These rules aren’t part of what needs to be executed by the program itself, they are rather a constraint on what executions the program should do. These rules can be rather sophisticated by themselves and need to, to some degree, be computed, making them a sort of metaprogram that needs to be executed whenever the actual program’s instructions are verified. These rules get intricately intertwined with the program’s actual instructions, so they need to both be referenced in the same documents (you can’t draw the distinction on a file/document level), which requires the distinction between them to be annotated with special syntax throughout the “source” documents. These annotations allow the program’s instructions to be “decorated” with information that is not an instruction per se (not one that should be performed when the program is running) and picked out by a static analysis tool.

The only way to make this type of analysis possible is to annotate the instructions in ways that indicate certain rules are known at design time. These annotations are added to programming languages to make static analysis (analysis by inspecting the source code instead of executing the instructions therein) possible, specifically a type of static analysis that the programmer can add his own rules to. The primary forms of this are function signatures (which indicate a certain symbol is a function, i.e. something that can be invoked, and usually indicate at least the number of arguments the function can be invoked with) and types, which ultimately determine what syntactically valid statements are semantically valid in the context of a program.

I have met a lot of programmers who think static typing is some kind of verbose burden dumped on programmers to be redundant in the instructions they write in code. Their favorite languages are ones like Ruby, which is explicitly designed to be as close to natural language as possible. This is totally confused. They don’t understand that the extra “fluff” in a language like Java or C# compared to Ruby is exactly why we have “Refactor -> Rename” tools in IDEs that work perfectly with absolutely no errors whatsoever in those languages, while if a comparable tool exists at all for a Ruby codebase, it’s guesswork that can’t formally distinguish calls to a specific method in a specific scope named doX from other callable symbols that happened to be named doX, including local or class scoped variables or an identically named method in another scope. Correspondingly, that refactor tool almost always does the wrong thing, and it is not possible to write a tool that does this operation correctly in Ruby.

Non-programmers and confused programmers will see all this “extra” stuff in code that wouldn’t be there, at least not as repetitively, if you were just talking in plain English, and think this is some kind of defect in such programming languages, or even worse something put in as a concession to make it easier for computers to understand it, at the expense of burdening programmers with more semantically empty “ceremony”. The latter is obviously not true because we have multiple programming languages like Ruby and Bash that don’t have these annotations. So computers being able to interpret such languages isn’t a problem. The requirement for such annotations in other languages is a deliberate design choice for those languages. We choose to make them work that way, for reasons that have nothing to do with helping computers understand them.

In fact, many such aspects of strongly and statically typed programming languages make writing the parser/compiler for them harder. In language design communities, people will often propose features for a programming language that enrich and complicate the rules for its type system or other annotations, that are pitched on the basis that they do something for programmers, they allow them to more robustly express rules that the compiler will then enforce at compile time (thus allowing larger classes of bugs to be rejected at compile time, preventing them from ever getting to even testers, let alone customers), but then get rejected because it’s too difficult to implement them in the compiler! That is, these language features make computers parsing and understanding the language harder. They aren’t compromises that push the language away from human-serving toward computer-serving.

Modern high-level programming languages have incredibly complicated compilers to make them work. These are some of the most complex and cognitively demanding programs that exist, far beyond the capabilities of most programmers (they would not be able to understand at all what the source code for these compilers are doing). We bent over backwards and put all this time and effort into building these compilers in order to serve programmers modern high-level programming languages. They have been designed for half a century specifically to serve the needs of programming, and are excellent at doing so. Anyone trying to avoid programming languages for writing software is like someone trying to avoid a car if they need to travel 30 miles down a road, and talking about how “I just traveled down the road without ever touching a steering wheel!” is some kind of win. What are you guys talking about!? These are the state-of-the-art tools made specifically for this problem!

This is not restricted to programming either, not by a long shot. Lawyers create restricted forms of natural language with which to write legal contracts (“legal jargon”). Every academic discipline invents terminology and often symbology (“academic jargon”) to efficiently and precisely express their ideas. No one talks about getting rid of this, so why are so many people talking about getting rid of programming languages in software?

AI is a Higher Level of Abstraction!

Using natural language to describe software is throwing away 60 years of progress in the fields of computer science, type theory, lambda calculus, formal grammar, and probably others I’m not thinking about. But curiously, AI Programmers claim exactly the opposite: that using AI is somehow just the next iteration in programming languages that moves us further away from machine code, in the same direction that existing programming languages already took us. They imagine a topology like this:

Machine Code -> Assembly -> BASIC/C -> Java/C#/TypeScript -> English

But everything I explained above indicates this makes no sense. There are of course many different programming languages in use today. There are OOP languages like Java/C#/TypeScript, but also Ruby and Python, which have always been more appealing to non-programmers (Python especially became the de facto standard for people who don’t want to get too much into programming to nevertheless write some programs). As I mentioned, the main design goal of Ruby is to be as close to natural language as possible (correspondingly its creator has successfully thwarted every attempt to add static typing to it, to the point it is now the last remaining industry language with no static typing, which PHP, JavaScript via TypeScript, and even Python now all have).

“AI is at a higher level of abstraction” seems to be a buzz phrase that probably originated from AI lab sales engineers marketing chatbots to tech executives. They know programmers talk about “abstraction” as being a good thing, so calling AI “the next level of abstraction” might convince a lot of programmers it’s the future of programming. I say this because I have not detected much real meaning in this phrase. I haven’t seen any concrete examples or elaborations on what this means, exactly. It seems to function primarily as a thought-terminating cliche.

It’s already questionable that OOP languages like Java/C# are at a “higher level of abstraction” than BASIC/C. C already has an essentially unlimited ability to raise the abstraction level. Abstraction means interfaces that express what to do without explaining how to do something. Any programming language that has functions can be used to build abstractions all the way up to the level of business specifications. This is possible in all of these languages, including C. The abstraction ceiling is not the difference between C and Java/C#. The difference is rather in what kind of conversation the programmer can have with the compiler, especially around design time constraints. This has more to do with verification of the program’s correctness, specifically at design (compile) time, than with building layers of abstraction that allow the business specifications to be written directly.

For example, Java/C# has classes that support inheritance, including abstract classes. You can build class hierarchies in C, and you can achieve the same level of conciseness (you don’t have to do it as a design pattern with boilerplate code templates) as long as you are willing to “build” the classes (lay out a struct with a pointer to a vtable that dispatches function calls through it) entirely at runtime and call their methods through strings and variadic parameters. You can support the concept of an abstract class that requires inheritors to override certain functions, and this will be enforced when you call the function to define a subclass. It will check if the base class is abstract, and if so, which functions need to be overridden, and if the subclass overrides them, which if it does not, will trigger an error.

The problem is this is all at runtime. There are performance problems with this (you’re spending CPU cycles and memory constructing all of this every time the program runs, even though it’s the same every time), but more importantly any mistakes, like creating circular class hierarchies, declaring overrides of functions that don’t exist in the base class or that aren’t marked as overridable, not overriding abstract functions, erroneous casting (like “sideways” casting across unrelated hierarchies, which is known statically to fail), or even calling non-existent methods, will all be runtime errors. They will be errors that occur while the program runs (triggering an abort or setting an error code that needs to be checked, etc.) and only when a line of code is actually encountered by the executing program. You built a class system with inheritance that the C compiler doesn’t understand. From its perspective it’s just a bunch of data structures and algorithms. So it can’t help you enforce that you’re following its rules.

If you do this in Java/C# with the tools the language gives you, the compiler does see what you are doing. The compiler understands the class, extends/inherits (or just : in the right position), overrides, virtual/final and abstract keywords. It recognizes those as special keywords with specific meaning, and it is able to check and enforce rules for using them correctly at compile time. If you make a mistake like circular inheritance, overriding something nonvirtual/final, or not overriding all the abstract methods of an abstract class, or casting across unrelated hierarchies, or calling a nonexistent method, the compiler flags it immediately and won’t even let you build your program until you fix it.

This isn’t about a missing ability to build as many abstractions as you want. Different languages have different levels of ability, and different techniques, to build concepts and rules at compile time instead of at runtime. It is the enhancement of the conversation you, the programmer, are able to have with the compiler (the thing that parses the language you’re writing in), that distinguishes different high-level languages (BASIC and C are both high-level) from each other.

And guess what natural language, including the prompts and markdown files AI programmers write, doesn’t have at all! That’s right: compilation, or any kind of static analysis pass that scans it all and detects errors. Even scripting languages do this when you first run them. The JavaScript interpreter will at least scan the entire script file immediately and reject it if there is a syntax error. You don’t even get this with the markdown files. You get no static analysis at all! And you can’t beyond basic “this isn’t even valid English grammar” or “this isn’t a real word”, because what enables static analysis is precisely the stuff that makes programming languages different than natural language. It’s those annoying syntax rules and annotations that enable static analysis that the people excited to never look at “code” again specifically want to get rid of.

So in the above sequence, English really belongs next to machine code. It’s a language with absolutely no static analysis whatsoever beyond basic syntax. Even assemblers will reject assembly that contains an invalid/unrecognized instruction or tries to CALL a nonexistent block. The total lack of static analysis that you just have to YOLO by executing it and hoping for the best is raw machine code (it’s just a bunch of bytes, every byte means something to the CPU so it’s going to do whatever that happens to be).

AI Is a Higher Level of Ambiguity

What I think people are vaguely trying to get at when they say “AI is the next level of abstraction” is this idea that with AI, now programmers can basically just be technical product owners. They can now just describe the business requirements/specifications in their prompts and markdown files, and the AI will act as a “library” that “implements” those requirements, the way programmers used to have to do themselves. This idea completely misconstrues why business requirements in JIRA tickets have never constituted the source code of computer software. It’s not because they’re “too high-level” or “too abstract”.

Plain English is not a higher level of abstraction, it is a higher level of ambiguity

An in the discussions I have witnessed, it is clear that a lot of programmers don’t understand the difference between abstraction and ambiguity, which is very unfortunate. “Abstraction” really is a buzzword a lot of programmers have been trained to blurt out whenever they want to defend something as good.

When you write array.sort() instead of writing all the lines that implement a sorting algorithm, you are not introducing any ambiguity into the program. It is still precise what is going to happen, and what the final state of the array is going to be. It is more abstract to simply say “sort” instead of explain how to sort. It is not ambiguous.

What people call “business requirements”, the acceptance criteria, etc., are almost always highly ambiguous. They do not explain exactly what the software should do. They leave out a lot of details… not implementation details (which product owners usually erroneously call them), but user-facing details that are part of what the software does, not how it does it. Product owners often use “implementation details” to mean “things I don’t care about”, but those are different. “Whatever, you pick something” is not the same as “do this, exactly this, but I don’t care how“.

If you try to put those vague, ambiguous requirements that are missing tons of critical details into source code files and hit the Build button, it will fail, the compiler will reject it as erroneous input, even if you put it in proper syntax for the language. But if you feed this into a chatbot prompt, it won’t say, “bro, there are so many missing details in this, you need to tell me exactly what you want for X, Y, Z, … before I can do this”, it will say, “sure thing, boss. I’m on it!” and then spit out… something, possibly something that you can then build and run.

If you think that is a good thing and encompasses the awesome power of AI, you could not be more wrong! It is not a good thing that chatbots invent missing requirements (and in fact requirements that weren’t missing, it’s just something the chatbot thought you’d like to be added) instead of tell you that requirements are missing and you need to fill them in. Being able to invent requirements if you ask it to is one thing. Inventing them automatically is another thing entirely. And if a chatbot ever takes vague, ambiguous business requirements in plain English and emits computer code from it, it is already guaranteed that it invented requirements not in those prompts because the input was vague, ambiguous and missing details, but the output is a computer program that runs and does something exact and fully detailed. The gap had to be filled in somehow (the way generative AI works is by filling in the gaps with whatever hopefully relevant examples were on the internet somewhere, i.e. filling in all the details for the layout and color template for websites, that aren’t in the prompts, with the default Tailwind black/purple style that every AI generated website uses).

Yes, human programmers can and frequently do this too. They take the vague, ambiguous requirements from product owners and fill in the gaps themselves with whatever they think the missing details should be. That’s almost always not good, and even when it is, it’s something you want a human to reason through, not a procedural generator to randomly grab examples off the internet for. We have put considerable effort into software development processes to catch and prevent this kind of requirements invention as early as possible, and force a feedback loop to bring in the stakeholders to properly address it. This is a large part of what BDD is intended to do: by having the stakeholder, engineer and tester collaborate (like literally be in a room together, it can be a virtual room) on authoring the specification, these missing details are shaken out early on, before any work begins that, if done based on misunderstandings, will lead to churn and waste, and placed properly in the hands of the stakeholder to be the decision maker (who can then delegate it if desired).

Finding problems, not least of which are missing or unclear details, in specifications for software as early as possible is a major part of what the software industry has been discussing for decades, all the way back to the original Royce Paper whose intentionally bad example of how not to run a software DLC was straw manned by Agile Inc. into “waterfall” (something they claim the software industry widely practiced before they showed up and saved the day). This counterexample was presented specifically because it lacked internal feedback loops that would detect mistakes and reverse the flow as soon as they were detected. The lack of such feedbacks meant that mistakes would propagate all the way toward final testing of a completed system, at which point they would be noticed and then they would have to be fixed, which is enormously expensive not just because of all the time wasted building the wrong thing, but because fixing problems like that is much harder in a finished system (the mistaken behavior may have become a “load-bearing column” of the overall architecture that can’t simply be removed or modified without significantly redesigning large parts of the system) than in a design phase.

Either way, even if we wanted to dump the responsibility of being the actual product owner (filling in all these requirements details) onto a chatbot, this has absolutely nothing to do with the chatbot writing code for you. It has nothing to do with prompts and markdown files being a better or more efficient language from programmers to work in. This would mean programmers feed the requirements they get from JIRA tickets into a prompt with the instruction to fill in the gaps and emit a better requirement, which the programmer would then formalize the syntax of to make it code, which should be far less work than explaining it to a chatbot and confirming it did so correctly. If there’s a large gap between requirements and code, the programmers need to build more abstractions.

You Don’t Have to Worry about Design Anymore!

Another idea is that delegating the “coding” takes the burden of “architecture” or “design” (as in code design, not graphic design) off of programmers and lets them “spend more time thinking about the problem”. I have heard ludicrous statements ranging from “now you don’t have to think about the right way to code a behavior” to “now you don’t have to waste time thinking about what to name every variable” in regard to this. I don’t know how people expect to be able to refer to a specific object in a system in the prompts in multiple places except by giving it a name, so I don’t know why they think prompting instead of “coding” somehow avoids the problem of thinking of names for things.

This one makes me the most upset of all, because this notion that architecture/design in code is some irrelevant artifact of programming languages or some other aspect of programming that any kind of “higher abstraction” tool can “unburden” us from is the quintessence of programmer incompetence. Like all of this, this is also not a new concept, and it’s one I’ve been fighting as hard as I can since I realized code design (or code “quality”) is everything a couple of years into my career.

Once again, this is exactly backward. How much “design” is there in machine code, in the sense of choices over how exactly to structure or lay out the code paths while keeping the user facing behavior the same? Well not none. For example, you can choose whether to code something as a loop (a jump instruction back to the start of a repeating section) or unroll it. You can inline sections into copies or write one version as a section that is jumped into and out of. You have to decide what algorithms and data structures to use. But overall… not much. How many books about “design patterns” are there for machine code, or assembly?

No, design or architecture is an aspect of programming that becomes increasingly important as we move away from machine code into high level languages, including from procedural languages like C to OOP languages. Design patterns are mostly associated with OOP, and mocking design patterns as excessive “over-engineering” is mostly aimed at Java. Java programmers are more burdened with how to design type/class systems (choosing composition or inheritance, for example), where to draw abstraction boundaries, how to make parts composable, and how to create only appropriate coupling and avoid inappropriate coupling, which is especially concerned with access scope (public, private, etc.), which are concepts introduced into high level languages that don’t mean anything once the program is compiled and running (from the machine or OS’s perspective, every part of a program has unfettered access to all parts of its memory). Ironically, this is frequently submitted as a major mark against OOP languages by C programmers, who think design patterns are just wasting time overcomplicating programs.

The idea that delegating coding to a chatbot (or anything else for that matter) suddenly makes such concerns not matter is a non sequitur unless you believe all of those concerns existed solely to make programmers reading code happy. This is a popular idea, as if there is something peculiar about humans that make design patterns important. The implication is that code design is some kind of aesthetic or emotional issue, which I will discuss in more detail in the next part of this series. But that is not why they emerged, and (this is the main subject of the Gang of Four “Design Patterns” book) spontaneously (through repeated independent reinvention) converged onto a standard set of ideas and techniques.

The purpose of design patterns in code is to organize and manage complexity.

Modern software is extremely complex, not in its “implementation details” but in its requirements or precise specifications. The ironic thing about claiming “programmers now get to be technical product owners” is (following the same pattern as all of this) that was always what they were! The lead engineers especially have always had the job of taking the vague specifications that only describe working software in people’s imaginations and adding all the details necessary to make it working software in reality. Again, this is not about “implementation details” (like choosing an array or a linked list, although even this has implications for user facing behavior through performance characteristics, which is the whole point of making a choice), it is about user facing details like how exactly a user interface is laid out and functions, what details (visible in the interface and often editable) exist in records and what rules they obey, and so on… things product owners rarely think of, but (at least the ones who actually do their jobs) once the lead engineer points out, they realize is missing details of the specification they need to decide on, or explicitly declare they don’t care about and let the engineer decide.

Here’s the thing that happens once all those precise, tiny details for all the intricate requirements get filled in: they become overwhelmingly complicated. All these specifications became an intractable pile of spaghetti that can’t be effectively incremented on (the key feature of software, which is rapid iteration or incremental modification) unless and until someone uses techniques to design the way those specifications are defined and expressed in order to keep them well organized and the complexity managed through abstraction/encapsulation (keeping complexity hidden from contexts where it isn’t important). This is what “code design” or “architecture” is and has always been about.

The tools to organize and manage that complexity, in ways that get statically analyzed and verified for internal consistency and conformance with constraints of the system being built, are a large part of what high level programming languages are designed to facilitate. When you take all of that away and try to specify software in English and not think about design concerns, you will get quickly overwhelmed with just how intricate and rich in complex features modern software is. If product owners think the well-designed and architected code expressing, exhaustively and precisely, all their requirements, is too much of a headache, just show them what the same expressed as a bunch of unorganized English prose looks like!

I’ve seen this exact problem come up multiple times when doing BDD and requirements analysis on enterprise software. Funny enough, the way product owners (remember that’s what we’re all supposed to be now, right?) deal with the overwhelming complexity of their business requirements is to literally avoid it by never writing it all down anywhere that even claims to be an organized, searchable source of truth for the software. Instead, most software these days is completely undocumented (except for the code itself), with the closest thing coming to an official ledger for its specifications being an unorganized history of JIRA tickets that would have to be collected and merged in order (since an older ticket can be superseded or even invalidated by a newer one) to be able to know what is the software supposed to do as of right now? By avoiding ever trying to build the official repository of requirements at all, product owners get to tell themselves that repository, if it were to exist, would be an easy read totally within their capabilities.

And then someone like me comes in and starts pushing them to actually do this by practicing BDD and requirements analysis, and almost every time, the reaction from product owners is to revolt against it, and specifically claim after taking one look at a proper set of specifications for even a small part of a system that this is code and not what they signed up for. In other words, they wan’t nothing to do with the full precise specifications for the product they “own”. I’m talking about Gherkin here, a sequence of plain English steps describing the initial conditions, action and final conditions of a single behavior in a system, no implementation details or algorithms anywhere to be found. That is what makes product owners throw their hands up and insist it’s not their job to worry about details on that level.

But even more interestingly, writing out Gherkin requirements for large systems becomes very tedious and hard to reason through because of the lack of design tools that full-blown programming languages give us. I realized after doing this a few times that “design patterns” are what we invoke to deal with this complexity, and that those product owners revolting against this sort of have a point: this isn’t their wheelhouse, it’s mine (software engineers’). What that means is: software engineers have always been primarily dealing with managing and expressing requirements. Especially in enterprise software where performance or other aspects that are sensitive to “how computers work” are lower in priority than getting all the intricate business logic correct, thinking about the requirements and how to express them in a way that keeps the complexity under control is already what we spend almost all our time doing, and it’s been that way for decades.

“Think about the problem” more? That’s how it’s always been… except for programmers who aren’t skilled in abstraction and design patterns so they really do waste most of their day writing repetitive boilerplate… but AI or some other “coding assistant” isn’t how you fix that, and in fact the last thing you’d ever want to do is hand novice programmers who work that way a tool that lets them generate this high entropy (little information for a lot of characters) code faster.

AI is the Next Compiler!

Somewhat related to the idea that “AI is a higher level of abstraction” that just continues the march from machine code to assembly to C to OOP languages, etc., there is this popular retort that “AI is the next compiler”, which is another way of saying natural language is the next programming language after modern industry languages. I have already addressed why this is completely backward. But comparing the AI coding workflow to a compiler specifically reveals some more major misunderstands of how the programming tools we use work, and why.

Besides working in a different language, what is the major difference between the way AI coders work, and the way “old fashioned” coders work? The answer emerges from the fact code is still the source of truth. The prompts and markdown files are not the official specification for the software system. The prompts are transient (they don’t even, generally, get saved anywhere, they go into a chat session, then that chat session closes and they are gone forever… and saving them wouldn’t be much help anyways) and the markdown files checked into the repo are, as far as the software system itself is concerned, irrelevant fluff. You can change those in any way you want, and it won’t make even a tiny difference to what the software does. If you want to change the software, you still have to modify the source code, which is still checked into the repo. But AI coders don’t write (and unfortunately for the ones suffering the most from AI psychosis, don’t even read) this source code. They only work on these transient and/or non-official documents.

There is no analogy between this and compilers.

There was never a point in history, however briefly, where programmers used compilers to write instructions, in a high-level language, for a modification to make to a software system, that is specified in machine code binaries, that would be executed by the compiler (the program that understands and executes the high-level language instructions) by reading in that machine code, performing the requested modifications to it, then writing it back, and then committing that modified machine code back to the repo. First, this wouldn’t work. The instructions to modify the machine code would have to reference things in the machine code (like variables, blocks of code, etc.), but those things have no representation in the high-level language, so how would they be referenced? Second, it would completely negate the value proposition of using high-level languages to begin with, which is precisely that they make the source of truth for the software system the high-level code.

Compilers shifted the code programmers work on entirely away from machine code to the high-level language. No version of the machine code needs to be maintained at all, because it is derivable from nothing but the high-level source code. The high-level code is not a series of instructions for modifications, it is the software, in its current form. Modifications to the system are made by modifying this code. The diffs from old to new can be reviewed, and tell a comprehensible story about what is being modified. If programmers ever tried to work in a way where they maintained a machine code binary, issued instructions on how to modify it, and didn’t even try to look at how the binary actually got modified and make sense of it (which, if they did, would mean they’d have to reason about machine code), they would lose control of the system they are working on, which might look fine until one day their modification tool stops working, and they realize they have a big pile of machine code no one wrote or has attempted to read or understand and suddenly try to comprehend it.

This would be a disaster that would end a software system abruptly. It would be literally unmaintainable. AI coders know this and defend what they’re doing on the completely baseless claim that AI will just always correctly modify the source code, with 100% reliability. They have no reason to believe this and submit no arguments for why this would be true, it’s just hand-wavy “but AI is AI, and it just keeps getting better!”, so then it must just do everything correctly, every time, or if it doesn’t, it will soon. In the entire lifecycle of a software system (which is supposed to be indefinitely), if AI screws this up just one time and can’t get dig itself out of the hole, guess what they’re going to have to do? They’ll have to send programmers into a giant pile of AI slop source code (which will easily be tens to hundreds of millions of lines, since AI can and does write tons of code really fast) that no one has ever even seen, try to make sense of it and fix problems with it. I can tell you exactly what is going to happen when this finally occurs, which by nature of probability is inevitable even if AI gets it right 99.9% of the time: no programmers will be able to fix it, the software will be literally unfixable, and it will have to be thrown away and restarted. There will be no other choice.

The belief that “AI will just be so good it will always handle it” is also born of ignorance of how generative AI (the transformer architecture) works. Frontier AI models currently have 1 million token context windows. The context window is a critical concept, because the way AI fakes “intelligence” is through its context window. Every single token (word or word fragment) an LLM generates in a reply is generated by feeding the entire conversation you’ve been having with it since opening the chat window (plus all the hidden static prompts the harness is decorating the conversation with) back into the neural net, which does a linear algebra transformation from this “vector” of tokens to the most likely “next token”. If it’s not in the context window, it simply doesn’t exist to the LLM. If you chop off the first half of the conversation from the context, the words the LLM will predict will be the ones that come next in a conversation that started in middle. This is when people notice LLMs acting “drunk”: they unknowingly blew past the context window (it went past 1 million tokens), so the early parts of the conversation (which probably contain critical context about what the conversation is about) get cut off, and the LLM completely “forgets” what it was talking to you about.

The context windows can’t just keep getting bigger, either. That’s a major part of the enormous cost of LLM inference, and it starts to rub up against the fuzzy “resolution” of the training data (which has also already been exhausted, the internet isn’t infinite).

1 million tokens (that’s roughly single words) is already much smaller than a lot of enterprise codebases, which often have more lines (comprised of many tokens) than this. An LLM literally can’t even pretend to “think” about these entire codebases. Humans can’t memorize millions of lines of code, but they do remember the important details. Code harnesses try to do this sort of “context compression” to simulate what humans do, but it’s just more fuzzy vector embedding guesswork. This presents an obvious reason why AI will not “just do this correctly”. It will not just flawlessly be able to make modifications to huge piles of AI slop code because those piles are much much larger than their context windows. They will start doing what programmers who can’t (or at least don’t bother to) be knowledgable in the system will do: just start monkey patching stuff, not realize it broke a bunch of far away things, and get stuck in an endless bug whack-a-mole loop.

And remember… all it takes is one time for AI to get stuck in this loop and be unable to get itself out (it will fix the bug it is pointed at, but cause 3 other critical bugs, and then when it fixes one of those, it will reintroduce the original bug), and your whole “agentically coded” software system is done, period, end of story. This isn’t unique to AI either. This is basically what’s happening, just more slowly, with most enterprise software already. The business is rushing everything, hiring a revolving door of cheap contractors who just shove tons of code into a system (rapidly growing the size to absurd levels, millions to tens of millions of lines for software that shouldn’t need more than a couple hundred thousand) until it gets stuck in a growing backlog of defects, with dedicated “bug bashes” attempting to address it just making it worse (the rushed bug fixes cause even more bugs). Most of them are in a state where only a small set of very highly skilled programmers who are experts in safe refactoring can salvage or work effectively (without making things worse) on these codebases. This is why so many of these companies are trying to rewrite their codebases from scratch, which is even less viable and almost never succeeds.

AI coding is just speedrunning this process of a software system collapsing into unmaintainability.

Now, what if eventually AI coders adopt a workflow that does make AI work like a compiler? That means they would stop checking source code into the repo, and stop writing prompts to make modifications. Instead, they would maintain a growing single prompt to “one shot” the entire software system: feed it into the chatbot, and the chatbot writes all the source code for it from nothing. It contains everything the software needs to do. This prompt gets checked into the repo, and is what gets maintained and modified in pull requests.

Well if that happens, then this prompt will become the extremely complex source of truth that needs to be managed and worked on effectively by humans. It’s definitely going to be much more than 1 million tokens, so the same context window issue is going to arise, and probably much sooner because describing software requirements in English is so verbose.

Then their workflow will be to modify this giant prompt in order to add or alter a feature. At this point, the workflow is identical to what it was before AI was involved, just substituting the source code for the prompt. And then the disaster of the software being specified in unstructured plain English will be fully manifest. Ironically, if any AI programmers attempt to do this (and probably before that, if this goes on long enough), the more clever ones will realize they keep making dumb mistakes in their prompts like typos that fail to convey two things are the same, or accidentally putting instructions in a section intended to describe the shape of data, or adding a parameter to an operation but forgetting to specify it everywhere it is invoked. And then they’ll come up with a brilliant idea: introduce keywords to annotate different parts of the prompt and write a parser that checks for mistakes like that before feeding it into the chatbot.

Congratulations! They just reinvented programming languages and compilers. Eventually one of them will realize that they’ve introduced so much formal structure into their prompt files, all for the purpose of helping them correctly write and modify their prompts, that the entire thing is parseable by a simple non-AI computer program and in fact can be directly turned into machine instructions. The parser that does static analysis is literally a language model, and once you have that, you don’t need large language models for all of natural language anymore, in fact involving one would be quite counterproductive. And at that point, they’ve squeezed the AI out of their development workflow and went full-circle back to what they were all doing in 2022.

Welcome to the Wonderful World of Metaprogramming

More experienced programmers who have done AI programming may object to all of this as irrelevant because they’ve seen AI just knock out tasks that would have taken them enormous effort to do “by hand”. This usually involves large scale refactoring operations. A popular example is translating a codebase from one language/tech stack to another. Chatbots don’t just magically do this perfectly. They claim to, and spit out a pile of code that is definitely not fully valid (and worse yet, in perfect alignment with the computerized charlatan trained to BS you, the ways in which it is not valid can be “cleverly” obscured and evade detection during a quick review, which is the only type of review possible because carefully reviewing a massive change set isn’t much easier than authoring it, especially for such “rote” work), but if you’re lucky, it takes care of a lot of the tedious parts of translating it, and you can then pick it up and fix all the issues with it.

A lot of the positive testimonials to programmers augmenting themselves with AI are some variation of this. They have some task they need to complete on a large codebase that is largely a bunch of mindless tedium (applying some kind of highly patterned change to a lot of code, which is an indication of poorly written high entropy code, but that’s the reality for a lot of enterprise systems), they already did the software engineering work of figuring out what design/architecture they want to get to, and they just want to hand the menial execution off to something else.

So here’s the thing about that. Programmers absolutely should not be wasting their valuable time and talent mindlessly typing repetitive patterned changes. But do they need AI to automate this tedium? Well… no! What they need is the skill of getting a computer to knock out a mindless, repetitive task quickly and flawlessly instead of doing it manually… which is always what computers have been for. You know what skill is called?

Computer Programming!

In other words… when a programmer realizes he needs to execute a loop of repetitive modifications to code (or to generate a lot of repetitive boilerplate code, which like I said, he usually shouldn’t be at all, unless the goal is to get the compiler to enforce a pattern of rules that the language doesn’t support expressing directly), instead of manually typing it all out, he should write a computer program to do that for him. Writing code to write or modify code is a concept nearly as old as programming itself. It’s what assemblers and compilers fundamentally are to begin with. And approaching programming tasks this way, with a mindset of reflexively applying the programming skill back on programming itself, is extremely under-appreciated and undernourished in the industry. I didn’t start doing metaprogramming until around 12 years or so into my professional career. I had thought about it for years but kept dismissing it as “too hard” or “not worth the trouble”, until I actually tried it out, and couldn’t help but laugh once I realized how much time I had wasted up until then.

The specific example where I did this was to write a program that takes an OpenAPI spec of a web service used by all the clients of a software system (mobile, smart TV, etc.) and generates the strongly typed client code to call it. This work of writing the “glue” code for a mobile app to consume the web service by hand constituted probably 30% or more of my time in the years I did mobile app development, and this wasn’t peculiar to me. It’s just how it’s done. But I had some downtime on a project and decided it would be an interesting experiment to try to hand this off to a utility program. The OpenAPI spec was available in YAML format, so I need to write a program that parses YAML, then loops through the structures describing the endpoints and shapes of request bodies and responses, and generate source code (Swift in this example) from it. How long did it take me to write this program and get it to fully generate working client code?

One day. One freaking day!

In one day, I accomplished what the rest of the client developers had to repeatedly spend a significant part of their effort on doing themselves (since the project was early on and the web service was still very volatile and incomplete) for the entire project. Every time I needed to implement a feature that needed a part of the web service newer than the last time I hit the “generate” button, I just hit it again, and in a couple seconds I had all the code I needed to call the service.

Roughly in parallel with this, I had also encountered a few cases of needing to translate an app from one language/stack to another. The first time I ever did that, I did it pretty manually. But this, more than anything else, forced me to start learning more about regular expressions (regex), which almost every IDE supports as a way to issue patterned find-replace operations. The next time I had to do this, I had reduced most of the tedious part to firing off a sequence of standard regex find-replace commands (to, for example, convert variable declarations in the form of Type name to name: Type, or replace function declarations of the form ReturnType functionName(...) with function functionName(...) -> ReturnType, etc.), leaving only the “interesting” parts of substantial differences in platform libraries that shouldn’t be handed off to a mindless algorithm for me to attend to.

Metaprogramming is a wonderful thing, especially when working on big, messy legacy codebases. The extent of what you can accomplish with it depends only on how seriously you want to invest in tooling for it (some tech stacks like .NET, which comes with a lossless parse tree tool, a part of the compiler Roslyn, to analyze and modify code in structured format, already have some). If you can parse source code into syntax trees and render it back to source code (what the aformentioned .NET tool does), it’s surprisingly easy to execute very sophisticated refactoring or patterned modification operations. Taking data in various formats (web service specs, database schemas, data structures in e.g. JSON, etc.) and rendering patterned code from it is quite simple (it’s just emitting lines of interpolated strings) and extremely powerful. Again, I’m surprised programmers (including me) don’t do this more. It’s probably downstream from software companies aggressively dissuading any amount of investment into tooling or maintenance and instead shouting at programmers to build the next feature right now.

Whatever you can accomplish with AI in this regard, you can accomplish it with traditional code and have it be much more reliable and cheaper. You will be able to precisely control what it does, it won’t fool you with convincing but subtly wrong outputs or randomly go off script and start doing things you don’t want, and you don’t have to write a check to Dario every time you execute it. The reason why programmers get impressed with AI in this area is because their own skills in that area are quite underdeveloped. They would be much better served developing those skills further than just telling a chatbot to do it and hoping it works out.

This is also true of scripting. There are various tedious little tasks programmers have to do routinely that aren’t writing software. Some programmers will tell you handing that stuff off to AI is a good way to utilize it. Sure, that makes a lot more sense than “agentic engineering” where you bend over backwards to create code without ever thinking about, writing or looking at code, but once again, scripting is just another programming skill.

Software Factory!?

The Final Boss of all the confused nonsense emerging out of the big rush to shove a chatbot into programming in a quest to “automate as much as possible” is the idea of a “dark factory” for software. It’s a fully autonomous system you just feed requirements into and software comes out the other end like a conveyer belt. I can attest from direct experience that software companies are spending significant time and money trying to build something like this. Like I said at the beginning, the intention the non-technical parts of the companies have in this is, once the factory is operational, to fire either the entire engineering department, or all but a skeleton crew to occasionally tighten screws on the factory as needed. I don’t know what the programmers working on this think is supposed to happen.

But the point is putting the two words “software” and “factory” next to each other succinctly captures how completely confused people have gotten about these concepts. Those two words are almost polar opposites, standing in complete contradiction to each other.

A factory is something that takes a blueprint and just churns out identical copies of the real thing the blueprint describes. For example, a factory might take a blueprint for a car engine, and produce engines according to that blueprint repeatedly. A factory operation is literally a loop, and in fact is built very similar to how computers (specifically CPUs) work: a pipeline that stages the operations, where each stage repeatedly loops on its specific job, taking inputs from the previous stage (or the blueprint if it’s the first stage) and producing the inputs for the next stage (or the output if it’s the final stage), which is exactly how CPUs loop over instructions of a program and execute them in stages.

What is “software”? It is literally a blueprint! It is a blueprint for what a computer should do. What would it mean for a “factory” to create software, or blueprints? It’s quite simple. We all have “software factories” at our finger tips. Here, do this: go find an .exe or .app or whatever file on your computer (whatever an application or program file type for your operating system), hit Ctrl+C and then Ctrl+V (or Cmd+C then Cmd+V). What just happened? There’s a copy of the file for the program. So now there are two copies of the app! You just manufactured a computer program from a blueprint!

Yes, a “software factory”, if it means anything at all, means copying and pasting.

But that’s obviously not what people have in mind. They think a “software factory” takes a… blueprint… for what, exactly? And then it… produces something repeatedly in a loop. That thing it produces isn’t a particular (already existing) computer program, it’s a new computer program, a .exe or .app that didn’t exist at all before the factory ran. And on every loop it produces new computer programs, each one being new and unique, just like each engine the car engine factory produces is a new and unique engine that can be put into a car.

But… every engine is exactly the same. That’s the whole point! That’s why the factory can run in a loop: because each iteration of its operation produces something identical. Each engine that it produces is “new” and “unique” in a physical sense, which is why it’s useful. It is, literally, implementing Ctrl+C -> Ctrl+V but for a physical thing like an engine. If I have two cars, I need two engines. If I have one, I can’t simultaneously put it in both of my cars. I would need to copy it, which means to take a blueprint or specification for the engine I already have and use it to drive a manufacturing process that produces another actual engine. With physical things, “factories” looping over this operation of producing identical real physical copies of an abstract concept is useful.

But a “software factory” is more like a factory that produces… engine blueprints? So it doesn’t churn out actual engines in a loop, it churns out pieces of paper (or USB sticks, or just saves a new file to a network drive or something?) containing the design for an engine. But if it’s a loop, it’s repeating, which means it’s producing the exact same design every time. So… it’s a file copy operation! Yeah, we already have that, and it works for all files ever (files are just bytes and computers can already copy bytes). The idea that each iteration produces a different design, a novel design for a new engine, like… on iteration 1 it produces the design for the next year’s sedan inline 4 cylinder engine, on iteration 2 it produces the design for the next year’s sedan high trim V6 engine, on iteration 3 it produces the design for the light truck V6 engine, on iteration 4 it produces the design for the medium truck diesel engine… this completely contradicts what a factory is, because it’s not a loop. It’s producing something completely different each time. Nothing is being “repeated” here.

And what would be the blueprint you feed into this “factory”? A blueprint for… making all the engines conceivable? Or… making an unspecified engine? But then you’d had to specify which engine you want, and then you’re feeding a series of specifications into the “factory”, and what would those specifications be except the blueprints for the engines? In other words, what do people imagine being fed into this “factory” on each iteration other than precisely what they want to come out of the “factory” on each iteration? And in that case, what is this “factory” doing (passing through a design document from one place to another)? You have to already design the blueprint to feed it in, so the factory certainly isn’t “building” the blueprint for you.

What do people imagine feeding this “software factory”? The answer is requirements for a specific software system, right? Well as I’ve been harping on this whole time, that’s the software! If you’ve done all the work to fully specify the system, then you already did all the work you’re expecting this “factory” to do. And again… what is the “blueprint” that drives this factory? A blueprint for… all software, ever? Well that’s called a computer (a general purpose mechanical device that can execute a set of instructions in a sequence, which means it can execute any computer program fed into it). But we’re not talking about hardware factories, so… there’s just nothing here. “Software factory” is an empty concept. “Factory” implies a repetitive loop turning a blueprint into identical real copies of a thing, and “software” is unique blueprints for instructing a computer to do something (which it can do as many times as you want, you can double click an .exe repeatedly).

The fact people ever started talking about “software factories” makes it blatant this is all just tech babble nonsense by software company executives and product people having fever dreams about making “all the money” while doing essentially nothing. It’s gone completely off the rails and we shouldn’t be indulging this (which we’re doing because a few AI labs full of weird cultists who think GPUs have feelings if they process natural language have a lot of money right now).

Conclusion

Programmers delegating “coding” to something else, whether it’s a chatbot, another type of computer program, another person, etc. is confused because “coding” means precisely instructing a computer to do something. You’re still doing that, but with unnecessary, unreliable and expensive extra steps crammed in. It’s really just throwing away the more than half-century of foundation we’ve built up for how to do that most effectively. There’s a reason we code in programming languages, not English.

In the final part of this series, I will discuss the issue of coders who hate coding and make it their mission in life to work as a professional “programmer” but do as little programming as they possibly can, which is a large part of why this has gone as far as it has.

The Programmer’s Guide to Hating AI – Part 4: A Brief History of “Coding Is Dead”

Introduction

Those who do not know history are doomed to repeat it.

In the previous parts of this series I have been addressing AI itself. Now I am going to start talking about how it has been targeting my field of software engineering. None of this is new. This is not the first time “coding is dead”, or even the first time AI in particular was going to kill coding.

An excellent review of this cycle of history is here. I encourage you to read this, it covers the timeline better than I ever could. What I want to do is highlight the most pertinent parts of the timeline, and give a somewhat different perspective on why this cycle keeps repeating, and especially why it keeps not working out the way it is supposed to. If you have read the previous parts of this series, you will know I do not agree with him that AI provides any significant productivity improvement to programmers or that it is a tool similar to high-level programming languages.

In that article the author discusses the issue of fixating on tools, which misunderstands what programming is really about: understanding. He also says that typing code has never been the “hard part” (or bottleneck), it is working out exactly what software is supposed to do, which is enormously complex, and becomes more complex the more tools emerge that simplify or abstract away low-level programming tasks. This is another manifestation of the Jevons Paradox: any tool that makes coding easier doesn’t shift the job of programmers down to a less cognitively demanding one, it shifts the complexity of computer programs up until the cognitive demand is back to what it originally was.

The point about fixating on tools is one that cannot be overstated. I have lost multiple job opportunities because the hiring manager believed I did not have enough years of experience in a specific language, framework or platform, despite the fact that my overall experience, both in programming in general and even in the relevant more specific domains (like frontend or mobile app development) were more than twice the job requirement (they missed a huge opportunity not hiring me). Almost every manager I have worked with believes my “skill set” is one of these things (a language like C#, Swift, etc., a framework like .NET, Ruby on Rails, etc., a platform like iOS, Windows, etc.), which is ironic because multiple such managers did not realize (due to the way I came into a job, such as through referral) my experience with the relevant tools was almost nonexistent.

It is from this misunderstanding of programming, which is analogous to viewing carpenters as having skills in “hammers” or “drills”, or novelists as having skills in word processors, or mathematicians having skills in drawing symbols, that people are now saying absurdities like that a programmer’s skills are now suddenly “obsolete”, because he will now use AI as his primary tool instead of those other things. Even if programmers shift entirely from programming with e.g. Visual Studio and C# to Cursor and prompts/skill files/etc., this is a trivial change to the job. Competently guiding an agent to produce acceptable code requires the exact same skill sets that programmers already had (or did not have), which are primarily about breaking high-level operations down into precise parts, ultimately down to algorithms, and managing the resulting very cognitively demanding complexity of all the required precise specifications. Programmers are the authors and maintainers of very elaborate, exhaustive and exact blueprints for information processing systems. Nothing has changed in this regard, even if we fully accept (which, remember, as I will get into, I do not) that AI is now the best tool available for programmers to perform this work.

He also specifically mentions that this is now the third time humanity finally figured out AI, it’s going to revolutionize everything, but first it’s going to eliminate computer programming. That happened in the mid 1960s, and then again in the mid 1980s. Well, the AI research community told everyone that’s what happened. What actually happened was that the thing people called AI that actually existed wasn’t anything like what AI researchers were promising, the false promises first hoodwinked a lot of people and then, once they realized they had been taken for a ride, they turned against not just the AI they had at the time but AI as a concept, and what followed was AI Winter: a large dry-up of public interest and funding for AI research. The author seems to suggest this time is different for AI. I don’t agree. I think the only thing different this time is the scale and sophistication of the magic trick, which only means when everyone turns on it this time (and especially after the enormous malinvestment into GPU supercomputers causes major economic damage), the winter that follows will be much more severe.

But the author of that piece does not dig into what I think is the most important part of why these promises to “eliminate coding” never worked out, which when we address, also reveals why AI is not an appropriate tool for code authorship at all, all the reasons given for why it is being based on gross misunderstandings of programming and programming tools.

The Original “Coding Is Dead”: COBOL

As stated in the article, “the story begins” with the first promise made to businesses that their businesspeople could now handle the creation and maintenance of their software directly, instead of hiring programmers to do this, thanks to a new tool created to enable businesspeople to specify software in terms they already understand. This tool was called Common Business-Oriented Language, or COBOL. This was a language based on English that could be understood and executed by computers, allowing the businesspeople to write the software specifications in familiar English terms and eliminate the need for programmers to manually translate those specifications to computer code.

Of course it did no such thing. COBOL didn’t eliminate programmers and allow business managers at banks to write and maintain the computer code for banking systems, it just created a new profession of COBOL programmers. But this should be “obvious” in hindsight. After all, COBOL is a programming language! Since when has creating new programming languages eliminated programmers (as in, the people who read, understand and write documents in programming languages)? The idea that something like COBOL would open up programming to non-programmers seems very strange. Did anyone think Java, or C for that matter, would do this? The problem, which we will discuss thoroughly later, is that people in these discussions have no coherent definition of “code”, or “programming”. This is why they don’t realize why business managers don’t want to touch COBOL with a 10 ft. pole any more than they wanted to touch assembly, or C, or any other computer code.

He goes on to say “COBOL succeeded spectacularly as a programming language”. That, I most emphatically do not agree with. “Success” here is measured only by how widely it was deployed… and even then, it really wasn’t successful. Almost no programmers ever touch COBOL today, and it has been that way for several decades. COBOL is widely used in mission critical parts of modern society, most importantly the banking system, but it is strictly quarantined in those areas, and every business that has to own such codebases has done backflips to minimize how much they have to touch them or expand them to new responsibilities. Banks usually have software systems written in Java or C# that handle all the newer stuff like their web applications and middleware, that call into the “core” COBOL system only to handle the transaction logic that they built decades ago.

The fact that this core of the banking system is still in COBOL is actually an expensive disaster. IBM has to continue manufacturing otherwise grossly obsolete mainframe computers, with old CPU architectures and instruction sets, just to allow these core codebases to continue to run without heavy, and risky, modification. Everyone is so terrified of making any modifications to this code, they don’t even want to update compilers to let it run on newer hardware. The vast majority of professional programmers today are not qualified to touch that code and banks won’t let them. This situation already became a disaster in the 90s, when people realized that code is full of a specific mistake: the Y2K problem (dates being represented as two-digit numbers that rolled over at the century). This required COBOL developers, most of whom had retired (again, most of the actively developed code for banks by this point was something like Java that just called into the COBOL core), to be brought out of retirement just to scramble to fix this problem before it started breaking the banking system.

This all begs the question of why banks didn’t just hire and train programmers in COBOL and build all of their systems, including the newer stuff, in COBOL. Marshalling calls between separate systems written in different languages is a significant architectural complexity added purely as a result of deciding to make the rest of the system separate and in a different language. Why did the industry pay for all this extra complexity, and in the process make maintenance of the COBOL core a niche speciality that requires rare and expensive (and increasingly unavailable as time goes on) talent, instead of just sticking with COBOL all the way?

The answer is precisely because COBOL is not a good programming language. The reason is obvious: it wasn’t made to be a good programming language. It is a programming language designed with the contradictory goal of not being a programming language, but instead being… something else, something that appeals to non-programmers. Programmers were explicitly not the target audience for COBOL, so it is not surprising that programmers don’t like it. Judged on the same basis as other programming languages like C or Java, COBOL is not appealing at all. It failed its promise to make business managers the programmers, and forced programmers to deal with code trying to obscure the fact it is code, which makes it harder to work on. There is a very important lesson in this: trying to replace programmers not only doesn’t work, it causes decades of expensive and difficult problems for any part of the industry that is seduced by the promise.

The Elusive “Fifth-Generation Language”

In the 80s, as programming languages were getting more advanced (object-oriented programming was starting to show up), people noticed that code written in these languages was more abstract, more declarative and less imperative, and read much more like the business specifications for software than exercises for computer science students compared to older code written in, say, C or BASIC. So naturally they imagined that one more round of advancement in programming languages would “raise the abstraction” all the way out of “programming” entirely, and again eliminate the need for a specialized “programmer” profession and instead allow the product owners, who create the specifications, to create the software directly.

The idea was that the move away from imperative and toward declarative programming would finally be “completed”, so that the text documents prescribing a software system were entire built out of constraints or rules without any spelling out of “how” a computer would perform calculations in line with those constraints or rules. The product owners are the ones who write the constraints or rules, so they could just write them directly in some kind of editor program that would generate executable code directly from those specifications.

My first professional job that involved any kind of “programming” used one of these languages: LabVIEW. I was an assistant at one of the laboratories at the physics department of my university, and they needed to add a thermostat to their lab setup. We added the necessary hardware, a thermometer and heater, to the setup, and connected them to the computer. Then I programmed a control loop that would keep the system at a specified target temperature using LabVIEW to describe the feedback loop that takes a difference in actual and desired temperature and calculates how high to set the heater. You do this by literally drawing circuits.

At the time this seemed fine. In retrospect, with 15 years of professional programming under my belt, I think it would have been much simpler to just write this program in C, or maybe Python. But I understand the point: most of the people working in the lab (students of the physics department, usually grad students) had little to no background in computer programming but occasionally needed some simple algorithms like this, but they all took multiple classes in electronic circuits (something every physicist needs to understand) so drawing circuits, and knowing what circuit to draw to implement a simple algorithm, was something they could handle.

These kinds of languages found niche applications like this. What they did not do is make any kind of impact on the software industry. The reason is basically the same as COBOL, just to a larger degree: these are tools explicitly targeting non-programmers, that may allow non-programmers to do some things they otherwise would not be able to do, but certainly did not allow non-programmers to start building advanced or complex computer software. You still need programmers for that, and if you know a programming language, it cannot be more obvious how silly it would be to try to use one of these “non-programming” tools to build software instead of just using a programming language. I mean, I shudder to imagine trying to draw a circuit that would implement even a basic calculator or todo list mobile app in LabVIEW.

The lesson here is that programming languages are by their nature general purpose, while “more abstract” specification tools achieve the higher level of abstraction as a tradeoff with less generality. What makes programming languages so… “programming language-y”, the characteristics everyone is so desperate to get rid of, is precisely their ability to express the requirements of any computer program. What non-programmers don’t like about programming languages aren’t mundane syntax features like braces or parentheses, it’s how complicated it is to spell out exactly how to do things. The only way to relieve people of that burden is to limit the scope of what they are specifying. This is basically what all productivity software is. You could write a C program that renders any word document you can think of… but C is so much more powerful than that, so this is sort of like killing a mosquito with a machine gun. The alternative is to use Microsoft Word. You can’t build an arbitrary computer program in Word, but you can render a word document by just describing the elements to render (text, images, etc.). What makes it easier (much easier in fact, I’m a professional programmer but I don’t want to write my word documents as computer programs) to create word documents is also what makes it impossible to create anything else.

The idea of a “general purpose computer program that lets you build programs” but that isn’t a programming language is “trying to have your cake and eat it too”. It is trying to achieve two contradictory goals simultaneously. In doing so you will either create another programming language (and probably not a great one, like COBOL) or you will create a tool that has a specialized use case but does not target computer software in general.

Visual Programming Languages, WordPress, etc.

The idea of a more abstracted editing tool for making software was also approached from a different angle. Software is almost always a GUI these days (and has been that way since at least the 90s, if not 80s), so a major part of building software is building the GUI. The GUI is designed by designers (graphical artists for computer software, who also work out how the user experience should work, i.e. what buttons do what, what elements to activate to navigate around, etc.). Programmers would build these GUIs in code, and wouldn’t even know what it “looks” like until they compile and run the program. Wouldn’t it be nice if you could build the graphical user interface of a program graphically? And then, since it’s designers who are really the ones building those interfaces, can we just cut the programmer out of this entirely?

This is an interesting one because as a professional programmers who’s worked mostly on frontend GUI systems, I would love it if this could actually be accomplished. I have always been frustrated by the significant overhead/waste of designers using their own software (Photoshop, or more recently something like Figma) to draw the GUI of the system I’m working on, only for me to have to take those drawings and redraw them myself in the programming tools I use (and then at the next demo get yelled at by the designer about how something is off by a pixel or has slightly the wrong color or gradient shape). I won’t talk about the ideas I have about how to do that because that’s a topic for another article. The point is: the software industry really tried to do this for a solid 20 years, it totally failed, and by now they have completely retreated.

This started in the 90s with “what you see is what you get” drag-and-drop GUI editors. NeXTSTEP, which eventually became Mac OS X, had Interface Builder (it was originally an entirely separate application from Project Builder, the code editor, before they were combined into Xcode, which strongly indicated the idea that different professionals would use each one). Microsoft had the “visual” programming languages (Visual Basic and Visual C++), whose respective identically named editing tools were eventually combined into “Visual Studio”. Java had Swing, with various vendors providing graphical editors. Web applications have always been strongly divided between code and GUI descriptions, owing to its history of emerging from simple HTML (the HTML itself is the data describing the GUI, adding code to web pages to turn them into applications required special <script> tags to be added to HTML).

These all got pushed hard in the 2000s and early 2010s, but by the mid-late 2010s, the trend had started to reverse. No one was using them according to their original intent. Designers weren’t opening up Interface Builder or Visual Studio, working on the GUI directly and saving their work back to the code repos. They didn’t want to go anywhere near those “programmer” tools or the code repos, which would have required training in version control systems. Instead, they used their own tools made just for designers (Photoshop, Figma, etc.) and delivered programmers mockups they then had to rebuild in these graphical editors. Programmers gradually got fed up with the graphical editors and started doing this directly in code, which is more expressive, and simpler because there’s no awkward boundary between data files or generated code and the code they had to work on directly anyways.

The tools eventually caught up with this in the late 2010s and early 2020s. For example on mobile, both iOS and Android pivoted to “next generation” reactive UI frameworks modeled after React (SwiftUI on iOS, Jetpack Compose on Android). A key part of this was there is no graphical editor. You always and only build the user interface in code. But you also get a live preview of that user interface in the code editor. This captures the fact the useful part of those graphical editors to programmers was just being able to see what the code produces. Editing the code graphically was just annoying, but seeing the results of code graphically is useful.

With this move, the concession was clear that designers are not going to jump into the tools that produce the artifacts that actually go into the code repo and become part of the software system. They are going to work on their own separate mockups with their own dedicated tools, then hand them off to programmers to rebuild what’s in those mockups in code, which will then be wired up to the rest of the code that makes it a “live” interface instead of a bunch of static images.

The problem, in addition to designers not wanting to use programmer tools or deal with the version control of the code repo, is that the line between “interface” and “code” is blurry and jagged. In these graphical editing tools, there was always a way to wire up an “action” like clicking on a button to a function/method in code. Who would do this, designers or programmers? Designers needed to design and explain the basics of UX, like that clicking a button should expand a menu, or navigate to another page, or trigger a transition within a view to a different layout with a specific animation. The graphical tools supported some, but not all, of this sort of stuff. Also, they directly supported some, but not all, more advanced visual building blocks and effects, like gradients, drop shadows, transparencies, templated widgets (like a mask that would be shaded differently in different instances), etc., but building those directly in the tool meant they would be rendered directly by the program. This might have poor performance, compared to baking these building blocks into an image. This was the concern of programmers, not designers, and the decision would mess up how designers edited their designs.

All of these systems were built with the idea of drawing a line between design and coding, and helping each class of professionals work exclusively on their side to minimize overhead. Other graphical editing tools were created with the idea of completely taking over the work of building an application. A canonical example is WordPress. WordPress is a tool to build web apps, which in its most basic form supports making documents, but also comes with a set of tools, that are expandable through a plugin ecosystem, to implement more sophisticated behaviors that start to get into full blown web applications. How are these plugins made? With PhP code. The idea is that programmers can build the plugins and make them available to designers/product owners, who can then just assemble them as needed into applications. You don’t need programmers to build your applications, your designers/product owners can just assemble them interactively/graphically.

This is essentially the same as “fifth generation languages” as described above, so it worked out the same way and suffers from the same problems, although I think it was a more sensible way to approach it, so the niche WordPress and similar “web site builder” tools settled into is much larger. These tools are fine for a restricted set of common web pages that don’t do anything very sophisticated or unique, and correspondingly they are used widely for such web pages, allowing them to be built by people with no programming background. But as a replacement for web application development in general, they didn’t even slightly penetrate that industry, because as soon as your needs reach the level of needing programmers, those programmers will very much want to avoid such tools and instead use the tools made specifically for web programming (JavaScript/TypeScript, frameworks like React, Vue, etc.). They won’t even want to offload the “basic” stuff to something like WordPress and handle the rest by marshalling back to a web application or custom plugins. That just makes everything harder. If your web site needs code, and once it gets past trivial requirements it will, it’s much easier to just go all in on web programming, and leave those “web site builder” tools in the drawer.

No/Low Code? What About Everything As Code?

The article talks about the No/Low Code era of the 2010s, with all sorts of specialized applications designed to try to offload certain common parts of software systems away from general purpose programming (again we see the same tension between eliminating “code” and generality), but when I read this I couldn’t help think of the exact opposite trends going on around the same time.

A major example is infrastructure as code (IaC). This got big when everything started moving to the “Cloud” with services like AWS, and the infrastructure for backends went from being a simple server or two to complex orchestrations of instances, clusters, and so on, all with their own scaling and resource consumption rules. For a while people would just use the GUI or CLI for AWS to set all of this up and modify it when needed. But this is a big headache. What if you accidentally break something and need to undo a change? What if you want to duplicate an environment in another region, but change certain parameters? What if there are layers of abstraction in how things are configured, like the instances for one web app follow the same pattern as another web app but with certain parts being different?

Ironically we see the same basic principle emerge: when configurations or systems get complicated enough, the tool best suited to express, manage and organize that complexity is code. It becomes desirable and then necessary for the entire exact specification of such a system to be described in text documents that are checked into version control, and expressed in a language fully capable of abstraction, and verified with static analysis tools that detect mistakes in the configuration at design time. So now the preferred approach is not to go in and issue a bunch of terminal commands or take a bunch of GUI actions to manage these environments, but instead write the infrastructure as code.

A similar thing happened with virtual machine configurations, which can cover all the machine dependencies needed to build, test, run or deploy an application. Instead of elaborate plain text onboarding documentation or READMEs for developers who join projects, instructing them on everything they need to download, set up and configure on their laptops to be able to work on a project, as well as similar documentation instructing DevOps on how to set up hosted environments for those same projects to run in, this can all be written as code and code-like configuration in DockerFiles and Docker Compose configurations, which are instructions for how to build a virtual machine from scratch that contains all the necessary setup.

Yet again, on the side of managing software requirements, behavior-driven development (BDD) is a technique focused on turning the specifications originating from product owners into another type of code, written in a programming language called Gherkin, and put into .feature files that are checked into the code repository and become part of the living documentation of the software system and drive the execution of automated tests verifying whether those requirements are currently satisfied. This comes up against the same friction that GUI editing tools always have: getting product owners to install programming IDEs (which is where the best support for writing and maintaining feature files is found) and participate in the development lifecycle of opening pull requests and committing changes to the code repo is like pulling teeth. They don’t want to, but the alternative they do instead is creating a graveyard of unorganized and frequently contradictory JIRA tickets and claiming that’s the “source of truth” for the requirements, written in vague natural language that is missing large details and includes a bunch of irrelevant commentary.

Gherkin also suffers from the same problem COBOL does. It is a programming language designed explicitly to not be a programming language, so it intentionally leaves out anything “programmer-y”, such as variables, types or even just loops. This makes it pretty challenging to express very complex requirements in Gherkin, and forces anyone who tries to invent their own ways of expressing those kinds of constructs. Programmers generally find Gherkin annoying because it’s not very expressive as a programming language, and they have to deal with marshalling between Gherkin and whatever programming language powers automated tests. Product owners often protest working with Gherkin or feature files specifically because it’s “too much like coding”, which many of them explicitly insist is not their job and instead the job of programmers.

So while everyone is out here shouting “coding is finally dead!”, there have been long-running movements to absorb even more of the software industry’s work into the domain of computer programming, including DevOps and even product ownership. If designers learned to code and built their GUI designs in code with modern reactive UI frameworks everything would get a lot simpler and more streamlined. As computer software continues to grow in complexity, there’s a better chance non-programmer roles like product owners and artists will be increasingly forced to become more like programmers than programmers being increasingly forced to be like product owners or artists. Sorry, we’re taking over the world even as you all keep trying to eradicate us!

Honorable Mention: The Turing Complete Programming Language Called “Excel”

A fitting final example to review of the idea that programming can be eliminated from software is good ol’ fashioned spreadsheets. If you didn’t know that Excel spreadsheets are an IDE for making general purpose software, boy do I have some news for you!

Software, generally, is dynamic, it does calculations. That’s what makes it different from just documents. Of course, spreadsheets can do calculations. There’s a whole syntax in Excel for what to put into cells to make them compute values from other cells. People use this all the time. It’s a very useful feature of computerized spreadsheets. It should come as little surprise, if you understand how computation works, that the ability to do basic computations like adding or multiplying enables pretty much any software system, no matter how complex in its requirements, to be built out of nothing but Excel spreadsheets. The only major limitation is that your GUI has to be in the form of spreadsheet cells, but as long as you can make them emit solid colors, then they’re just pixels and nothing is stopping you from building GUIs in Excel (well, except for your sanity, more on that in a moment).

Now, for spreadsheets to be able to implement literally any computer program, the formulae expressible in spreadsheets need to form a Turing complete language. Basic computation isn’t enough, you also need to be able to do loops whose bounds are themselves computed (i.e. “do something X times, where X is itself computed by the program”), which is equivalent to recursion (the ability for a computational operation to call itself). But Excel has long been able to do this, through fixed-point combinators and later LAMBDAs.

This isn’t a completely academic problem. I haven’t seen this myself, but I’ve heard stories from fellow programmers about companies that built incredibly elaborate computation systems, that would be complicated enough if they were computer programs, in Excel spreadsheets, and of course maintaining and modifying them was an absolutely awful experience. Can you write any computational system in Excel? Yes. Would you want to write any computation system in Excel? Hell no! And where’s the line? How complicated does a computational system need to get before the Excel manifestation of it will have a business manager begging to learn Java? Not very complicated at all. There’s a level of complexity where WordPress stops being convenient and starts becoming a headache compared to a TypeScript web application. Similarly, there’s a level of complexity where Excel stops being the “easy” way to do something, and it’s surely at a much lower level.

Why Does “Coding Is Dead” Always Fail?

See, the problem has never been code. To the extent it’s even meaningful to “kill” coding, you very much wouldn’t want to, unless you only want to do some basic arithmetic. If you want to build nontrivial software, you better hope you have code. And if for whatever reason you don’t, someone is quickly going to reinvent it, discovering again everything academic computer scientists and industry programmers worked out nearly a century earlier when they designed the programming languages we already have (a major problem with any kind of “everything from the past is now obsolete” movement is it begins by announcing its refusal to learn anything from the past or stand on the shoulders of giants, it is practically defined by a complete regression of progress that must then be painstakingly relearned).

If it is not obvious to you that everything I have discussed above is completely relevant to, and in fact damning for, the very concept of “AI programming”, then you don’t have a correct mental model for what “AI programming” is to begin with. It is just the latest manifestation of this ill-conceived desire to remove, or even just reduce, the “programming” part from software, while at the same time maintaining the full general purpose nature of software. This is, again, trying to “have your cake and eat it too”. Just like trying to build software by drawing circuits in LabVIEW, assemble widgets in WordPress, or write formulas in Excel spreadsheet cells, is possible and also a terrible idea, imagining AI as some kind of simplification tool that takes care of the “programming” part but lets us “work at a higher level of abstraction” (I’ll talk about this more in the next part of the series, this is a misunderstanding of what “abstraction” is) is running afoul of the same erroneous beliefs about what makes programming difficult, why it is cognitively demanding, what the real bottlenecks are, and why we do it the way we’ve been doing it for decades (using programming languages and the tools around them).

The fact that programmers are now using AI to write code can be properly put in perspective when you remember they also do things like port Doom to run in Excel, or build an NES emulator in Minecraft.

After all, what is the definition of “code”? Originally “code” meant literally the opcodes, which are a set of codes for operations in the instruction set of a CPU (“code” here means a lookup table from numbers to something else, the same way ASCII is a set of “codes” that map numbers to text characters, or health insurance companies have “codes” mapping numbers to certain categories of doctor visits or procedures). In this narrow definition, only literal machine code is “code”. It’s a stretch to even call assembly “code”, and it certainly doesn’t apply to “high level programming languages” (which includes C and BASIC). If we look at a C source file, we don’t see literal “codes”. When we add two variables, we see the “+” symbol. That’s not a “code” for addition, it is the symbol for addition. There’s no lookup mapping a number or something else to an “add” instruction, the source literally says what it’s doing. The same is true of assembly, which deliberately replaces the opcodes with abbreviations of the corresponding instruction.

When we say “computer code”, the term has been generalized to mean something else. Computer scientists meditated a lot on this. What, really, is in common among a binary executable, a C source file, a Bash script, a Python source file, and a Java source file, but distinct from a JPEG image? We consider all those except the last to be “computer code”. But we don’t consider “plain” text documents, images, or even configuration files, to be “code”. Why? What’s the distinction that captures this boundary?

We might think the answer is whether something is “executable” by a computer. Machine code literally is. Those other examples of “code” are executable indirectly because of compilers and/or interpreters. Those things not considered code are not. But this doesn’t really answer the question, because it instead begs the question of why those other things aren’t “executable”. What’s stopping us from writing an “interpreter” for plain text documents, or JPEG images? Do we just need to do that and then suddenly plain text documents and JPEG images are now “code”? Is it even possible to write such an interpreter? If it’s not, is it simply too difficult, or is it actually conceptually impossible?

What even could it mean to “execute” a JPEG, for example? What does a JPEG mean, interpreted as “instructions”? Instructions for what, exactly? Unless the pixels are codes for instructions (meaning the JPEG actually does contain computer code, just “hidden” in an image), this question has no answer. An image is an image, not an instruction, or recipe. The category of computer programs is not a subcategory of images. For plain text documents, the problem is different: some text documents in natural language are instructions, but some are not. What would it mean to “execute” a novel, or a forensic report of a crime scene? Natural language is not just imperative, and when it is declarative (which code can be too), it is not necessarily declaring something desired (which makes it implicitly imperative, or at least interpretable in that way), it is usually declaring something that just is. “The sky is blue”. How do you “execute” that!?

What about “be a Point of Sale system for bakeries”? Is that computer code? It is imperative, after all. But what does it mean to “execute” that? We might think that means do all the things a Point of Sale system for bakeries needs to do. But what are those things? Whatever they are, they are not contained in this request. The problem here is it is too vague. It’s not actually instructing anything specific or concrete. The word “specification” begins with specific. “Be a Point of Sale system for bakeries” is not specific, therefore it is not a specification, so it is not computer code. It is missing details and needs to be fleshed out before it could be. The problem here isn’t that we aren’t spelling out everything explicitly. “Make a double espresso” doesn’t explain how to do that but it is (or at least could be, maybe it’s missing details that coffee aficionados know about) a precise instruction. The word “espresso” contains in its definition (which we can look up) everything needed to know exactly what is being instructed here. The problem is that “be a Point of Sale system for bakeries” does not. The term “Point of Sale system” does not have a definition detailed enough to be an instruction, especially with the “for bakeries” qualifier. At best, we can consider this an instruction to specify what that means, and then the resulting specification would be computer code.

If we pull on this thread enough we will eventually realize that “computer code” is an exact and exhaustive specification for computer software. The reason why machine code, C source files, Bash scripts, etc. all qualify is because they all do this: they describe exactly and thoroughly what we want a computer to do. But this is also true of LabVIEW circuits, WordPress data files, and, wait for it… the prompts and markdown files that get fed into AI. If all these things are “code”, then they can’t possibly kill code! They just change code from one form to another.

And this isn’t a pedantic distinction. “Coding is dead” sounds seductive because “coding is hard”. Getting rid of it sounds like we just eliminated the biggest, hardest part of making software. “Coding is different” doesn’t have the same ring to it, does it? Coding was different when C was introduced, and then again when Java was introduced, and so on. AI programmers like to claim AI is just “the next compiler” or “the next higher abstraction” (which we’ll talk about more later), but some of them still say “coding is dead”. Well, which is it? Is AI the “end of coding” or just “the next programming language”? It can’t be both. Outside of programmers, the product owners, managers, executives, etc. who are so excited to talk about AI being “revolutionary” to programming are all firmly in the “coding is dead” camp, because that’s always what they’ve wanted: to make building software possible without needing “specialized programmers”. If AI merely makes coding different and shifts it to another programming language, their dream is dead.

And if we instead have a discussion about coding being different, we have to assess AI programming in ways no one, not the non-programmers or AI programmers themselves, seem at all willing to do, and usually don’t even realize needs to happen. If coding is now merely different, we have to ask if this difference is an improvement or a degradation. Is the code AI programmers write (accepting that prompts and markdown files are code) better or worse than the code they were writing before? Well, are prompts and markdown files more or less similar to Excel spreadsheets than industry programming languages? And to what extent is the appeal of AI prompts and markdown files precisely that they’re not written in programming languages and don’t “feel” as “code-y”?

Conclusion

“Coding is dead” fails, and will always fail, because it is an ill-formed concept. “Code” just refers to the instructions precise and thorough enough to actually specify a software system. The only way to not have code is therefore to not have software. The form that code takes is a different issue, but the sales pitch of AI programming has never been that it changes code to a different (and hopefully better) form, it is that AI eliminates it. This is the same promise that COBOL, fifth-generation languages, drag-and-drop tools, and so on, have been making for decades. It never works out because there is nothing to work out. Talking about eliminating “code” from software is indicating deep confusion about what “code”, and really what “software”, is to begin with. Thus, every time a group of people announce that they accomplished “killing code”, it becomes clear eventually that they don’t know what they’re talking about, and if they accomplished anything, it has nothing to do with what they’re describing, and therefore unintentional, and therefore almost certainly counterproductive if not outright destructive.

What I think the author of the history piece (which again I think overall is very well-written and reasoned) misses is drawing a sharp distinction between these tools that aimed to reduce or eliminate “code” and the tools that embrace code as the thing computer software is about and instead aimed to improve it and empower (rather than replace) programmers to lean more fully into it. In the former we have things like COBOL, fifth-generation languages, no/low code tools, and all three (so far) generations of AI hype. In the latter we have programming languages designed by programmers or computer scientists with the concepts programmers deal with (precision, composition, abstraction, type safety and other types of static verification, etc.) explicitly in mind: assembly, C, C++, Java, C#, JavaScript, TypeScript, and more on the academic side (and for this you have to get into PhD level math to even follow what’s going on), functional languages like Haskell or OCaml.

Going from machine code to assembly, to C, to Java, etc. is a completely different, if not opposite, progression than what something like COBOL or WordPress was, and AI now is, trying to do. These programming languages are more “complicated” (advocates of one criticize the latter ones precisely of being “too complex”) and require more programmer/computer science type expertise to use effectively on every successive generation (it is a popular misconception that e.g. Java is “simpler” than C just because it, for example, has a garbage collector, but really it shifts complexity from things like memory management to management of the high-level conceptual complexity of requirements, in the form of design patterns, for which C programmers routinely mock the Java community as examples of overengineering or complexity for complexity’s sake. Abstract factory builder strategy mediators are more, not less, complex programming concepts than the memory heap). It is a category error to conflate these two.

In the next part I will continue this analysis into the concept of programmers “delegating” the coding part of their job to some kind of assistant or tool.

The Programmer’s Guide to Hating AI – Part 3: No One Believes in the Revolution

Introduction

In the last part, I went through the evidence, or rather total lack thereof, of any revolutionary productivity boost that AI was supposed to create in the economy. Besides the distractions I mentioned there, a common tactic AI Boosters use to brush the missing ROI aside is to perpetually claim it’s coming any day now. It’s been 6 months away for 3 years.

Of course no amount of empirical data, which by definition is from the past, is going to plainly refute a claim that is perpetually in the future. No empirical data is going to support such a claim either, although the empirical data cited to support that something revolutionary is totally about to happen, just you wait, is this:

If these trends continue… aaaaay!

“The early progress in a new technology was exponential, therefore progress will continue to be exponential all the way up to sci fi magic” is not a serious argument (people have always done this, in the 50s they thought flying cars were a decade away, in the 60s they thought moon colonies were a decade away). Besides, if you agree with me that AI is computerized charlatanism, the only thing continued exponential progress could mean is that the deep fakes generated by AI get exponentially harder to detect as fake, which is only “progress” for the scammers trying to charge money for those deep fakes. Regardless that isn’t happening. The early exponential “improvements” were achieved by simply scaling the size of the model (the number of parameters in the neural net). That stopped working in late 2024. Since then, the modest “improvements” have all been from traditional code “harnesses” surrounding LLMs, which constitute a set of clever text preprocessing, feedback loops and workarounds, which do not progress exponentially, they all have to be individually, carefully thought up, implemented and tested.

But perhaps surprisingly, the most effective way to dismiss all this stuff about “what’s coming soon” is not to try to argue that it is not coming, but to expose that the people who claim it is don’t really believe that. If we inspect their predictions closely, we find incoherent, contradictory claims that do not line up at all with the high-level premise that AI is a revolutionary technology leap, and instead reveal they’re quite anxious about the future not being very bright.

What Do AI Boosters Actually Believe?

By and large, and it brings me no joy to have to say this, AI Boosters are antisocial bullies who spend most of their time taunting people that they’ll be “left behind” (what does that mean? Starve to death? Be sentenced to a lifetime punishment of being a DoorDash driver?) if they don’t “embrace AI”, and patting themselves on the back for embracing it early, which contains within it two critical implications:

  • The future is not one of superabundance but one of scarcity and struggle for survival with a growing divide between people who can “make it” and people who can’t
  • AI is not “just doing the work for you”, it’s creating a new category of complex, highly cognitive work that requires substantial investment of time and resources to “learn”

In other words, the future they actually envision is that the world looks the same as it does today, except in order to earn a paycheck to cover basic necessities, you need to earn a degree (or go to a “boot camp” or something) in this new field called “AI”, and labor for, I’m guessing, around 40 hours/week, applying this skill to get the AI to do stuff. Since the need for this skill suddenly appeared out of nowhere, the older people with already established careers and skills need to all abandon their now obsolete career backgrounds, rush to retrain and reskill in the new field, and thereby barely grab a humble spot for themselves on the new ladder (since they’ll be at 0 years of experience while the AI Boosters already have 1-3 years).

People don’t act in these kinds of toxic ways if they’re really excited about great things to come. People become antisocial bullies when they’re under stress and anxious about the future.

The guys who started playing around with chatbots early on are especially fond of this predictive model, and it’s easy to see why: they have secured a position for themselves at the top of the new hierarchy, which is inherently not open to competition because the only way to have a comparable amount of hands-on experience in the new skill field is to have been an early adopter like they were. They are graciously helping people at least get some scraps by clinging onto the bottom of the ladder, but they are comfortably near the top. They will become part of the new elite or upper class in the AI Future.

If we inspect more closely what individuals believe this progression looks like, we find something even more interesting: everyone has different, contradictory ideas about how AI is going to “disrupt” the economy, but they are all similar in that AI will disrupt all jobs right up to mine, which will be fine.

AI Programmers think “manual coders” (which, we’ll dig into this more later, means people who actually know how software works) are cooked because AI has “solved coding”, but their skillset of building, maintaining and/or instructing the coding agents with software requirements is perfectly safe. AI will never, or at least not any time soon, be able to handle that. AI is so good at coding it can code enterprise SaaS from nothing but JIRA tickets, but AI coding agents can’t write the AGENTS.md or skill files for themselves. Who knows why their capabilities abruptly stop there, or why the markdown files are a harder problem to solve than the production code (well, we do know why, or rather why AI Programmers think so).

Product Owners think programmers in general are cooked, because AI can just take the business requirements, which they are responsible for writing out in detail, and produce working software from them. At most, they need programmers for another few months to build the “dark factory” and then they can all be liquidated (hey, programmers training their replacements before getting fired, where have I heard that before?). But, of course, the job of taking the high-level use case for software and working out all the precise requirements of that software (the job of Product Owners)? That will never be handled by AI. You can’t just say to AI, “build me a Point of Sale system tailored for stores working in this industry” and expect it to figure out all the screens and flows and persistent records that would require! What do you think AI is, intelligent or something!?

Managers think “AI has taken over execution, now orchestration is what’s important”, so instead of them managing a team of humans, they manage a team of agents. The agents do the “gruntwork” (what lots of managers think of their individual contributors) while the manager focuses on what’s really important: orchestrating all those agents to work together. But AI will never be able to do the orchestration. That’s just too complicated for AI. It can easily do all the individual contributor work, but telling an agent to manage and orchestrate 5 agents… that’s a bridge too far for AI, apparently.

Executives think AI is going to replace entire departments, but whatever it is executives do all day (make deck slides, go to a bunch of meetings, watch demos and decide who gets more or less money?), that of course definitely cannot be handled by AI. It’s just too complicated, or maybe it can’t be trusted to hold the purse strings (what? You mean AI isn’t trustworthy!?).

That last part is especially funny because if AI can actually fully automate any of those jobs, it would be the executives. AI is already being used constantly to make PowerPoints, summarize meetings, and review things. You could easily hook all this up to an agent harness that then determines budget allocations to different departments or products, and there’s your fully AI CEO/CTO. And that would save a lot on company payroll, wouldn’t it?

You surely see the pattern, here. Everyone thinks AI is coming for everyone else’s job, which is trouble for them and they better scramble to switch to a different job (which, weirdly enough, would be their job, i.e. AI Programmers think “manual coders” better rush to become AI Programmers, Product Owners think Programmers better rush to become Product Owners, Managers think everyone better rush to become Managers, etc.), but the AI job takeover always abruptly stops at their job. They will be fine, as long as they learn to delegate down to agents instead of subordinate employees. These are all contradictory positions (is AI going to replace Product Owners or not?), but they’re all mutually self-serving.

This is funny because if it is actually true, it means for any particular person, everyone under him is getting eliminated and replaced with a machine, leading to all the people previously employed in those lower positions now competing with him for his position. This means both that he is now working a job at the bottom of the hierarchy, and that job position is now saturated with applicants from all the eliminated lower positions. The way they twist this is weird. This means they are now the individual contributors. If you were a manager or lead before, we called you that because you had people under you. If you replace those people with a computer program, you aren’t still a manager or lead, because you aren’t managing or leading anyone. You are now the individual contributor! A junior programmer doesn’t call himself a “team lead” because he has multiple programs open on his work laptop! In the predictive model held by executives, they become the lowest level individual contributors. Everyone in this society will be an executive running their own little company, leading to massive oversaturation and competition at the level of private businesses.

So… congratulations? In this new world, you are in the lowest rung of the corporate/office ladder with endless competition for your position, which means your pay is going to tank. You are now going to earn the salaries that individual contributors were previously earning. If this actually happened, going back to what I discussed in the last part, the superabundance of products being produced by AI would mean this low salary now pays for luxury, but either way, you’re now at the bottom of the hierarchy, because as you believe, all parts of the hierarchy below you got destroyed.

Of course anxiety over any of this is a clear indication none of these people think any kind of revolutionary productivity increase is coming. If a real AI revolution was coming, unemployment would be the goal. Why would anyone still work when AI does everything for us? If it can do all knowledge work, then we’ll all drive for DoorDash (what’s wrong, are the self-driving cars not going as planned?) or do construction work for 5-10 hours/week and the wages will pay for what we now consider upper-class living standards. Why would anyone be worried about this? Why would anyone be “coping” that their career skills will still be “relevant” (relevant for what? Continuing to work a 40 hour/week desk job when 5-10 hours/week of manual labor you don’t need much training or skills for gets you rich?)?

Because no one actually thinks that’s coming. They think what’s coming is some kind of Elysium style exaggerated cyberpunk dystopia of haves vs. have-nots, and that for some reason learning to babysit chatbots will be the ticket to join the new elite (spoiler alert on that, if anything like this is coming, you’re not invited to the floating city, period, getting certified in chatbot babysitting isn’t going to change that).

The statements and behavior of executives is even more schizophrenic. In SaaS, executives apparently believe AI is so good, either already or it will be in a few months, that it can just produce SaaS from vague use case prompts. Well if that’s true, that means there is no SaaS industry anymore. Obviously this is because everyone has access to chatbots and can just make their own SaaS for no more than the cost of a chatbot subscription (something I keep pointing out is that even this is schizophrenic on its own, if chatbots can be prompted to make SaaS, why can’t they be prompted to just be SaaS? Why ask a chatbot, “make me a Point of Sale software system for my store” instead of just asking the chatbot to ring up your customers?). But if they believed that, they’d be scrambling to get executive jobs in completely different industries and liquidating their SaaS companies. Well, they’re not. They’re shaking their fists at their programmers to “learn AI right now and do it fast” in order to… I don’t know, become a chatbot drop shipper? Do they think their business is going to just vibe code SaaS the same way their clients could do themselves, but then just mark it up and pocket the difference? Whatever it is, they must be the first mover in this brand new industry of, I don’t even know, which is why their individual contributors need to move fast. This is so incoherent I can’t even properly put it in words.

The Resentful Mediocrities

There is another category of AI Boosters who will taunt you about your impending obsolescence beside the anxious status-seeking white collar worker who just wants to keep his cushy high-paying job, and that is a type of person that is much more toxic: the person who has no skills or creativity and is excited to see people who do have skills and creativity get torn down, humiliated and impoverished.

I don’t think it is fair to present the behavior of people like this (who aren’t new and obviously have personal problems) as representative of AI predictions, but the fact people like this seem to have swiftly embraced “AI is gonna change everything” predictions and derived a specific result from doing so illustrates further what AI predictions are really about. The prediction here is really not much different from the other predictions, it’s just emphasized and framed differently.

These guys claim to believe that AI will effortlessly automate all coding, game production, art creation, movie direction, math and science proofs, health diagnoses, and so on, but this will not lead to any kind of increase in broad living standards. We won’t have more basic necessities like food, housing, etc. All this superabundance of creative outputs will do is destroy the livelihood of people who work in creative or intellectual fields. And more than anything, it will rob those people of any ability to claim they provide any value to the world. They will “cope” that the AI can’t replace them, but it can, because it will make better code, better art, better proofs, better diagnoses, etc. than they ever could.

And that will show them. That’s the important part. Those arrogant jerks acting like they’re so smart and creative and skilled and talented or whatever else will see a computer program outdo them in every way, and they’ll get what they deserve for thinking they accomplished anything or made anything of themselves. They’ll be forced to admit they’re now worthless cogs in the machine just like the rest of us. I have been seeing a lot of this on social media lately, and I suspect it is itself the “cope” with the fact AI is not nearly as popular or well-received as it was supposed to be. In fact it appears to be widely despised, and the AI Boosters have given up on pitching their argument for it or even trying to threaten people into accepting it, and retreated to psychoanalyzing the public to explain why their argument didn’t take.

My intention is not to focus on the obviously toxic resentment people who think this way hold toward people they perceive to be more creative, knowledgeable or talented than themselves, but the fact their prediction of AI being so amazing it can wholesale replace human creativity (I mean, that would be pretty incredible, like sci fi fantasy level incredible) leads to nothing except a collapse in the economic value of creativity and an ensuing humiliation of creative professionals. It doesn’t… do anything else. It doesn’t usher us into post-scarcity Star Trek utopia with replicators and holodecks. It isn’t so brilliant that it immediately figures out robotics and manufacturing and takes over manual labor. It only destroys the economic value (that is, scarcity) of human creativity and intellect.

In fact, once it does that, and creative people are out of a job, those creative people are then going to have to go work at McDonald’s or something (as these guys like to put it on social media, “put the fries in the bag”). Okay… so the predictive model of this absolutely magical revolutionary technology appearing is that talented coders, artists, etc. have to work full time menial (what these guys consider inherently humiliating) jobs, presumably for poor wages and therefore also struggle to earn a living. I’m sorry, but that doesn’t sound very revolutionary. It actually just sounds like the schizophrenic ranting of angry, resentful people.

The line between this kind of attitude and the anxious office worker attitude is not a fine one. There is a blurry transition from one to the other. There is a ton of toxic resentment among programmers, where ones who don’t really get all the stuff about code quality, code design or architecture don’t like thinking of themselves as less talented and potentially in over their heads, so they want to tear down the programmers who excel at that stuff. There is a lot of toxic resentment toward programmers in general by product owners, many of whom think programmers are weird, arrogant overpaid glorified data entry clerks. The ostensibly empathic warning to get good at chatbot babysitting before it’s too late can easily be an insincere mockery that your job is now mere chatbot babysitting (so it’s worthless), it’s over for you and you deserve it for thinking you were so “talented” and “important”.

Conclusion

Overall, the emotions behind AI predictions are some combination of anxiety, fear, envy, resentment and a scarcity mindset (I better get mine before it runs out). None of these are good. I have never seen AI predictions come from a place of joy, excitement, optimism, or charity (abundance mindset), even when they are superficially presented as an ultra-optimistic vision of a hi-tech future.

Against this backdrop, the fact everyone seems to have been coached to regurgitate the words, “AI is here to stay” (either as AI boosters or skeptics) is profoundly bizarre. So basically everyone hates this, no one really wants or is excited about the AI Future (except maybe broken people who want to see the world burn and fiddle over it), everyone agrees it’s a dystopia, not utopia, but we all think it’s getting shoved down our throats either way, so we better do what we gotta do to survive it? Did this originate from corporate propaganda? If it was social media influence, who coordinated it? Is this the marketing campaign AI labs decided is their best shot at success?

Regardless, no one actually thinks a positive advancement of human civilization is underway. If we believe anything real is happening at all (which, remember, I don’t, chatbots aren’t automating any jobs, layoffs are just companies failing, and everyone’s been wasting their time with this), we think it is the construction of some kind of hellish hi-tech walled city that excludes most people, or pollution of the internet with so much creatively sterile AI Slop that real creators can’t make money anymore (exactly the opposite of the utopian vision, which was originally that AI would do all the labor and free us to sit around writing poems and painting or whatever all day… actually it’s going to churn out uncannily creepy poems and paintings ad infinitum while we do all the labor).

None of these are coherent or internally consistent predictions anyways, so more than anything it just tells me this is all a mirage. I believe the inconsistent, vague fogginess of AI predictions are directly downstream from the vague fogginess of what AI even is to begin with. If it’s actually “people in computer form”, we’ve just created a new class of sentient beings who are going to need resources, develop their own emotions, interests and hobbies, and not simply follow instructions we give them, which will create a new class conflict, not a productivity revolution. If it’s a tool, well like I keep asking, what tool for what operation specifically? Since no one answers that, everyone invents their own ideas about what the application of AI is, which never really have anything to do with what AI is or how it works (most people, even programmers, have no idea), and the result is what we see: “AI is gonna change everything”, but not literally everything (how many executives are selling off assets because profitable business and money won’t matter soon?), just “lots of things”, and the more you ask about details, the more annoyed the predictors get.

If these guys can’t explain in clear terms what this revolution even is, I don’t think any of us need to bother with believing a revolution is underway, or coming.

In the next part, I’ll start analyzing AI in relation to computer programming specifically.

The Programmer’s Guide to Hating AI – Part 2: There Is No Revolution

Introduction

In the last part, I explained what my position on AI is: it’s not “so good it’s bad”, it’s just bad, because it’s computerized charlatanism. All of that was analysis, the kind of abstract logical-deductive argumentation typical of math, or philosophy. It is, of course, non-empirical. And many will find this unsatisfying, especially if they believe there is already ample empirical evidence refuting my position. If they believe AI has already revolutionized the world, then of course they will dismiss any logical-deductive argument that AI is nothing but a slop generator, for the same reason someone would dismiss a philosophical argument that X cannot exist while he’s holding an X in his hand.

Well I’m here to assure you that there is not only no empirical evidence contradicting my position, the lack of empirical evidence supporting the claim that AI is some kind of technology revolution is, by this point, a deafening silence.

Forget Productivity, Where’s the Product?

For almost a year, or really longer if you listened to the early adopters, people have been claiming absolutely absurd increases in productivity due to using AI. The most common number has been 10x, and it will never not be funny to me that in mid 2026, in light of the… not great way that things have been going, many of them doubled down (or, I guess, decupled down) and boasted 100x productivity boost!

Okay, so let’s put these numbers into perspective. Putting a number on a productivity increase refers to the increase in units of a product. So to say you are 10x as productive is to say you produce 10x as many units of… whatever it is you produce (this can be concrete, like a gallon of milk, or abstract, like a feature in a software system). We can comprehend what this means by considering incomes. What kind of standard of living could someone in the U.S. sustain on a salary of $100k/year in 2022? Depending on who you ask and where he lives, the answers you’ll get will likely be “barely to comfortably middle class”. Not poor by any means, but also not rich or even well off.

What a 10x productivity increase means is that there is 10x as much stuff (products and services to buy) for that same amount of money. That is equivalent to if everything was the same price, but you had 10x as much money to spend. So that means going from a salary of $100k/year to $1 million/year. What kind of standard of living could someone in the U.S. sustain on a salary of $1 million/year in 2022? That is filthy stinking rich. To be clear, this is not net worth. This is yearly income. You’d have a mansion, probably a nice boat if not a yacht… you get the idea. This illustrates the difference that a 10x increase in products makes. It’s the difference between being barely middle class to being ultra-wealthy.

If the economy was 10x more productive now than it was in 2022, that would roughly mean that $100k/year today would get you what $1 million/year got you back then (adjusting for inflation). I can already hear you laughing (and it’s more like half “you’re funny” and half “I hate you”) about that. We’ll talk more about the actual difference between $100k back then and the same in 2026 is, don’t worry.

Now the AI Boosters will protest and insist the 10x productivity boost isn’t broadly across the whole economy. AI hasn’t made everyone 10x more productive. It’s not in “physical space” (not yet! The robot revolution is just a few years behind the AI revolution). It’s just making office or knowledge work 10x more productive. Sure, I understand they’re not claiming the entire economy became 10x more productive. The point of this is just to illustrate what a 10x productivity boost actually means. Suffice to say, it’s not some subtle change you need to squint to see. A 10x productivity boost is enormous.

However, they are claiming software engineering is now broadly 10x more productive (or 100x, lol), and the thing about software is it’s broadly useful! Software powers basically everything now. The roofer isn’t suddenly shooting nails 10x as fast, but the roofing company uses plenty of software to schedule, coordinate, do accounting, etc.. Either that software should be doing 10x as much as it did before, or if it already did everything it conceivably could, it should be doing it at one tenth the old price (that is also hilarious, in the half “haha” half “I hate you” way). An absolutely gargantuan productivity increase in software development would entail a broad increase in productivity across the entire economy.

But what AI Boosters don’t like about this line of questioning isn’t how broadly applicable this claim to a productivity increase is. It is that I am tying the meaning of a productivity increase to an increase in product. And that is because there is one simple question you can ask, and I and many others have been asking on repeat for 9 months, that AI Boosters refuse to answer and insist on distracting away from:

Where’s the product!?

Okay fine, AI has only narrowly revolutionized productivity in knowledge work, or even just software specifically. And maybe not by 10x (although I wouldn’t let them off the hook for that number, they said that number, not guys like me, it’s not a straw man). Even if it’s by 10%, whatever. Show me the 10% increase in software!

Where is it? What is the name of it? What is the new thing it does that it didn’t do before? Or if it isn’t doing anything new, show me a side-by-side screenshot of the subscription price from a year ago, and the significantly lower (even if just by 10%) price today. Can I hear from the customers? Surely someone who uses this significantly better or cheaper software is amazed by it and raving about how something changed in the last year and software is just so much better now!

We all use software, all the time, every day. Does anyone feel this way about software? About apps, or websites, or any of it? Do any you feel like your experience using that stuff today is significantly better than a year ago? Or can you point to a significant reduction in how much money you pay for it? I mean, I can’t even ask this question with a straight face. The consensus seems to be, and I very much agree as a regular user of software myself (especially the more complex software I use for my job), that software just sucks a little more than it did a year ago. Software has been slowly getting worse (buggier, slower, etc.) for a while, so we can’t blame that trend on AI (which actually isn’t the point, remember we’re asking for evidence of a 10x productivity increase), but in the past year it’s gotten worse a little faster. I mean, come on. I noticed a distinct drop in quality in the JetBrains IDEs I use to do programming this year (mostly in the form of egregious freezes, lasting up to several minutes).

Defenders of AI don’t want to talk about this, they want to ramble about how much more productive they think or feel they are at work. They want to talk about their perspective of productivity, as the producer, instead of talking about the users’ (consumers’) perspective of productivity, which is the product. There is only one reasonable answer we can give as to why: because it’s all an illusion. There are all sorts of reasons people can feel more productive at work (including that they just want to defend AI) that aren’t actually being more productive, and some of them specific to programmers (or rather people who decided to start programming careers) I’ll talk about more later. The way to tease the two apart is to look at the product.

They want to focus on the producer’s perspective of productivity because the data on the consumer side is nothing short of a catastrophe for them: there is literally nothing to show for this! An honest assessment of “what increase in products has resulted from AI” turns up literally nothing, except for AI products themselves. Yes, the major difference between life today and life in 2026 is that a lot of people are using ChatGPT and Claude, or whatever white label rebranding of those everyone is shoving into their apps/websites. That’s it! Everyone’s using lots of new AI services, and it’s made absolutely no difference to anything outside of AI services.

The Actual State of the Economy

Instead of everyone basking in endless optimism and luxury from an unprecedented economic boom powered by a revolutionary increase in economic productivity, what is everyone talking about in 2026?

Grocery and gas prices, unemployment and job insecurity, a housing crisis, and labor shortages. Headlines like “A Crisis Bigger Than Covid: American Business Owners Are Barely Getting By” are more in line with the mood of 2026 than any evidence of a productivity revolution. Far from the unbridled optimism that a tech revolution should be powering, everyone is overwhelmed by bills and worried about making ends meet.

The tone deafness of tech bros and executives boasting about how we’re “entering the future” against this backdrop really can’t be overstated. It’s really the latest round of doubling down on gaslighting we’ve all gotten used to since 2020 (a couple of years ago it was “you think things are getting tough but this chart made by this economist says you’re wrong”). I’m right there with everyone else. I make what I thought was good money and while I’m not outright struggling (not anything like other people are), I’ve experienced quite a bit of anxiety over financial security over the last year.

Pretty much all economic growth in the last 3 years has been not from or due to but literally in AI. At some points people did the math to subtract out the data center/GPU part of it and found essentially zero growth. So AI is helping the economy only insofar as it created some jobs for people to make and supply AI. It’s not helping any other part of the economy though. And that’s really funny because AI vendors themselves are losing money faster than any other company in history. It’s really just Nvidia, the shovel salesman of this proverbial gold rush, who’s really making any money off of this.

This “AI Revolution” that’s going on can’t even pull the economy out of recession, much less blast it into some kind of hypergrowth. At this point, what does “tech revolution” even mean? Does it mean obnoxious LinkedIn posts about “agentic flows” which is, at best, a novel form of entertainment (I consider it torture)? How is your life any different today than in 2022? My answer to that question is: my bills are harder to pay, the internet is polluted with slop, and my job is more annoying than it’s ever been. And I get the impression a lot of people share that assessment with me.

Progressives will argue that rich a**holes are pocketing all the extra proceeds for themselves. But is that even happening? Do billionaires have 10x as many yachts, or underground bunkers, today as 3 years ago? I don’t see any evidence of this either. The evidence is rather that there is no extra productivity at all.

AI Boosters have been crafting a careful way to evade this conundrum, which I call Schrodinger’s Productivity:

The productivity boost from AI only exists where it cannot be observed or measured

Did it make operating systems better, or widely used apps or SaaS? No, that would be observable. But it totally means all these non-programmers can vibe code little internal tools for a company.

You’re a strange fellow, but I must say… you vibe a good app.

Where’s the Disconnect?

What we are witnessing is the producer side blabbing about how amazing AI is (to the point of becoming a meme) while the consumer side either doesn’t notice anything or is sick of having to dodge AI Slop constantly. How do we reconcile this? That is… what the producers actually measuring that makes them think they’ve unlocked a giant productivity boost?

I don’t know how this works in general, but for software specifically, the answer is quite simple, and it couldn’t be more disappointing to me:

Lines of code per unit time

I have to clarify that I am not even slightly kidding or exaggerating, but I have watched town halls with deck slides boasting that coding is dead and agentic engineering is the future of software, and justifying it with ChatGPT wrote 1 million lines of code in a day.

To reiterate… yes really.

Most of the time it is a bit more sober than this. It’s usually something more like the claim I discussed above, i.e. “AI can write 10x as many lines of code per day that a human can”.

Well, that’s not true (give me 10 minutes and I can write a script that will write as many lines of code as the development laptop can store on its hard drive, which will be at least in the billions), but even if it was, so what?

When I said this is “disappointing”, what I mean is I thought we were done with this conversation 8 years ago. I thought the software industry already successfully killed “lines of code” as a metric of value. It’s quite ironic that the same people who say “the code doesn’t matter” also think the value produced in a day can be captured by the quantity of code generated.

This is like measuring the productivity of a construction team by the number of nails they use per hour. This is not a value metric, it is a cost metric. In fact, you might as well measure the productivity of a team by how much money they spend!

The utter disconnect between productivity and AI usage led tech executives with terminal AI psychosis to redefine productivity to mean AI usage. The laziest (but most dedicated) form of this is tokenmaxxing, as in creating token usage leadership boards that literally measure employee productivity by AI tokens consumed. There were also forms at least claimed to be more sophisticated, like Shopify evaluating employees by how “creatively and efficiently” they shove a chatbot into whatever they do. Hey, that was almost a year ago, let’s check how it’s going! Oh, lol.

Most corporations have backed off of this by now, but not because the CEOs or CTOs regained any semblance of sense, it’s because the CFO finally saw the bill to Anthropic (which had switched all enterprise customers to token based billing) after the first quarter and immediately beat down the CEO/CTO’s door with a baseball bat in hand (I mean really, telling a bunch of computer programmers their bonuses will be allocated by how much they can consume an expensive web service was exceedingly foolish). They are still regularly threatening their employees with baking AI usage in one way or another into their performance evaluations.

The main point of this is that AI usage is not baked into deliverables, which was already the key performance metric… you know, the metric where you do your job? There is no correlation whatsoever with how much employees use AI and how much measurable value they actually produce for their employer. But AI executives are some of the main targets (especially by Anthropic) of a malicious “fear, uncertainty and doubt” marketing campaign tailored to make them anxious their company will fall behind if their employees don’t unlock that elusive 10x multiplier, which requires shoving a chatbot into everything, throwing every little problem at it, and trying repeatedly over and over to see if it helps with anything (very much how a casino keeps people dishing out money on the promise that eventually they’ll win a bunch back). The executives are well aware AI hasn’t done much for their company yet, and that scares them because they all mutually think all the other companies unlocked the secret and they’re the only ones trailing up the rear of the race. Some of them are even giving up on trying to “train” or push their current employees to use AI and are hiring vibe coders thinking that’s what they’re missing, that native AI talent!

The AI Hype Grift is entirely built on this “fear of missing out” (FOMO) tactic. No individual corporate leader can publicly start the conversation that leads to the grift collapsing, which would be to say, “guys, we’ve been trying to make this work and it f***ing doesn’t, what are we even doing?”, because then he would be seen as confessing that his company is incompetently losing in the “AI race”. All the other leaders, knowing full well they privately agree with it, wouldn’t be able to admit it, they’d instead say, “wow that sucks, my company is getting all sorts of huge wins!” (executives always have to say this publicly, they can’t be honest about company failures because it spooks investors and customers). It’s like the scene from Archer where Lana tells Cyril she’s going to charge every male coworker to sleep with her for revenge, but she actually meets each coworker individually, takes his money and tells him she’s not sleeping with him, but he gets to tell everyone else she did, leading to this exchange:

She also made over $20,000!

Furthermore, executives are not actually very happy or excited about AI. Most large companies are not doing well (maybe this doesn’t apply to the really big ones like Microsoft and Google), they’re actually up at night worrying about how to keep the business going, and they all feel like they need a miracle. AI is the miracle. The fact executives dove so hard into it is another illustration of the fact there is no productivity revolution but in fact the opposite, a growing crisis of unproductivity, that executives are praying AI is going to reverse.

This is evident from the slide decks they present internally. I have seen quite a few of these. The narrative they present for why they are “pivoting to AI” or “becoming AI first” or whatever they want to call it is not some kind of super-optimistic “guys, this is so cool, you’re gonna love this and it’s gonna shoot us to the moon!” framing, it is rather “look guys, real talk, things just aren’t working, something needs to change, we either do this new thing or we’re done for”. It’s entirely based on anxiety. They’re either afraid their entire industry is about to be replaced with chatbots wholesale (i.e. SaaSpocalypse, who’s going to buy SaaS when everyone can just vibe code it themselves now?), or they’re acutely aware their current business operations are unsustainable and on the brink of collapse and need some kind of total gamechanger. In other words, they can’t continue running their businesses at the current burn rate, which (especially for software) is mostly payroll (and in that, mostly engineer payroll), so they need a way to keep running the business without paying so many salaries.

Also, large software companies have grossly neglected routine maintenance work on their flagship products for decades, and their codebases are in an advanced state of decay and on the verge of collapse from technical debt. The nontechnical part of the organization (especially the “product” department) wants to just wish away this tech debt. They want a magic reset button that just erases it all, like the last 25 years was just a fever dream. They’ve been trying to build this magic reset button for years in the form of a “greenfield rewrite” (just start over and build a new codebase from scratch). For reasons that deserve their own articles, this never works out (these rewrites usually never go to production and just rot in internal code repos, or even worse become a new separate product to maintain). But now they think AI is that magic button finally arriving in a nice little package with a bow on their front door. Just use AI to rewrite it from scratch, in 6 months!

They don’t really care that data reveals AI isn’t the White Knight in Shining Armor they’ve been wishing for. When you’ve been wandering in the desert for 10 days and on the verge of dying from dehydration, you’re not interested in any evidence that the reflection on the horizon is just a mirage. If there’s a 1% chance it’s an oasis, well then that’s your last hope for survival. It’s either that or you’re dead, so you might as well walk in that direction. Inventing fiat productivity metrics and threatening your employees to “do AI or else” is just like the guy yelling at his legs to keep walking. The leadership level doesn’t think AI is a revolution, they need it to be a revolution and see no purpose (no upside and all downsides) to even entertaining the possibility it isn’t one.

Recession Is Revolution, Actually!

The fact corporations desperately need a revolution that’s turning out to be a plastic toy revolution is why this is going to go on until the bitter end (which likely means the financial collapse of AI vendors, or mass employee burnout that leads to a de facto economy wide strike). The latest I’ve heard is that the disconnect between what executives need AI to be capable of and what it actually is capable of is concentrating at the individual contributor level in the form of death marches, which means employees working 12-16 hour/days, 7 days/week (on salaries, so not getting a single penny extra for it) killing themselves trying to fulfill deadlines that are just comical even compared to the deadlines leaders were inventing out of thin air 4 years ago.

They’re putting up with this because they’re terrified of being fired for either not “embracing AI” (like these companies are all cults now) or for just not “holding it right” (they’re not getting the 10x boost out of it so they must be dumb and not getting it), and they keep hearing the job market is a clown show, ironically enough because both the job listing and application sides have been DDOS’d by AI Slop. Plus, people are getting laid off, so holding onto a job at all is “lucky” right now.

Guys, I don’t know, everyone being overworked with no extra pay desperately trying to keep their current job while we hear about mass layoffs, downsizing and a job market oversaturated with applicants… that doesn’t sound like a productivity revolution to me, it actually sounds like a f***ing recession! Like, to a tee. This is how people described 2008, or 1930 for that matter.

I see no more fitting way to wrap up this part of the series than by sharing how AI Boosters spin this:

Multiple simultaneous frank recession indicators are actually proof AI is revolutionary!

See, the reason why lots of people are getting laid off, people are desperate to hold the jobs they have and getting effectively much lower hourly rates due to unpaid overtime, companies are downsizing out of desperation to slash their payrolls to stay in the black, and cutting entire classes of basic services (like actual, as in “human”, customer service), is the evidence AI is a revolution!

People are getting laid off because AI is replacing them. People are desperate to hold jobs and working unsustainable hours because they’ve been genuinely obsoleted by AI and just waiting for their current employer to figure that out. Companies aren’t “downsizing”, they’re becoming more efficient! They’re not removing basic services, they’re innovating those services with cutting edge AI!

I hope this is self-evidently ridiculous to everyone reading it, but if you want a satisfactory takedown of this sophistry, I can do that. In short, this is all economically illiterate. More than anything it is an indulgence of a failure to understand the Jevons Paradox. It’s not how supply and demand works.

What does every company do when it’s doing well? It grows (this is a feature of capitalism progressives/socialists are weary of, likening it to cancer). Even if their market is fully saturated and there is no untapped demand for more units of what they sell, they are now able to keep producing those units while 90% of their current employees are totally idle. That means they can reallocate those employees to do something else: take an idea off the shelf and make it into a new product, expand to new regions, expand into an adjacent industry, etc. Why does anyone think a capitalist corporation would respond to a sudden influx of high margin profits by… firing a bunch of people!?

This is exactly the opposite of how it works. Look I’m not trying to argue that corporations are welfare programs for employees. They’re not hiring (or avoiding firing) people out of the goodness of their hearts. Ironically the whole argument of Marxism is that the owners of means of production exploit employees by acting as rent seekers, shaving off a portion of the proceeds of labor for themselves. Employees are, in this way, like quasi-slaves. Why would a slave plantation ever get rid of slaves!? If they suddenly got tractors, they wouldn’t fire slaves, they’d just get their slaves to do lots more work and pocket the extra value generated, wouldn’t they?

The rich a**holes who own large corporations either want to hoard as much wealth as possible, hoard as much power as possible by growing their corporate empires as far and wide as they can, or some combination of both. Which of these goals is served by reducing employee headcount? Employees are people whose value creation they’re skimming off the top (again I’m just taking the Marxist perspective here), so the more of these they have working for them, the more value creation they have to skim off of. Firing employees is just handing them on a silver platter to competing rich a**holes. Why would any of them want to do that?

From a “capitalist” perspective it’s not any different. They don’t think the employer-employee relationship is a zero sum parasitical one, they think it is a mutually beneficial one, where each employee is an opportunity for the employer to make more money. Even in the most cynical view of this, employers view employees as assets, like the fleet of trucks for a delivery company. Why would a company ever toss their perfectly working trucks in the garbage? If they’re going to get rid of you, they’re going to do it by completely using you up, like strip mining the value out of you. That doesn’t involve firing you while you’re perfectly capable of working, it’s more like the above-mentioned death march until you collapse from exhaustion with a permanent disability. Then they’ll drag you out and toss you in the trash. But even that is short-sighted on their part (they can’t get any more value out of you if they do that).

This idea that employees are viewed by employers as a cost is very confused. This doesn’t require us to view leaders of giant corporations as saints, or endorse “trickle down economics” or whatever. It wouldn’t be hard for a corporation to just fire all their employees. Then they don’t have a business. Even in the highly corrupt and broken financialized corporatist system we have now, corporations do the exact opposite. They actually overhire whenever they can just to show investors “look how fast we’re growing!” They will put butts in seats with nothing useful to do just so they can “show growth”. They just need the cash flow to cut the paychecks, and obviously the whole point of the company is get that cash.

Lots of us experience the unpleasant and hostile side of the employer-employee relationship, but that’s not because they’re itching to get rid of us. This is the experience of low paid, so-called “unskilled” workers, the key being they are easily replaceable. If you so much as ask for an extra bathroom break, you are now slightly more annoying to your manager than any one of the 100 applicants begging to get your job, so he’ll toss you aside and hire one of those other guys. This is exactly what layoffs or downsizes, where your position is eliminated, not refilled, are not. Yes your employer can treat you like total garbage if 100 other guys are knocking on the door eager to get your wage and put up with anything. That is literally because it is so easy to refill the job, that is, to hire someone else!

Companies are not excited to lay people off. Downsizing means the company is failing. It means they are unable to do the thing every company wants to do, which is grow like a cancer cell. What’s happening now is that a lot of companies are being forced to downsize because the economy is in a recession but they never want to be honest about this, and they see an opportunity to lie about it: call layoffs “AI innovation”. If AI was really an innovation, sure they’d relieve a bunch of their employees of their former duties, which are now AI automated, but then they’d hold onto those assets and reassign them to something else. And what would they do with the extra profit margins? Yeah, pay bigger bonuses, but that doesn’t cover much of it. Most of that extra money they’re going to reinvest in growing the company, so if anything they’d hire even more people in this scenario.

Guys, stop falling for corporate executive BS: layoffs and downsizes are failure. And there is no corporate executive on this planet who is happy to have to do it. Sure, they’re not worried about you or your family or the awkward conversation where they tell you to get lost. They’re worried about the awkward conversation with the Board and Shareholders where they have to explain why the company is shrinking. They’re deceptively spinning it as “AI innovation” because they’re that unwilling and terrified to tell the truth.

Yes there is a fantasy some executives have about AI letting them rule giant empires without having to deal with obnoxious human beings who have feelings, families, interests outside of work, health issues, and so on. But that’s a sci fi fantasy, it has nothing to do with what’s actually going on right now. What happening right now is the Western (and possibly global) economy is collapsing because it is deeply unsound (mostly due to the way money and banking works), and AI is irrelevant to that (it neither caused nor is it going to stop it).

Conclusion

It has been 3 years now, and 1 year since “coding agents” showed up. The AI Revolution not only didn’t happen, things are just getting worse. I shouldn’t even even have to say that this is incompatible with wild claims about productivity boosts. The way you destroy this narrative is to simply ask for evidence, specifically evidence from the consumer side. Where are all the amazing products? Life is no different today than 2022 except there’s a ton of low effort slop on YouTube, some obnoxious AI “assistant” you didn’t ask for bugs you on a bunch of apps or web sites, everything you actually want is more expensive, and your job is a mix of a soul sucking death march and annoying corporate leaders micromanaging your workflow to an extreme degree.

After all that, it may be surprising to hear that no one actually expected a revolution. What they did expect is what the next part is about.

The Programmer’s Guide to Hating AI – Part 1: What Being Anti-AI Means

Introduction

There has been a lot of “anti-AI” commentary over the last few years, but I have been surprised how much of it is not really that anti-AI. Most of it is either an apology for or flattery of AI disguised as a criticism, or it is irrelevant to AI itself and focuses on something tangential. The common categories of this are:

  • AI is Skynet and it’s going to kill everyone
  • AI is going to automate all office work and cause mass unemployment
  • AI is a great technology but the people in charge of it suck
  • AI data centers are destroying the environment and local communities

I want to make it immediately clear that this series does not fall into any of these categories, which is part of why I felt so compelled to write it (all that stuff is covered pretty well already).

No, my position on AI is rather well summarized by this satirical news video from 15 years ago by the Onion. It hits everything, including “needing to use it to not feel like some toothless hillbilly living in a hillbilly shack somewhere” (or as it’s called these days, being a “Luddite”).

Now, as soon as I say this, I’m sure many of you will immediately react with, “he can’t really believe that, or he’s never used it, it totally does do useful things!”

Yes, I’ve seen it do useful, even quite impressive, things, before too, and I’ve coaxed useful behavior out of it. That’s not what “works” means and I find it incredible this has to be clarified. Sony’s “Stupid Box Thing” surely has all sorts of uses, like: a doorstop, a stepping stool, a blunt weapon to fight off a home invader, something to destroy in a fit of rage like the printer from Office Space, etc. I don’t know if a contraption being absolutely useless in every conceivable way is even possible. Dog poop isn’t useless, it can fertilize grass, or attract flies, if you happen to need that for some reason, and so on.

“Doesn’t work” means it doesn’t do what it’s advertised to do. For AI, this isn’t saying much, because what it’s advertised to do is just plain ridiculous. It’s advertised to do… everything? Depending on the mood of the day, or how far into the same rehashed argument with an AI Booster you are, it’s advertised as being a computer program that reasons through problems (or a “roomful of PhDs”), or failing that, some sort of all purpose tool of automation. I call this the Automatic Thingamatron. It automates things! What things? All the things!

I don’t know why anyone takes such an advertisement seriously, but here we are, and measured against that advertisement, AI is indeed a stupid piece of s*** that doesn’t f***ing work.

But can it be claimed useful against a different metric? That is, can we say it “works” as something that is not what it’s advertised to be? I’m sorry but the fact we’re even going there is ridiculous, but if we’re going to, now we have to clarify: what exactly is it supposed to do, and is it actually worth my time and money? Don’t worry, we’ll get there, but the fact it takes this long in a discussion about what this thing is and why I should care to answer that question is already a very bad sign.

When it comes to programming, “useful” has come to mean erecting convoluted Rube Goldberg machines around AI (“AGENTS.md”, skill files, plan mode, subagent swarms, “loop engineering”, etc. etc.), none of which was in the “just tell the roomful of PhDs what you want!” brochure, that change every few months, all to achieve the result of it hopefully emitting some decent enough code that a modestly skilled coder could have done himself. Every time I hear people describe this, I can’t help but think of this:

“Agentic Coding”

So What Is AI?

All of those arguments I listed above are, as I said, either obfuscated compliments of AI, or concern something besides the tech itself.

“AI is Skynet and going to kill us all” is basically “AI is so good, it’s bad”. This is what most of the people working at AI labs believe, it is accurately labeled the “AI Doomsday Cult”, and it is a well funded and highly astroturfed marketing campaign for AI research (see here, here and here). I’m sure if we hooked up the hallucinating chatbot to our nukes it would kill everyone, but that’s not what these guys mean.

“AI will cause mass unemployment” begins with the premise that AI is so good it can just automate away all knowledge work. That part, which is part of the marketing material from AI labs, is glossed over and then the focus is shifted to how we should handle, regulate, etc. such an awesomely overpowered technological revolution. But I don’t accept the premise that was glossed over.

“AI is great but Sam, Dario and Elon are dirtbags” similarly begins with the premise that AI is great, which it doesn’t really do anything to defend, and then shifts to talking about how the CEOs are dirtbags. Yes they are, but the fact what they’re selling isn’t great makes that true to a degree the people making this argument don’t seem to fully appreciate.

All the stuff about data centers is a real concern and I don’t want one of those things anywhere near where I live. But this discussion skips over what is the freaking point of building those data centers, in the process conceding, however implicitly, that what these data centers do is actually useful, but they just generate too many negative externalities to do it. But if the internalities are all negative too (that is, if the output of AI data centers is just another form of pollution), the case against AI data centers is that much stronger. They generate real, environmental pollution in order to… generate digital pollution? Either way, this just isn’t addressing AI itself.

So what is AI, really? I refer, here, to the “generative AI” that exploded since 2022 (conflating this with all the other things people call AI, like Machine Learning, is a common misdirection so I have to clarify this). Quite simply:

AI is a Silicon Valley Venture Capital Scam

It is an attempt to do the same thing people tried to do with “crypto everything” (web3… does anyone still remember that?) a few years prior. In fact, it is literally the same people who abandoned crypto and switched to AI, a phenomenon termed “The Great Brotation“. Now that the AI grift is starting to show signs of drying up, the next grift they have lined up appears to be quantum computing (or possibly fusion power plants). If your reaction to this is, “but wouldn’t quantum computing/fusion be cool!?”… people have been talking about quantum computers and fusion reactors for 50 years. You perpetually imagining how cool it’s going to be once they crack it “any day now” is how the grift works.

To be more specific, the AI grift is an alliance of two distinct groups of people who are mutually exploiting each other:

  • Silicon Valley VC/Tech Bros looking for the “next iPhone” but, bereft of any real ideas, are content to just sell empty hype or even run outright pyramid schemes and pocket as much as they can in the process
  • AI Doomsday Cultists who believe they urgently need to build “Good AI” and that this requires brute force through massive supercomputers and unprecedented capital expenditures

The first group was seeking any excuse to get investors to give them as much money as possible on the promise of a tech revolution, and the second group believes they need all the money in the world to build God the App, and were able to successfully create a very convincing parlor trick (perfect for a demo in an investor deck) that requires GPU supercomputers to power it, and is supposed to magically “become the real deal” (“wake up and solve physics”) if you just shove enough GPUs in.

It was a match made in heaven (or maybe hell).

Everyone is probably already familiar with Tech Bros and thinks they’re annoying and dangerous. What I think deserves more attention is the AI Doomsday Cult, which calls itself “Rationalism” (no relation whatsoever to the much older philosophy/epistemology school of thought, it’s basically self-serving “we’re smart and reasonable” branding) or “Effective Altruism”, their main hangout is LessWrong.com, that makes up most of the technical staff of AI labs… the people who believe “AI is going to kill us all”. But that’s obviously not the whole story, because aren’t they working at labs building AI?

To square that circle, you have to know about their concept of “Good AI” (which will give us all eternal life in digital heaven), and “Bad AI” which will be so extremely indifferent to us it will “turn us into paperclips” (use us for raw materials). The doomsday scenario is about “Bad AI” being created, which they believe is inevitable (someone will figure out the tech specs and do it) unless someone builds the “Good AI” first… the “Good AI” is the only force that can stop the “Bad AI”. So the only way to stop AI from killing us all is… build AI really fast to save us.

This isn’t some kind of niche within AI departments. All the terminology we’ve been inundated with since 2022, like “singularity”, “alignment”, “AGI”, “ASI” and so on, originated in this cult (“alignment” refers to whether the AI we’re building is the “good” or “bad” one). This is what this community is broadly involved in.

And of course no discussion of this cult is complete without mentioning Roko’s Basilisk, which I encourage you to read and try not to laugh at. This is the kind of stuff I rambled about, drunk and stoned out of my mind, at 2am in college, fully aware the whole time it was entertainment. These guys, presumably dead sober, take it totally seriously.

These are the people building the chatbots. You cannot separate what the chatbots are from the absolutely insane cultish nonsense they emerged out of.

But It’s Just a Tool!

If you bring up this cult and its half-baked beliefs about a GPU data center being “conscious” or whatever, you are likely to get a response that is some variation of, “okay but forget about all that. AI is just a tool! Why are you against using tools!?”

This is an extraordinary backpedal in a conversation about a thing we all keep calling “artificial intelligence”. Oh it’s “just a tool”? “Just a tool” is exactly what “AI” is not. The whole point of it being “AI”, everything about what it’s supposed to be, what it’s supposed to do and what it took to make it work, hinges on it not being an idle, inanimate mechanical contraption that just automates mindless tedium. We already have tools for that stuff. We already have automation for repetitive tedium. The reason AI is supposed to be so exciting is because it breaks through the barrier and finally starts “automating” the cognitive part of work, the part that computers have never been able to help with because they’re just algorithmic automatons that don’t “reason”, “strategize”, “learn”, etc.

And now you’re telling me it’s not any of that, it’s just a tool!? We were sold a robot intern and it turns out it’s just a hammer?

Okay, what tool is it? Please be precise. A tool is made with a specific use case, designed to implement the steps of a repetitive operation. What repetitive task does AI implement? What is its precise function? You can’t answer with “thinks”, “reasons”, “does what a person would do” or anything like that because you already conceded that away. A hammer is made to hammer nails. A drill is made to drill holes. Excel is made to edit spreadsheets. So what tool is AI, what is it made to do, and why are we calling it “AI” instead of just calling it the tool that it is?

See, there’s no answer to this question, because the non-answer you get is back to the Automatic Thingamatron: it’s the everything tool! It wasn’t made for a use case, use cases were made for it! (there’s a subtle confession there that you have an extra task on your plate to figure out how to cram AI into some workflow and get utility out of it). This is what is fundamentally different about AI, and why comparing it to other technologies or saying, “oh well you must be against using Google” is nonsense.

Tools exist to give you more time to use your brain to do the thinking part of a problem, because you’re not spending time on the mindless tedium parts. Thus, calling something that purports to think for you (it’s a subscription to “intelligence”) is basically the opposite. It’s not you being more effective and efficient at completing a task by thinking about it more, it’s fully delegating the task out to something else in order to think about it less, or not at all. There is a difference in kind, not in degree, between a novelist using a typewriter, or a word processor, spell checkers, grammatical checkers, dictionaries, thesauruses, and so on, and using a contraption that claims to write passages of his novel for him. Assuming that contraption even does what it’s advertised to, if he does that, he’s no longer the author, and he’s no longer writing a novel.

These two categories work entirely differently in almost every way. How do I choose when to grab a hammer, or nail gun, or circular saw, or drill? The answer is when, in the process of performing a task, I come to a step or subtask for which that tool is the right one to automate it. I need to cut a 2×4? Grab the circular saw. I need to drill pilot holes for fasteners? Grab the drill. I need to nail two pieces together? Grab the hammer, or a nail gun. How does this work with AI? At what point in a workflow do I reach for AI, and for what purpose, exactly? AI doesn’t have a defined use case because it “does everything”, so all this could look like is that I start off asking AI to just do the whole thing for me, and depending on how badly it screws up (assuming I even check), take over parts of it or maybe try asking it in different ways or giving it more instructions. People don’t even have a mental model for what they’re doing here. They don’t know what AI is or how it works, they just think it “does stuff”, and they can’t explain why it makes sense to even try offloading something to it.

The honest (but ridiculous because it’s pure fiction) framing of this is that AI is exactly that, AI, and that I’m delegating a task entirely to another entity with agency, which is exactly not what augmenting my own performance of the task with tools is. You gotta pick one. It can’t be both. Which of these two things is AI? If it’s the latter, then it’s not AI, it is a specific type of computer program with specific features made to perform specific operations, and we should be able to clarify exactly what those are (which should be derived from what computer program does, i.e. how it works under the hood).

This “just a tool” argument is AI users wanting to have their cake and eat it too. They want to be a novelist asking a computer program to just write a whole passage for them, but still put their name on the byline… except when they’re trying to market the power of AI itself, and then it’s “AI solved that math problem”, not “that math PhD solved that math problem, using AI as one of many tools to do so”. Or, they’re using AI to do spell checking, look up words (be a dictionary) or find similar words (be a thesaurus), which… why!? All of that stuff already exists and you don’t have to pay Sam or Dario for it or pick out the hallucinations.

Claiming “AI is just a tool” seems to always begin by downplaying or dismissing the tools that already exist and were specifically created for whatever task AI is claimed to help with. A good example of this is Sam Altman tweeting “I can’t believe developers used to type code one character at a time”. Well, we didn’t. We have lots of very advanced tools to help us author code. But if we ever compared “AI as a tool for X” to the purpose-built tools made just to do X we already have (or could build once we realize we need to do X repeatedly), we’d start a discussion AI Boosters don’t want to have.

This is why the concrete examples you get of “AI is just a tool” is people using AI to do things you can do without AI. “My AI agent reads my emails, flags some of them as spam and then deletes them!” Oh, you mean the “Junk Email” folder that every email client has had for… 15 years, at least? “My AI agent checks a bunch of flights to a city on a certain date, books the cheapest one and then finds a hotel to book in that city on that date!” Okay, so… Expedia? “I use AI to describe a blood test result and see what it means”. Okay, so… Google search (most uses of AI are actually just as a search engine, more on this later)? This reminds me of a hilarious video by Patrick Boyle about how Tech Bros seem to do little else but reinvent existing products (or simple concepts like lunch breaks) and claim they’re revolutionary.

In programming, a lot of this ends up being programmers discovering scripting/cron jobs and metaprogramming for the first time. They imagine doing some big refactoring operation “by hand”, one line at a time, in comparison to handing it off to AI, but they’re programmers, their skill set is literally “automating repetitive tasks with computers”, so why did they do it that way instead of writing code that does all that code editing?

The more interesting examples are things like “I use AI to summarize emails”, which is actually something a “large language model” would be appropriate for (and, for what it’s worth, I get annoyed when I find out someone won’t bother reading something I sent them but claims they sort-of did because they read an AI summary… all of this seems inexorably aimed at turning people into lazy zombies). But is that it? Is AI actually just a “block of text summarizer” tool? If so, why did we ever refer to it as “AI”, and why are people claiming it’s also a giga-multitool that does endless other things no one who built it even thought of and automate away all office work?

The Technology Behind Generative AI

A common phrase I kept hearing when I found what appeared to be anti-AI content is “the technology isn’t the problem” or, much more suspiciously, “AI is here to stay”. That second one I heard like clockwork, always near the beginning of a video with a title critical of AI, almost like it was a disclaimer. I found this very odd, like the Overton Window about all this was set so that we can make trivial complaints but never, ever dispute that the Magical AI Revolution is coming any day now.

No, the technology is the problem. This idea that “tech is always neutral, it’s how it’s used that matters” is a popular misconception. There are technologies created specifically to be misused (for example, the techniques used by computer viruses to spread themselves without users noticing). They may be assembled out of smaller pieces of technology that, by themselves, have legitimate uses, but the assembly is still malware.

A funny example of this is the auto-dialer from the Simpsons:

However much Professor Frink insists it was made for noble causes, it inevitably just ends up being a tool for scammers.

All we have to do to illustrate that the technology of “generative AI” is inherently a problem is describe in enough detail what that technology is. A good gentle intro to that is here. The technology that powers generative AI is called the “transformer”, and the foundational paper describing it is “Attention Is All You Need“. For chatbots (transformation of text tokens to other text tokens), a transformer memorizes large quantities of human text and conversations (by now basically the entire internet), measures and encodes the statistics of how words appear in sequences (this is called “vector embedding”, referring to how words are expressed as points in a multidimensional space, so that the statistics are encoded as “distances”). It then takes text inputs (prompts) and “completes” them (fills in text that follows the input) with words following the same statistics. The result is a “response” to the input prompt that is reminiscent of the text it originally memorized and encoded.

Okay so once it “clicks” in your mind what I just described (the technical details like vector embedding aren’t really important), it should immediately be clear what these programs are. Memorizing a large set of conversations from people who, presumably (one hopes), understood the words they were saying, in order to be able to produce responses that sound convincingly similar to those conversations and therefore superficially mimic the same understanding, is exactly what an unscrupulous person would do to fake understanding or expertise in a topic on which he has none. For example, someone who wants to get a high paying job that requires a skill needs to pass a technical interview, and if he does not possess that skill, he may instead try to feign expertise by memorizing the replies people who are experts gave to the kinds of questions interviewers ask.

There are several colloquial terms for this behavior, such as bullsh*tting, but we also have a formal word in English for this:

Charlatan (noun):

one making usually showy pretenses to knowledge or ability

So, put simply, generative AI is computerized charlatanism.

When you point out what the technology is to AI Boosters, they will try to fog the discussion with a bunch of pseudo-philosophical gobbledegook about “emergent phenomena” or whatever, implying that while this may be in base terms how generative AI is programmed, once it goes through training (memorizes all the conversations) something else appears spontaneously, namely intelligence, which at least implies that the thing does in fact understand, rather than just mindlessly regurgitate, words.

I’m sorry, what? Intelligence and understanding is a phenomenon that emerges from… charlatanism? This appeal to foggy “no one really knows” mystery might pass muster if they were doing voodoo dances in the rain and suddenly the rock next to them started holding a conversation, but they’re not, they’re meticulously constructing a computer program to pretend to know things, capturing to an admittedly excellent degree of precision how exactly blabbering about stuff one doesn’t understand works on a technical level. This is like claiming not just that ghosts are an emergent phenomenon, but that they emerge from magicians doing the Pepper’s Ghost trick on stage. Yes, I’m sure it’s just a strange coincidence that the phenomenon from which real intelligence spontaneously emerges in a computer is programming a computer to fake intelligence.

It is becoming increasingly clear to everyone, even nontechnical people, that this is all “generative AI” has ever been, and incredibly, the AI Booster counterargument to the obvious (and rather impassioned, as evident from comments under content online these days) disgust and rejection of such fakeries (“AI Slop”) is basically to deconstruct the concept of “fake” itself (just like they try to deconstruct the concepts of intelligence, consciousness, thinking and reasoning, i.e. “but what are you other than a statistical token predictor?”) and ask: if the fakery is convincing enough that it never gets detected as fake, does it really matter that it’s fake? What is “real” except a fake that evades detection!?

“Fake” is the right word. One of the first concerns about generative AI was that it would be abused to generate “deep fakes”, i.e. audio or video of events that never took place but are passed off convincingly as recordings of real events. A “deep” fake is a fakery that is just as fake as a “shallow” fake (like an obviously Photoshopped face swap) but it is harder to detect as fake. The harder detecting the fakeness is, the “deeper” the fake is.

People immediately realized AI could be “abused” to create deep fakes, but what was largely missed (and hopefully slowly becoming clear) is that everything generative AI generates is a deep fake. Generative AI itself is a deep fake of reasoning and understanding (we could replace the term “artificial intelligence” with “fake intelligence”), and applying it to generate specific artifacts thus results in it generating deep fakes of those artifacts. This has been expressed in novel ways by people lately. A good example is the phrase “work shaped output”, coined to sharply distinguish AI generated office work deliverables from actual deliverables, pointing out that they capture all the superficial qualities of real deliverables and therefore pass shallow tests (it takes very close inspection to reveal they are not real deliverables). What I haven’t seen is an explicit tie of this concept to the already well-known concept of a “deep fake”. For example, when AI “hallucinated” court cases in citations, this is properly understood as a deep fake of a legal case.

I am going to discuss this in much detail in the later parts of this series, but the computer code AI generates is a deep fake of software engineering. The actual software powered by it is a deep fake of real software, which basically means a seemingly “functional” user interface that doesn’t actually connect to real systems (i.e. a login screen that simulates a login flow without actually logging anyone in). This is enough to fool executives who assess progress on “demos” (to be fair to generative AI, the software industry has been defrauding people with misleading demos since long before 2022), which is why they all think AI is an utterly magical thinking machine that will replace their engineering department.

Now, when I say everything AI generates is fake, that doesn’t mean AI itself is entirely fake… in the sense that there’s literally nothing there. The technology is real, which is to say: it really is a faithful programming of charlatanism, it really did memorize the entire the internet, and it really can deeply and convincingly fake things. If it wasn’t “real” in this sense, it never would have gotten off the ground. And since, in order for this elaborate parlor trick to work, AI had to memorize the entire internet and catalogue it in a way that lets it retrieve the relevant bits of text to fake understanding, it can end up “accidentally” serving a real, nonfraudulent purpose. Furthermore, it takes an enormous amount of computing resources to power AI, and computing resources can certainly be used for nonfraudulent purposes. And so, every now and then, we can see glimpses of real utility come out of the Slopomatic 9000:

  • It can retrieve and reproduce, without garbling, something it memorized in training, acting in the process as a semantic search engine for the whole internet
  • It provides access to enormous amounts of GPU compute resources (heavily subsidized in most cases), which can be used to do useful things

Neither of these are some kind of win for a computerized charlatan program. We could easily build a vector database of the internet without the “generative”, “replies like it’s alive and understands things and makes stuff up in the process” layer slapped on top of it, and we could just directly subsidize and rent massive amounts of GPU compute to look for math proofs or security vulnerabilities in code. I point this out only because the accidental utility that slips out of chatbots, completely in opposition to their intended use and claimed capabilities, is routinely submitted as some kind of refutation of the claim that they’re deep faking slop generators. It’s not. The charlatan faking his way through a tech interview had to memorize a bunch of replies to technical questions, and likely memorized the correct answer to many of them. That doesn’t change the fact he’s a charlatan or somehow prove charlatanism “isn’t all bad”.

A lot of people genuinely don’t understand the difference between understanding and expertise vs. memorizing correct answers. Maybe we can blame this on school, I don’t know. This is probably why generative AI is so effective at fooling people.

The vector database/semantic search part in particular is a legitimately useful technology. But that’s boring, and compared to the search engines we already had, an incremental improvement, not a revolution. Fuzzy semantic search of documents (or the internet) isn’t “the next big thing”. It’s not “the next iPhone”, “the next internet”, etc. So it’s of no use to Tech Bros. And it’s not “AI” so the Doomsday Cult doesn’t care either. If making semantic search work well enough actually requires gigawatts of GPU compute resources, then it’s quite simply not worth it. It’s a neat demo of a technology that may become viable if it can be heavily optimized, but that’s it. This is why the useful part of the transformer architecture isn’t being sold as a standalone product. No one could claim a better search engine is going to “wake up and solve physics”, so it can’t be hyped enough.

All legitimate uses of generative AI are non-generative

They all involve using AI as a search engine to retrieve things that already existed, not “generate” “new” content. Using AI to generate code is absurd, but using it to sift through code and find potential problems is actually useful (whether it’s useful enough to justify the unsubsidized cost is another matter). When it does so, it still blabbers a bunch pretending to understand things (it won’t just tell you “hey here’s a line of code, looks suspicious, double check it”, it pretends to argue about it), makes a bunch of stuff up and flags a bunch of stuff that isn’t wrong, so it’s not “doing a code review for you” (and if you’re not an expert you’ll be grossly misled by what it says), it’s just pointing you at something you might have overlooked so that you can review it more carefully. That’s certainly useful, but ironically if you tell AI Boosters you use AI just for stuff like this they’ll call you stupid for treating it as “just a search engine” instead of offloading your brain to it.

Procedural Generation Is the Original “Slop”

Increasingly more and more people are able to tell the distinct “feel” that AI Slop has. The fact that the output of a transformer is inherently inferior to its original training data is why “model collapse” happens (the above linked video talks about this). But this difference between what human creativity produces and recycled collages of past human creative productions is something that certain communities have been acutely aware of for decades… especially gamers.

The Elder Scrolls is a series of open world role playing games, famous for dropping you into a large, immersive world full of opportunities to explore and grow a character. If we look at how physically large the playable world of each of the games is, we see a very bizarre pattern, one that doesn’t make any sense at first. We would expect on each successive generation for the playable world to get larger, as technology and hardware progressed and the studio grew and employed more people to craft the world. Instead, we see this:

  • Arena (1994): 15 million km2
  • Daggerfall (1996): 220,000 km2
  • Morrowind (2002): 16 km2
  • Oblivion (2006): 57 km2
  • Skyrim (2011): 37 km2

The first game, Arena, is the largest by a factor of ~70, the second game, Daggerfall, is the second largest by a factor of ~4000 (it is roughly the size of Great Britain), and Oblivion is significantly larger than Skyrim. What gives!?

The answer is procedural generation. This refers to using a random number generator to assemble a set of assets (terrain types, buildings, components of dungeons like hallways and rooms, etc.) into content. Designers crafted the assets themselves, but they didn’t design every output of the generator. The generator is just an algorithm that randomly assembles those assets.

Daggerfall has a unified, traversable game world with some handcrafted locations but it is almost entirely procedurally generated. Arena is not actually a single playable world. It is a set of procedurally generated towns, each surrounded by endlessly procedurally generated wilderness (you can’t walk from one town to another, you’ll just encounter random wilderness tiles forever until the game glitches and then crashes), which makes its “playable area” kind-of meaningless (or just lore). Morrowind and Skyrim are both entirely hand crafted worlds. Designers shaped every parcel of land and built every town, building, dungeon, cave, etc. in those games. Oblivion is mostly hand crafted but has procedurally generated dungeons, which contributed to a larger playable world.

So when we say Daggerfall is 4000x as large as Oblivion, that doesn’t mean designers built 4000x as much content for Daggerfall as they did for Oblivion. They certainly didn’t, both because it would be infeasible to make so much content (if Oblivion took 4 years to make, that would mean Daggerfall would have roughly taken 16,000 years to make!) as well as store it in game files (if Oblivion fit on a single DVD, Daggerfall would have needed roughly 16,000, not to mention how many hard disks you’d need on your computer to install it on). There were, in fact, far fewer game assets in Daggerfall than in Oblivion (or Morrowind for that matter). The difference is Oblivion’s assets were placed explicitly, while Daggerfall’s assets are recycled nearly “endlessly”.

And you can tell the difference. Daggerfall feels very different from the later games. It is obvious that if you traverse around the world, you’re just seeing recycled combinations of assets you’ve already seen dozens or hundreds of times, and the combinations aren’t exactly creative. That’s fine for what it is, but in order to simulate this massive world to explore, you have to settle for a world that is repetitive and sterile in some sense.

But Morrowind is widely considered a masterpiece, while Daggerfall is at best a good and notable game. The key to Morrowind’s success was precisely that it abandoned literal scale, which could only be achieved with procedural generation, in favor of the smallest playable world of any of the Elder Scrolls games, but a world that was meticulously created. The resulting creativity was far superior, and it allowed for much deeper immersion. It turns out that once you reach enough scale, which isn’t much, you can better achieve the “dropped in a whole other world to do whatever you want” experience by designing every bit of that world than by simulating a much larger world with algorithmic recycling.

Recently, Bethesda abandoned this approach of totally (or at least mostly) handcrafted open worlds and went back to relying heavily on procedural generation for Starfield, an open world game set in space. It sort of makes sense, given that the scale of a game set in a space faring civilization spread across countless star systems, is once again at a scale much too large to hand-craft or deliver and store on a PC. But that sacrifices the creativity of a hand-crafted world and returns to the repetitive sterility of algorithmic content, and well… the players reacted predictably to it.

This isn’t to say procedurally generated game worlds can’t work (i.e. No Man’s Sky, although they had to fail before succeeding), but you can’t skimp on actual content. Procedural generation isn’t an excuse to create less content than you otherwise would, it’s to extend the scale of a game’s world. A game with the amount of hand-crafted content that is in Skyrim, but that uses it to procedurally generate a planet sized world, is very different than a game where you realize you’ve already seen all the content a couple of hours in, it’s now just being assembled in different ways. Furthermore, if you took the assets from Morrowind and fed them into a procedural generator to generate a giant game world, you did not make a new game, at best you made a barely creative (only because you crafted the procedural generator yourself) and unoriginal mod for Morrowind.

So what is the point of all of this? Well it should be obvious how this relates back to AI:

Generative AI is Procedural Generation of Internet Content

The internet is a massive amount of content, so this can be interesting for much longer than a procedurally generated game from the 90s, but you are still likely to start noticing that it is just repetitive reassembly of the same base assets in different combinations, and more importantly, you will notice the sterility of the collages. Quite simply, it’s not creative. It’s just endless rehashing.

People are starting to notice all AI generated writing is rehashing the same patterns (“it’s not this, it’s that”, rule of three, etc.), AI generated thumbnails all kind-of look the same, AI generated videos are all basically the same thing just applied to different topics, and so on. This is interesting… until it isn’t. And society seems to be getting close to being done with it. More importantly, it was never anything but entertainment. The idea serious corporate office work could be done with procedural generation is just silly, and it was always a grift.

Yes, you can generate basically endless content with an algorithm like this. But the grift of AI is succinctly summarized by the false claim that endlessly recycling what was already on the internet can serve as a stand-in for the human creativity that originally produced that content. This is why vibe coded software is always crappy “remakes” (either of video games, or maybe C compilers) and never anything new, and this is why corporations are never going to get out of AI what they think they will. AI can rehash and recycle their (and other corporations’) greatest hits. It can be a radio station that plays a catalogue and maybe even remixes it in interesting ways. But it’s never going to make a genuinely new song. It will not create the next product or application that doesn’t already exist.

Conclusion

AI isn’t “so good it’s bad”, “so good it needs to be regulated”, or “great but just too dirty”, it’s just bad. Nothing about the world in the last 3 years has gotten better from AI showing up. It has just polluted the internet and given the most annoying people an excuse to be even more loud and annoying. This is what being “anti-AI” sounds like.

The only content creators I have encountered that I can fairly say are really anti-AI are David Gerard of “Pivot to AI“, who has proven uniquely excellent at seeing right through the constant scams around it, and Ed Zitron, who’s been exposing the financial calamity of generative AI fueled by the totally false promise about what it is. Both of these guys have been hosted repeatedly by The Tech Report. I obviously highly recommend all of these channels, but also find it strange how it seems to only be a few prominent people. I have encountered more “anti-AI” videos and channels on YouTube as well as content elsewhere than I can remember, but it pretty much always falls into one of the categories I listed above, which means it mostly compliments AI as a technology and regurgitates the obligatory “AI is here to stay” disclaimer. I never found that content particularly interesting and it doesn’t align with my own viewpoint really at all.

If your reaction to this is to protest that this analysis simply cannot be true because AI has already revolutionized the world, the next part of this series is just for you!

The Immutability Fad

Introduction

The programming community goes through fads regularly, and they start repeating after a while. It’s very similar to the fashion industry, where at any moment there is a force to be both not wildly different than what everyone else is doing (out of fashion) while at the same time being slightly different (fashion forward), which sets up an oscillator on variables like tie width, tight vs. loose fit, etc.

I suspect the programming community is going to see-saw back and forth between the object-oriented (OOP) fad and the functional (FP) fad in perpetuity. OOP was “in” in the 90s and 00s, and FP started taking over in the 10s and is now very much “in”. Just look at all the new GUI frameworks these days. Despite the fact the programming is aimed at solving an objective problem in a way that fashion is not, it may seem strange that an engineering discipline would experience the same aesthetics-driven phenomenon. But the same forces are at play: a balance of conservatism (this is the official way everyone does it, if you do it differently other coders won’t be familiar with it) and progressivism (programming is hard, and if it’s at all the fault of patterns we’re following that it’s this hard, doing things differently is the way to make it not hard).

They don’t balance, so a gradual evolution occurs. But it’s not the Whig theory of history: the progressivism doesn’t just plainly make things better over time. The source of today’s difficulty is misdiagnosed, a lot of it is simply wishful thinking (trying to make programming Simply Not Hard™ anymore), so it really does come down to “different for the sake of different”, and because it doesn’t really make things any less hard, once those different patterns become the norm, and it turns out things are still hard, people are going to want to be different going back in the opposite direction.

The primary mechanism by which this occurs in programming is that old patterns get followed for years, giving birth to large, complex years-old codebases that follow those patterns, implementing the behavior of very complex, sophisticated programs (because entire “product” departments of businesses are paid to do nothing but invent more complexity to add), and gradually accumulating cruft, tech debt and design warts due mostly to a combination of being rushed by the business and being built by novice or low-skill programmers.

The revolutionaries present these complex codebases alongside tiny, trivial “sample apps” contrived solely for the purpose of demonstrating their patterns as better, and say “behold! Look how much simpler this tiny sample app is compared to the production codebase you’ve been working on!” People buy this argument, spend years building real production apps with the new patterns, they degrade for the same reasons, and people learn the hard way that they, too, are complex and messy. Rinse and repeat.

This is obviously what’s going on because the propaganda of “Paradigm X is dead, long live Paradigm Y” is laced with wild promises (precisely that the new paradigm will make programming Simply Not Hard™). As time goes on, these sales pitches become easier to believe because they’re mostly refuting the unrealistic sales pitch of the previous paradigm shift. OOP promised to make programming Simply Not Hard™, it certainly didn’t do that, so FP is now here demonstrating (correctly) that OOP failed its promise, giving the discussion an air of authority, and making it easier to believe that FP is the true way to make programming Simply Not Hard™.

I’m not suggesting genuine progress doesn’t happen. It obviously does. No one’s writing articles titled “Compilers are Dead, Long Live Assembly”. There’s little controversy over genuine progress. The controversy is over stuff that’s either largely a matter of personal taste, or a battle of mutual false promises driven by people who don’t understand why programming is hard and that it never won’t be (it’s hard because it’s logical problem solving, where all tiny details need to be worked out and accounted for. This is never going away).

Mutability: Ontological Evil Manifest

One major, if not the central, feature of the FP fad is immutability. Apparently, mutability in computer programs is the source of pretty much anything bad. Mutability causes logic errors, destroys thread safety, makes programs harder to reason about, contributes to global warming and probably harbors extremist political views.

You know this belongs to the “oscillating fashion trend” category because of these ridiculous promises, like that if you program in an immutable functional style you’ll basically never have logic errors or thread safety issues. I’ll explain later the specific fallacy people use to justify this claim.

I’m not saying this because I’m an OOP fanatic. I think both of them are fads.

I’ve always found “mutability is bad” to be a strange assertion. Taken to its logical conclusion, yes a program working with only immutable state would surely be much, much easier to reason about and not suffer from any logic errors or race conditions… because it wouldn’t do anything. A completely immutable GUI app is otherwise known as a PDF. It just sits there. It displays state that doesn’t and can’t change while the program is running.

But this has to be a straw man. The FP crowd isn’t telling people to stop writing, well… programs. They’re claiming that somehow behavior, dynamism, change, or what I ask you to please recognize is a synonym for all of those: mutation, can be achieved in a paradigm of total immutability. It sounds like a naked contradiction. What’s going on here?

Well, if I have a some state, S1, even if it’s immutable, I can create new state, S2, by calling a function that takes S1 as an input and returns S2 as an output. I didn’t mutate S1, I just created a similar but different in a few ways state S2. S2 is also immutable. If I want something in my program to change, I create another new app state, S3, from S2.

Okay fine, each instance of this app state is immutable, but if what I’m seeing on screen is supposed to change, then certainly the state of the UI is changing. Somewhere the UI has to track the current app state, and that is going to mutate from S1 to S2 to S3, right? I haven’t eliminated immutability, I just concentrated it in the reference to a “current” value instead of in the individual fields of the value (we’ll explore the implications of this difference more below).

Ah, but we continue the argument into the UI! The UI state isn’t mutating, there’s another function that takes an app state S and returns a UI state U. For each app state S1, S2 and S3, each one is put into this function to create corresponding UI states U1, U2, and U3. Just as the app state is not mutating but simply new slightly different copies are being created, so too is the app state not mutating, new copies are just getting created.

Um… okay (I’m starting to get slightly annoyed now, you’ll see why soon). So you make new immutable copies of the UI state every time the app changes (*cough* mutates *cough*) what it displays. But you’ve just shifted the problem again, not eliminated it. Only one of those states is going to be sent to the frame buffer, which is what the computer hardware is actually drawing on my computer monitor. So the frame buffer is still going to have a current UI state, and that is going to be mutated by setting it to U1, then U2, then U3, etc.

But you don’t understand! We simply keep pushing forward in the same way. The frame buffer isn’t mutable! There’s a function that takes a UI state as an input and returns a frame buffer as an output. Each time a new copy of the UI state is created we just use that function to make a new copy of the frame buffer.

Oh for f*ck’s sake…

Alright, so you’ve got copies of the frame buffer being created. You still have to decide which one is read by the computer hardware and sent to the monitor at any given moment. You have to have a current frame buffer, and that will mutate!

This is where it’s going to get plainly ridiculous. This isn’t a straw man. Hold onto your hats. Here we go:

There isn’t one monitor! As every moment in time passes, a new copy of your computer monitor is created, each one potentially being slightly different than the last copy. New copies of your monitor are being created on every tick of time in the physical universe in which we live. Those copies are created by calling a function that takes the copy of the frame buffer created from the copy of the UI state created from the copy of the app state, and since each copy can be slightly different than the previous one, each copy of the monitor for each moment in time will be displaying something slightly different.

Reality is, in fact, entirely immutable! Mutation is just a pedestrian way of modeling things. The brilliant FP philosophers have realized that nothing changes, instead for every instant in time there is a copy of the entire universe, created from a function that takes the previous copy as an input. “Mutability” would mean you could go back in time and edit the past. But you can’t! The past, meaning already constructed copies of the universe, is immutable. You can only move forward in time, which means creating more slightly different copies of the universe that existed in those past moments.

I have a phrase that I do not hesitate to use when I start hearing stuff like this, and I spent four years in college, so I’ve heard plenty of it:

“This is so stupid only a smart person could have come up with it.”

I mean, seriously, does anyone really conceive of the world like this? If you paint your car, you aren’t changing the color of your car, you’re just causing the copies of the your car that get produced every Planck time unit to be slightly different from the previous one by having one extra microscopic stroke of new paint? And you believe that’s anything but an extremely convoluted and confused way to say “you changed the f*cking color of your car”?

But let’s be fair, I’m just having an emotional reaction to this. One that I think is entirely warranted (who’s more foolish, the fool or the fool who debates him?), but nevertheless my “reeee”ing doesn’t count as a refutation. So let’s formally refute this once and for all.

Even if it is true that the universe creates copies of the entire state of all physical objects and sticks them in a dictionary mapping instants in time to states of all physical objects, this still fundamentally cannot eliminate mutability. First of all, does this dictionary mutate each time the clock ticks and a new moment in time is created? Well, maybe you’re an ultra-Calvinist and you think everything is perfectly predetermined, the dictionary is already fully built up from the beginning to the end of time itself. If not, you’d have to concede that on every tick, new copies of this dictionary are created, discarding the previous one that contained all time-state pairs up to the previously latest moment in time, with the new one containing all the same time-state pairs as the previous, plus a new one for the now latest moment in time.

Regardless, we now come to the crux of the matter. Whether new dictionaries are being created constantly, or there’s one ultra-predetermined dictionary, there’s still one thing in this ultra-immutable universe that must be mutable:

Now

Whatever instant in time is considered to be “now” has to mutate. The clock has to tick. Trying to model this as immutable gets stuck in an infinite regression. “No the moment that is now is copied on every new moment”, but you have to pick which one is the actual “now”, instead of a historical “now”. If all the “now”s are a stored in an array where each new copy is one larger than the last, you still have to say that the true “now” is the last element of the array… but which array (what if you hold all the arrays in another array, and say the current one is the last element? Again, that array changes when a new array is added, and we’re back to the same problem)? All the historical ones are still out there. You have to assign a “latest”, and that’s a mutating variable.

Honestly we’re doing rigorous super-abstract philosophizing to remind ourselves of what everyone already knows: things change. You aren’t experiencing all moments in time. You experience a particular moment at a particular moment (this is already becoming unworkably circular), and that particular moment changes. That’s what time means. Time is the parameterization of mutation (our minds recording snapshots of the changing state of physical objects and storing them in order). Modeling the universe as copies being keyed by moments in time is failing to recognize what time is. At best those keys are proxies for time, not time itself.

Yes you store all the frames of a movie sequentially in memory somewhere, where the index of a frame indicates the time of the frame. But that data is static. Those characters aren’t alive, they aren’t moving, they don’t do anything. The index isn’t literally time, it’s literally an index in an array, an offset (meaning a location in space) in memory. The only way to make it come alive is to play the movie, which means to create a connection between that index and literal time: you use actual time, what an actual clock tells you, to pick a frame to show. Because clocks tick, because the time they read changes, the displayed frame changes. Suddenly the movie becomes dynamic, a living simulation of whatever was filmed, not a dead one that sits still in memory banks.

You can never eliminate the mutability of “now”. If you did, the universe would simply be the frames of a movie sitting in memory banks somewhere, but with no external time (there’s nothing external, this array of frames is everything that exists), there’s no way, it’s not even meaningful, to “play” the movie. This describes a dead universe where nothing happens, nothing changes, nothing mutates.

Of course it does. Of course immutability implies nothing mutates! Come on!!

What Does “Immutable” Actually Mean?

Now, what was the point of that exercise? I thought we were trying to write software, not get stoned and talk about the meaning of existence.

Strained sophistry notwithstanding, it’s plainly not true that there are multiple frame buffers. There’s one (well, probably two or three, to prevent visual tearing), it has an address in memory, and its content is changed (mutated) by your running app. The “interpretations” to make that immutable only prove that “viewing things as immutable” in this way is actually not different than viewing things as mutable. The whole distinction becomes almost meaningless. Where and how it remains meaningful is what we need to talk about now.

It’s not hard to spot the obvious contradictions in articles about this stuff. Look at this article, not just at the title but within:

However, if you’re using Redux, you need to know how to modify your state immutably (without changing it).

Does anyone else not find this sentence hilarious? How to change something unchangingly without changing it!?

This plainly contradictory phrase appears in none other than the Redux docs themselves:

It’s also not obvious just by looking at the code that this function is actually safe and updates the state immutably

Update something immutably!? What are these guys smoking?

Yes I know what it actually means, but they’re obviously using the wrong words for it. None of this has anything to do with immutability. To say that in redux, you can only mutate the app state through reducers, is saying something meaningful, and in fact very important, it just isn’t about immutability. The app state can obviously mutate. But no one has unfettered permission to do so.

See, that’s the point. Mutability is controlled. You don’t just give naked write access to all the fields inside your app state to everyone who wants to read the app state. You make them go through functions that limit how mutations occur. You protect your app state by making sure it mutates only in a limited set of ways that you allow.

Now someone’s going to tell me I’m wrong, that in Redux the app state really is immutable, and that reducers don’t mutate state, they emit new values of state. Yes there’s a real distinction there, we’ll talk about that below, but I’m not wrong to say the state that comes out of the reducer gets reassigned back to the mutable reference-semantics state variable inside the Store, and thereby mutates what the app considers to be the state.

The difference in Redux isn’t the mutability of the app state. It’s who is allowed to do what mutations on the app state. We have a word in programming for this concept, and it’s not “immutable”. It’s “encapsulation”.

All this is telling us is that the app state is encapsulated. It’s a specific type of encapsulation in redux patterns: reading is not encapsulated, but writing is. You could choose to encapsulate reads as well, but the overarching point of this really seems to be that encapsulating mutation is far far more important than encapsulating reading.

I absolutely agree.

But see, “encapsulation” is one of the “four principles of object-oriented programming” (whether it’s legitimate for OOP to lay claim to it is another matter), so FP fanboys can’t be caught using that word.

That’s what’s kind of funny, and at times confusing, about these discussions. They get framed as big philosophical defenses of paradigms that, taken at face value, are totally wrong, but the framing itself is also wrong, and these two wrongs end up producing rights: it’s wrong to say that immutability solves these problems, and it’s wrong to frame redux’s limitation of mutation as a form of immutability (obviously), and these combine to a correct statement “it’s good to protect writing to your app state much more strongly than reading from it”.

Of course there are plenty of ways to do this that don’t require reducers. Make your fields public get and private set, and define your “reducers” to just be public functions on your app state type. The only difference between this and redux is that you don’t save copies of your state before updating it. But you easily could, just make it observable, subscribe to it and save every published update to an array somewhere.

I’m not saying you should or shouldn’t pick one or the other, I’m just saying the raison dêtre of redux is not at all an essential part of that pattern, it’s something that’s achievable in a myriad of ways in all widely used programming languages in the industry. Once that’s clear, it really makes you wonder: what’s the point of all of it? If reducers and actions is just a (very convoluted if you ask me) way to create data that’s publicly readable but not publicly writable, with some public methods for modifying it, why not just make a class?

Well, there’s a frequent assertion I hear from the “OOP sucks, let’s all write enterprise software in Haskell” people: the the hallmark of OOP, and the principle reason it sucks so hard, is that it “pairs data and functions together”. The article by Joe Armstrong is a canonical example.

The complaint isn’t about the irrelevant syntax difference between x.doThis(y) and doThis(x, y), or the fact that functions for a class are written inside the class, next to data. No, functions and data are “paired” in a more significant way than the mere mechanics of OOP languages: the methods are the only functions that pierce the encapsulation boundary of the object. Any language that supports encapsulating data will support pairing functions with that data (otherwise, that data becomes literally inaccessible to every part of the program, and might as well not exist).

Now, the weird part about this is that the functional languages they praise often support this. Both Haskell and OCaml call them “modules”, and they exist to create encapsulation, which is the fundamental mechanism of creating abstractions, i.e. an X that is simply an X and not the sequence of bytes that happen to be used, today, to implement an X. This is literally pairing data with functions, in the exact same way than OOP class closes over its fields (data) and members (functions). I don’t think it has ever been stated by FP language designers that encapsulation, which involves pairing data and functions, is somehow incompatible with a paradigm of immutable values and pure functions. The two seem quite unrelated.

In that article Joe Armstrong, after declaring that data and functions “should not be bound together” (because they aren’t identical concepts… I’m not sure how “X should not be bound with Y” logically follows from “X is not Y”), goes on to directly attack encapsulation. This section is honestly headache inducing. The argument seems to be: FP languages eliminate all state from a computer program by exposing all state as input parameters and return values of every function, which hides all the state by giving you full access to the state, which is good because hiding state is bad.

It was reading stuff like this that made me start to think all the Redux immutable functional stuff I keep encountering, and consistently not knowing what the hell the point is, is just a bunch of deeply confused gibberish from people who’ve managed to convince themselves they write computer programs that do something other than mutate state, and defend this by saying everyone through all of history has fundamentally misunderstood how the universe works and really there’s no such thing as state or change at all (if that’s true, surely OOP programs aren’t mutating state either, because state and mutation don’t exist, they’re just emitting new copies of the heap and stack on every clock cycle).

The Real Problem: Reference Semantics

Anyways, I can’t help but conclude that the insistence to do Redux instead of just writing a type with private fields and controlled methods for modifying those methods is due only to this confusion that: pairing mutable state and functions into a class is an anti-pattern that causes unnecessary bugs, but we need encapsulated data that can change over time so we still need a way to do this but in a way where we can, with a liberal dose of squinting, tell ourselves that everything is immutable and we’ve kept data and functions completely separate.

Look at this diagram:

This is literally just a class. The “state” is a private field, and the “actions” are methods:

class State {
  #account = { ... };

  deposit(amount) {
    #account.balance += amount;
  }

  ...
}

Wrap it in an Rx Observable (or some comparable equivalent) and now you’ve got your subscribeTo capability, which you can use to store a growing array of the historical values.

There’s a problem though.

Recall that Redux originated in JavaScript. Well, because of the way objects in JavaScript (and, in fact, most OOP languages) work, simply wrapping a State instance an RxJS Observable won’t correctly publish an update event when we call one of the methods:

const state = BehaviorSubject(new State());

state.subscribe(state => console.log(`New state: ${state}`));

state.value.deposit(10); // Doesn't trigger the log statement

Why not? Well, because of “mutability”… but that’s not the whole story, and saying it like that is confusing because we’re trying to mutate the state, how could mutability be the problem!?

No, the problem is that the mutability is on the internal #account field. Actually that’s not even right. What we’re mutating is the balance member inside the #account. The State instance itself doesn’t change, not even #account changes. Notice that we’re not calling .next anywhere to publish a new value. We’re reaching inside the BehaviorSubject, getting its value, which is “read-only”, but we are just reading it, but we’re calling deposit, which doesn’t mutate this, it mutates stuff inside of this.

Really, making value read-only is almost useless, at least when it’s holding an array or object. Claiming that the value is read-only, but that you can reach inside of it and change whatever you want (as far as the type’s encapsulation allows) is borderline fraudulent. It’s not necessarily bad modelling that I can go through an object’s member and make modifications to it while claiming I didn’t modify the object, but in many cases it most certainly is bad modelling.

For example, consider me as a value. I have two members: my left arm, and my best friend. If you replace my original left arm with a cyborg arm, have you mutated me? Absolutely! If you go to my best friend and replace his arm with a cyborg arm, have you mutated me? No. What’s the difference? My leftArm member is a value, the arm itself, but my bestFriend member is not the person himself (including all his members, like his left arm), it’s a reference to the person. Changing something about the person who happens to be my best friend doesn’t change me. What would change me is to change who my best friend is: that is, to change the reference itself stored in bestFriend.

This is the well-known problem of “value vs. reference types”. Objective-C, Java, C#, Swift and JavaScript treat the distinction on the metatype level (they have types of types that are values are references respectively, i.e. class and struct), and only C# and Swift let you define custom value types (unless you count custom C structs in Objective-C, which you usually don’t because they don’t interop well with Objective-C). For the rest, the only value types are the handful of primitives that come with the language. C/C++ treat the distinction on the type level (all types have value semantics, but some primitive types, namely pointers, provide referential access to other values. C++ references are a sort of unique oddball). Kotlin defines a value type as a class that obeys certain conventions (strictly speaking they always have reference semantics, but if you make them immutable enough you can’t tell that they have reference semantics… interesting, there’s that word “immutable” showing up in a discussion of references vs. values).

In JavaScript, an object has to be a “reference type”, which means you can’t actually work directly with object values. When you assign a variable to an object, you’re really assigning the variable to a reference to an object instance. This means you have no choice but to model members of one object that are themselves objects as being references. If you model an arm in JavaScript as an object, then my leftArm can’t be the arm itself, it has to be a reference to an arm, in the same way bestFriend is a reference to my best friend. Then, just as modifying my best friend doesn’t modify me, neither does modifying my arm modify me. Sure, replacing my arm, as in assigning my leftArm to refer to another arm instance modifies me, but I can go inside the existing arm reference and change stuff without changing me.

The problem repeats on every level. If an arm is an object made up of members, if those members are also objects, you can once again go inside the referenced instances and change stuff without changing the arm, and repeat if those objects’ members are once again objects.

Being forced to model all complex objects, on every level, as references, is a major restriction in a language’s ability to model things. And it is a direct consequence of OOP fanaticism in the 90s: if “everything is an Object“, well what exactly is an Object? It’s not just a synonym for “thing”, that would make it meaningless. This means a lot of things, including that literally every type you can define inherits an Object type… and this implies one key capability of Objects is inheritance, which is assumed to imply polymorphism (that if I have a variable of type BaseType, I can assign to a DerivedType), and the straightforward way to implement variables that work this way is as references (literally pointers is how C++ and Objective-C did it, and Java imitated C++ in this way).

So, there’s a legitimate point buried under all the pseudo-philosophical gobbledygook about “stateless immutable programs”: a misplaced insistence that “everything must be an object”, which specifically means every variable must really be a polymorphic reference, caused mutability to be shattered and spread across the model when in many cases this is incorrect and mutability of parts should be equivalent to mutability of the whole, which also implies those parts should have value semantics: copying the whole should also copy the parts.

The problem is not the existence of “mutable state”: that’s called a computer program. The problem is an overly restricted, and therefore often wrong, model of mutability, wherein the parts of something can always be mutated without considering it a mutation of the thing itself, and there’s no way in these languages to express that no, that’s not right, in this case they are one and the same.

Since we can’t express this directly in these languages, what do we do instead? We enforce it in a more ad-hoc manner. We simply can’t make object members have value semantics. But what problems does that cause? It makes it possible to mutate those objects even on “immutable” (read-only) instances of the containing object, and it means when we copy the containing object the member objects don’t also get copied.

The second problem isn’t really a problem because it’s reference semantics all the way: the containing object never gets copied in the first place, unless we specifically call a copy function in our code. Since we must define this copy function ourselves, we can decide there that it will copy the member objects too.

The first problem is about mutability of the members. We fix this with encapsulation, in order to make anything that mutates them without also mutating the containing object impossible to do from the outside, and then we just avoid doing those things in the class itself. What does that take? In our example above, the trouble comes from the deposit function that mutates the #account field. We must not write any methods that mutate fields. We instead replace the “mutating” method with an “immutable” flavor of it, which creates a new value:

class State {
  #account = { ... };

  deposit(amount) {
    var result = new State();
    result.#account = #account;
    result.#account.balance += amount;
    return result;
  }

  ...
}

But this isn’t correct yet. We’re assigning the #account of the copy to our #account, which means we’re assigning the reference. That means we’re sharing the value: when we mutate balance, it affects both the copy and us. We have to also copy the value of #account first. Well how do you do that? If you did a memberwise assign with a spread ({ ... #account }) you copy the top-level object, but not any members that are themselves objects. You’d have to do the same to those, and so on.

Is there a way to do this in general for any object in JavaScript, so that a deep copy is made on all levels of members, ensuring you have a fully independent instance? Yes: serialize it to JSON, then deserialize it back to an object. But that also might not be correct. Some of those members might genuinely be references (this doesn’t make the containing object mutable as long as the object being referred to follows the immutability rules itself), and you don’t want to copy those. Ultimately, you might have to make a bespoke copy function for your structure that understands at each level whether an object is a reference or a value. This is because the language has no idea about the distinction and can’t discover it.

This is already turning into a major pain in the a**. So I’m starting to have more sympathy for JavaScript developers inventing the Redux stuff instead of dealing with all of this.

Anyways, once we are properly copying the #account object, we have to actually assign this value, which for the BehaviorSubject means calling .send:

const state = BehaviorSubject(new State());

state.subscribe(state => console.log(`New state: ${state}`));

state.send(state.value.deposit(10)); // Triggers the log statement!

What if we want to be able to read part of the state, like the value of #account, from the outside, but not be able to write to it? If #account is an object, returning it in a getter returns a reference to it, and then we can fiddle with its insides. Instead we need to return a copy. Luckily we already had to figure out how to copy the thing, so we just use that:

class State {
  #account = { ... };

  get account() {
    return #copyAccount();
  }

  deposit(amount) {
    var result = new State();
    result.#account = #copyAccount();
    result.#account.balance += amount;
    return result;
  }

  ...

  #copyAccount() {
    ... // Do whatever it takes here
  }
}

This way, the object that comes out is guaranteed to be independent of the one inside the State object, so no fiddling with it will affect that object.

Alternatively, and I think this is a better approach, we can define classes on every level, and design them all to be immutable. Then instead the custom copying logic, i.e. what is value vs. reference semantics, manifests in what members are immutable types or not. If you want to alter an immutable-type member inside of an immutable type, you have to make a new instance of the member type, and then make a new instance of the parent type. That means you have to write a similar function on the member type that creates a near-copy, or “mutator” (it returns a new value that is identical except for one part that you specify to be different), and this repeats until you get down to primitives.

This shifts the custom copying logic from deciding which members, upon making a copy, need to be deep-copied (and those members then determine what deep copying means), to different copies sharing instances of members but those instances cannot be modified in any way, so they act as semantic copies (you can’t tell they’re being shared), and you only make a deep copy when you need to make a modified instance. Both achieve the same result of distinguishing members that are the values themselves from members that are really references.

Here’s an example with the “mutator” methods that produce near-copies:

class State {
  #account;
  ...
  
  constructor(
    account, 
    ...
  ) {
    this.#account = account;
    ...
  }

  get account() {
    return #account; // No need to copy, because Account is immutable
  }

  deposit(amount) {
    return new State(
      this.#account.deposit(amount),
      ...
    );
  }

  ...
}

class Account {
  #balance;

  constructor(balance) {
    this.#balance = balance;
  }

  get balance() {
    return #balance;
  }

  deposit(amount) {
    return new Account(this.#balance + amount);
  }
}

If we upgrade to TypeScript (which of course you’ve done, right? Right?), it’s even better because we can actually (sort of) enforce some of this “immutability”, or at least express that that’s the intention, and that eliminates the need for getters, we can expose fields directly:

class State {
  readonly account: Account

  constructor(account: Account) {
    this.account = account
  }

  deposit(amount): State {
    return State(account: this.account.deposit(amount))
  }
}

class Account {
  readonly balance: number // Oh yeah, storing a bank balance in floating point format, what could go wrong!?

  constructor(balance: number) {
    this.balance = balance
  }

  deposit(amount: number): Account {
    return Account(balance: this.balance + amount)
  }
}

You can be sure that any class you write is immutable as long as it is composed only of primitives and readonly class/array members… but keep in mind that those class/array members will have reference semantics unless you ensure the type of that member is an immutable type. For example, the array type you get out of the box in JavaScript is not an immutable type, so if you have an array member of your class, even marked as readonly, it is a reference to a particular array. If you can obtain the member through a getter, you can then start modifying the array.

If you want an array (or tuple) value type, TypeScript gives you one and even supports nice syntax for it. They also give you read-only (immutable) versions of other collections like Map and Set, and a Readonly<T> wrapper for any type.

If you aren’t using TypeScript you have to build a read-only array yourself:

class ReadonlyArray {
  constructor(values) {
    this.#values = values;
  }

  *[Symbol.iterator]() {
    yield* this.#values;
  }

  get(index: number) {
    return this.#values[index];
  }

  set(index, value) {
    let values = [...this.#values];
    values[index] = value;
    return new ImmutableArray(values);
  }

  append(values) {
    return new ImmutableArray(...this.#values, ...values);
  }

  remove(index) {
    let values = [...this.#values];
    values.splice(index, 1);
    return new ImmutableArray(values);
  }

  #values;
}

Before you get any crazy ideas (and despite what the FP fanatics say), you can’t, and wouldn’t want to try to, make everything an immutable value type. Your program is going to need to work with identifiable things. You need to choose judiciously which members of which types are values (they obey the immutability rules) and which are references (they are mutable arrays/objects), which you do by choosing the types of those members to be immutable types or mutable types. But what if you want to define a particular type and use it as a value in some places and a reference in others? Following this approach you’d have to write two versions of the type, an immutable flavor and a mutable one (much like the two flavors of arrays in TypeScript).

Another approach is to define all of your types as immutable, making them represent values not references, then define a dedicated type for a reference:

class Reference<T> {
  protected _value: T

  constructor(value: T) {
    this._value = value
  }

  get value(): T {
    return this._value
  }
}

class MutableReference<T> extends Reference<T> {
  set value(value: T) {
    this._value = value
  }
}

This allows you to more finely control encapsulation. You can define a MutableReference<T> instance somewhere, and hand that out to whoever should have write access to that identifiable object. Then you can hand it out upcasted to a Reference<T> to anyone that should only be allowed to read it (but will see modifications those with write access make to it). Done with inheritance this is easy to defeat by simply downcasting, but if that’s a concern to you, you can do this with composition as well (get rid of the inheritance and make Reference<T> hold a private MutableReference<T> member that it forwards the value getter to).

This approach is really an attempt to emulate what C++ gives you out of the box: define all your types like MyType to have value semantics then use MyType* (or a smart pointer like shared_ptr<MyType>) as a mutable reference and const MyType* (or a smart pointer like shared_ptr<const MyType>) as an immutable reference.

Well, if the solution to the problem is to make State (and sub-objects, and so on) an “immutable” type, then was the problem actually “mutability”? Well, not the existence of mutability, but its distribution. We aren’t eliminating mutability, we’re bringing several little islands of mutability together into a big island nation of mutability.

Since the language makes it so difficult to model deep trees of aggregates as a single value whose parts cannot change without that constituting a change to the whole, yeah… Redux starts to make a little more sense. But it’s ultimately not solving the problem. In Redux you get a “copy” of the current state passed into the reducer. Well that’s whatever type of object you initially specified, and if you fiddle with it’s insides, you’re fiddling with the internals of the store’s private state instance. And then stuff just breaks. It still comes down to “just don’t do that”. If you want to prevent this, you have to go through the trouble of defining classes that follow the immutability rules.

So… this doesn’t really make things any better, and you have to do silly stuff like define enums with a 1-1 correspondence to functions, and then write out the switch statement confirming that the two are, in fact, 1-1 (why define a new concept just to make it equivalent to an existing concept and then spell out the identity mapping between them?). Maybe this is because people got a vague notion that the original problem has something to do with mutability, they heard about these “functional languages” where everything is immutable and it’s impossible to have mutability bugs, and the way you model the state (which mutates as the inputs come into the program) in a functional program is as a list built out of a reducer over the sequence of program inputs. So then the solution to this mutability issue in JavaScript must be to model application state with reducers the same way you’d model it in a Haskell program.

Blaming mutability is not thinking about this carefully and understanding the problem is not mutability itself but reference semantics and the implication that has for how mutability is distributed and linked (or not linked) together. Understanding that this is the root cause of the problem makes it clear the proper solution is figuring out how to model aggregates as value types, and the fundamental mechanism of value semantics is copying, so you have to either define the copy function for your state object, or use immutability to ensure that shared references act as semantic copies (you can’t tell they’re not literal copies because you can’t modify one “copy” and see the modification in the other “copy”) and write “near-copy” (mutator) functions for mutations, which require any mutation to something deep inside your app state to cascade all the way up to a mutation of the entire app state.

Is It Just JavaScript?

How do you deal with this in other languages? In Objective-C and Java, it’s the same as JavaScript: you make “immutable” classes with hand-written copy-mutate methods and compose them. Objective-C makes this pattern more canonical as its core collection types (NSArray, NSDictionary and NSSet) are immutable (and have those hand-written copy methods). In C#, you get true value type aggregates called structs, which alleviates you of having to write the copy function yourself because the compiler can tell (by your choice of struct vs. class) whether a variable is the value itself or a reference and can therefore write the correct copy function for you.

In all these cases, syntactically this means replacing in-place mutation style code with whole-value replacement through immutable methods. This:

state.account.amount += 10

Becomes this:

state = state.withAccount(state.account.withAmount(state.account.amount + 10))

This is pretty close to the TypeScript example above. You’ll probably write a lot of helper functions in places where you have to reach down through multiple levels. That’s what the deposit methods are.

C# has this awkward problem where by default you can write the code in the first example, but it ends up creating a copy, mutating it and throwing it away. More specifically, when you call .account, assuming the result is a struct, you get a copy, not the one inside state, you change it’s amount, but it’s an unnamed temporary and just gets immediately thrown away. I’m pretty sure the compiler at least warns you about this. You can prevent this by marking the structs as readonly, and then this line becomes fully banned and you have to write the second line or some equivalent. It’s unfortunately this isn’t the default, so the conventional wisdom now is to just mark all your structs as readonly.

C++ is on par with C# here: you pick values vs. references by making the types of your members either T itself or T* (or some pointer-like type such as unique_ptr<T> or shared_ptr<T>). But it’s more powerful in two ways: first, it writes the default copy constructor for you, but you’re allowed to customize it too. You need to make sure you follow const correctness, i.e. if you return references to private fields, make sure it’s a const reference. Second, you immediately get to declare any field of any type to be a value or a reference, by choosing between T itself as the type or one of those above-listed “reference to T” types you get for free. Since it’s trivial to give a type reference semantics, a good rule of thumb in C++ is make all your types have value semantics (if it doesn’t make sense to copy it, delete the copy constructor), instead of writing classes that have reference semantics you can’t strip off.

As I mentioned, you can emulate this in C# (and Swift, which has the same struct vs. class dichotomy), by making everything a struct and writing a generic Reference<T> class that just holds a struct member, to use wherever you need reference semantics. You can’t change the fact other code doesn’t do this, but you can make your code follow this pattern. It’s an idea I’ve been increasingly exploring, particularly in Swift. The main downside is you can’t suppress copying… but Swift 5.9 introduced non-copyable structs!

The language that I think best solves this problem is Swift. The language designers realized that people want to write the in-place mutation style of code, but have that actually mean whole-value replacement that doesn’t sneak around the const-ness of the top-level value. So they defined mutating functions on structs (value types, like in C#) to work this way via a special inout function parameter. Since the “immutable style” so often involves reading a value, calling a function to produce a new related value, then assigning it back to where it came from, they formalized this pattern directly into the language. This way, you can write the in-place mutation line and it will, in fact, replace the whole value and call whatever setter the top-level read-write variable defines… which implies if the top-level variable is read-only (doesn’t have a setter) you aren’t allowed to write this line.

This:

struct State {
  private(set) var account: Account = .init()

  mutating func deposit(amount: Decimal) {
    account.deposit(amount: amount)
  }
}

struct Account {
  private(set) var balance: Decimal = .init() // Ahh, that's better.  No more mystery pennies.

  mutating func deposit(amount: Decimal) {
    balance += amount
  }
}

var state = CurrentValueSubject<State>()
let subscription = state.sink { state -> print("New State: \(state)") } 
state.value.deposit(amount: 10) // Line is printed!

Is equivalent to this:

struct State {
  let account: Account

  init(account: Account = .init()) {
    self.account = .init()  
  }

  func deposit(amount: Decimal) -> State {
    .init(account: account.deposit(amount: amount))
  }
}

struct Account {
  let balance: Decimal

  init(balance: Decimal = .init()) {
    self.balance = balance
  }

  func deposit(amount: Decimal) -> Account {
    .init(balance: balance + amount)
  }
}

var state = CurrentValueSubject<State>()
let subscription = state.sink { state -> print("New State: \(state)") } 
state.value = state.value.deposit(amount: 10) // Line is printed!

Really, the compiler turns the former into the latter. In the latter example, all the members of the structs are lets so they are formally “read-only” structs. But structs in Swift (unlike in C#!) are always read-only. Making “mutable lookalike” structs with var members just generates all these helper copy-mutate methods automatically and let’s you call them with mutation-style syntax.

Notice that the fact the CurrentValueSubject subscription fires is pretty obvious in the second example, because it’s explicit: we’re assigning value. But in the first example (without helpers we might have written state.value.account.balance += 10) it’s perhaps surprising, especially if you’re familiar with other languages and the fact the syntactically equivalent code in other languages would not fire the subscriber. That’s what is cool about this approach. You get this behavior you probably want for free, which is fundamentally because Swift lets you write the direct mutation syntax you want but ensures the side effects of mutating the whole occur even if you (apparently) mutate the part. No sneaking around invariants and triggers by reaching inside of stuff.

What’s funny is I’ve seen Swift devs scream “mutability, nooooo!!!” when they see the first code, after reading about how evil “mutable state” is, and then demand this be replaced with the immutable style of creating new values and assigning them back to the read-write value at the top… not realizing apparently they’re the exact same thing: Swift’s “mutation” of value types is just a more clear and straightforward syntax for achieving the exact behavior that the immutable “assign back” code spells out more explicitly.

“Eliminating” Bugs?

Now, here’s the fallacy that almost everyone uses when they make the “my pattern eliminates this whole class of bugs from your programs” arguments: it is usually true by definition, because that classification of bugs requires that you not follow their pattern. When you do follow their pattern, it doesn’t eliminate bugs, it just reclassifies them.

If we follow the pattern of making our state immutable, which we now understand doesn’t really mean immutable, it means particular instances of that state are immutable but the values meaningful to the program are emitted as copies-with-mutation by special functions like reducers, then yes, this will eliminate the “improper mutation” class of bugs in a formal sense. And it will replace them with “improper emission of an incorrect copy by a broken reducer” bugs.

Redux (even ignoring that it doesn’t stop you from reaching inside the state instances handed to you in the reducers) doesn’t stop you from writing the wrong reducer or dispatching the wrong action. So any idea that it somehow prevents you from incorrectly mutating the application state is obviously mistaken. Since the mechanism of achieving what is needed changes from X to Y, the bugs get reclassified from improper X bugs to improper Y bugs.

This same claim is made about reference semantics. If you force everything to be value semantics, well I’ve seen claims as fantastical as “you’ll never have concurrency issues again”. Plus reference semantics is “hard to reason about” and it creates a bunch of surprising and implicit coupling between far away parts of the program, and that means side effects (another naughty term in FP circles, synonymous with bad) that are not clear when reading part of a program (you see something being changed, who knows who else is referring to that thing and will be affected by the change).

The solution is value semantics, i.e. giving each part of the program its own copy, which ensures they aren’t coupled to each other (no side effects).

Well, okay, but what if they should be coupled to each other? Again, a program with no coupling between any parts is a program that doesn’t do anything interesting. Why are we calling everything a “side” effect? Aren’t some of those just effects? If I take ibuprofen, I don’t call the headache relief a side effect!

And that’s the problem. Value semantics doesn’t automatically eliminate bugs, it reclassifies bugs. After all, if you need coupling, i.e. if it’s correct for A to affect B by mutating X, then how would you do this in FP? The answer is by nesting a bunch of monads inside each other and zipping or otherwise merging together multiple lists to express that one list (representing what one part of the program is doing) is in fact a function of another list (representing what another far away part of the program is doing).

Once you’ve got that mindf*ckery in every place where you need coupling, I’ll bet it’s pretty damn easy to get it wrong. Then guess what: incorrect coupling. You’ve turned “A shouldn’t be coupled to B” into “I flatMapped over the wrong higher order function that produces the wrong list and zipped it into the wrong other list”. Yes, this makes the coupling explicit: you just read the program there and see that A and B are coupled… if you can read any of that in the first place, that is.

What’s more likely is that using value semantics will in fact reduce coupling in your program as intended, and do so far beyond what is correct. You’ll turn “too much coupling” bugs into “not enough coupling” bugs. Specifically, now that you’re passing copies of data around everywhere (that’s the whole point of value semantics, isn’t it?), your “side effects” bugs become “stale data” bugs. You end up with copies you don’t want, because there really should be one source of truth for some data, and you forget to update everyone’s copy.

These kinds of bugs caused by way too much caching (holding copies) of data in GUI apps are pervasive. All the React-ish UI frameworks are designed to prevent them (i.e. forgetting to update your view when state changes, which these new frameworks are supposed to achieve automagically). They don’t accomplish that with value semantics, they accomplish it with observability (i.e. reactivity) on reference-semantics “component state”.

The idea that all coupling is locally explicit might seem nice, but I’ll bet it doesn’t scale at all. There’s tons of (appropriate) coupling in very large, sophisticated applications. I don’t want to have to change tons of places to add a new explicit expression of coupling every time more coupling is added, and then be blasted with all that information every time I’m reading any part of it. That’s actually bad for the level of abstraction. Explicitness is another way of saying “implementation details spelled out”, which is the exact opposite of the direction you want to go in when you scale up software.

Then again, these guys explicitly don’t like encapsulation, so they probably think this is good.

Inappropriate coupling isn’t something I think you can solve with some blanket programming paradigm. It requires careful analysis of the system you’re building, and I think it’s primarily addressed by naming things well. If you’re coupling to something you shouldn’t be, it should hopefully be self-evident by reading the name of the what you’re coupling to. A big part of this is a tendency of coders to name variables after their type instead of what they represent. But this is confusing because it doesn’t tell you what that variable means to the program, and it’s especially bad for reference types because it isn’t telling you what that specific reference means to the entire program. It’s a specific instance that is used in other parts of the program. Instead of calling it theScreenCoords, you should call it primaryCursorScreenCoords, to make it clear it’s a reference to the special instance that means something special. If you follow that rule, hopefully you’ll notice when one class is either inappropriately holding a reference to that instance when it shouldn’t, or it is inappropriately mutating it.

Both OOP and FP are Turing complete language paradigms. Any OOP programming, including all of its bugs caused by mutability and reference semantics, can be translated perfectly into an equivalent FP program that behaves exactly the same, including all those bugs. How is this possible? How would that program have mutability and reference semantics bugs when it’s written in a language that does not have mutability or reference semantics? Because it translates those things into different constructs. Mutable state is transformed into a reducer over a list of inputs that produces a list of the different values that state takes on as the program runs. So mutation bugs get transformed into improper reduction bugs. Reference semantics is transformed into more deeply nested monads of lists that eventually get flatMapd and zipd together. So reference semantics bugs get transformed into improper flatMaping of monads and ziping of lists.

Now, maybe it’s the case that the buggy parts of the OOP program, which look totally innocuous in OOP code, are translated into super convoluted and plainly wrong FP code that no one would write. That’s the hope: that while it isn’t impossible to recreate the undesired behavior of the OOP program, it’s very easy to create it in the OOP language but very hard to create it in the FP language, and when you do, it’s pretty self-explanatory that you did so.

That’s possible in principle, and I don’t buy for a second that it ever works that way in practice.

Every useful program mutates state and requires two distant places to communicate with each other by sharing a reference to something. If the FP way of modeling this is convoluted, then every nontrivial program will be extremely convoluted if written in a FP language. That’s not going to eliminate bugs, it’s going to generate them.

I’m not saying I’m opposed to the FP paradigm. That’s the funny part: I probably bring in functional style constructs (gratuitous use of monadic transforms like map and flatMap on all sorts of types, from collections to optionals to observables, and so on) more than any industry developer I’ve worked with… but I see right through nonsense like “state is the root of all evil” (what could that possibly even mean?).

I just don’t think FP is the One True Way and I think it’s a terrible idea to a restrict a language to only work in that paradigm. I have the same opinion of the OOP paradigm. The problem is actually the “One True Way” part, so it’s funny that I’m reading people telling me that solution is to declare FP the actual One True Way. Why won’t these guys just let go of this search for a silver bullet? Programming Is Hard. You’re not going to get anywhere declaring that every computer program that can ever be created ever can be written with a single tool or concept or approach. We already know what that universal tool is: it’s called a computer, and the language for it is machine language. Everything the software industry has done for the last near-century is a desperate attempt to avoid having to write code with this universal tool.

I very much want a Swiss Army Knife programming language that supports as many paradigms as possible and allows them to interact with each other. This is why I’m such a fan of C++, whose designers share this philosophy. And of course I see endless whining about it for being “too complex” and hear that teams at major companies like Google declare large parts of the language as off limits, fracturing it into endless dialects because having to learn multiple dialects is apparently “easier” than just learning the language (I still have to learn everything because I’m not going to spend my entire career on one team, and additionally I have to learn how each team restricts things and how I’m supposed to do something that I would normally do with some part of the language they ban).

Plus, I mean, anyone suggesting that programming would get easier if we all just wrote Haskell… LOL. Have these guys ever seen Haskell? It’s a fascinating language, meant for language research, not building Microsoft Word, and for that purpose it’s been extremely fruitful, producing several concepts of type theory that eventually made their way into industry languages. Since it’s an extremely abstract research vehicle that requires you to be familiar with a bunch of super abstract math like category theory, the last word in the entire English language I would ever use to describe it is “easy” (for who, the most Asperger’s-y idiot savant who’s ever lived!?).

I should note that there seems to be some overlap of two groups here: one like Joe Armstrong who makes these nonsensical philosophical claims and says FP is the One True Way, and the other who is angry programming languages evolved past the 1970s and think everything should be written in C. They agree that OOP is a “disaster” but I suspect they’d hate each others’ paradigms even more. Addressing the people who want me to write GUI apps in C (which will, I guarantee, result in building an ad-hoc object model with abstraction, inheritance and dynamic dispatch… why do I have to build all that myself when C++ ships with it and its compiler understands it?) is a whole other topic.

Conclusion

These are the key takeaways:

  • When someone says a tool will eliminate an entire class of bugs, that doesn’t imply you’ll have fewer bugs, they’ll just be classified differently.
  • There is no One True Way to write computer software. Carpenters don’t look for one tool to bring to the job, they bring an entire truck full of different tools, each with high specialization, and walk around with an entire toolbelt strapped to their waist.
  • Anyone who genuinely thinks they’re writing computer programs that don’t have state and don’t mutate it are smoking some sh*t I wish I could have found in college.
  • OOP obsession and the languages influenced by it did create a problem of improper modeling of mutability. The solution is to make judicious selection between value and reference types, and in languages where you can’t make custom aggregate value types, use a combination of encapsulation and hand-written copy constructors or copy-mutators to simulate aggregate value types.

I promise at some point, people are going to look at giant apps written with stuff like Redux, freak out and start writing articles saying “FP is Dead, Long Live OOP” (this has already sort of happened with ReactiveX, which is a highly functional paradigm, it got massively overused and misused and now lots of people hate it). It’s going to go right back to where it started, no one’s going to learn the real lesson (stop looking for silver bullets!), and while history may not repeat, it’s going to rhyme.

That cynicism (it’s not so bad if you take the correct approach of just laughing at it) notwithstanding, I think programming languages have made genuine progress recently. Supporting a whole plethora of approaches, including value and reference types, imperative and declarative, procedural, object-oriented and functional, threads and coroutines, etc., lots of advanced work in generics, higher-order type systems and metaprogramming… this is all genuine progress, and this is happening in several languages. I’m sure at every point a group of people are going to be too proud or lazy to learn the new tools and complain about it… don’t be one of them and don’t let them drag you down with them.

At the same time, be prepared to look at a new trendy tool (especially ones that sell themselves as “simple” and work by banning large swaths of techniques that are available elsewhere) skeptically and recognize the patterns of a programming community latching suddenly onto a new concept and become outright drunk over its wild promises, and anticipate the epic hangover that’s about to strike them. In my opinion it’s very rare that a tool or technique gets added to a language or library that’s outright useless. Rather tools and techniques simply get used inappropriately, beyond their range of utility (i.e. hammers aren’t useless, but they’re not good screwdrivers). When entire communities start declaring a widely used tool ought to have never been invented and needs to be removed, that’s when the bender is starting, and that’s when you can bow out so you don’t wake up 3 years later with a pounding headache, no memory of what you did and codebase you can’t believe you thought was a good idea to write.

On Protocol Witnesses

Introduction

So, it’s just a normal day at work, you’re writing some Swift code, and the need arises to model an abstract type: there will be multiple implementations, and you want users to be able to use those implementations without knowing which implementation they are using.

So, of course, you reach for the tool that Swift provides for modeling abstract types: a protocol. If you were writing Kotlin, C#, Java or TypeScript, the comparable tool would be an interface.

As an example, let’s say you’re writing the interface to your backend, which exposes a few endpoints for fetching data. You are going to want to swap out the real or “live” backend for a fake backend during testing, so you’re at least going to need two variations. We’ll therefore write it as a protocol:

protocol NetworkInterfaceProtocol {
  func fetchJobListings() async throws -> [JobListing]

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant]

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing]
}

We’ll write each flavor as a conforming concrete type. The “live” one:

struct NetworkInterfaceLive: NetworkInterfaceProtocol {
  func fetchJobListings() async throws -> [JobListing] {
    let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings")

    guard let response, response.statusCode == 200 else {
      throw BadResponse(response)
    }

    return try JSONDecoder().decode(type: [JobListing].self, from: data ?? .init())
  }

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings/\(listing.id)/applicants")

    guard let response, response.statusCode == 200 else {
      throw BadResponse(response)
    }

    return try JSONDecoder().decode(type: [Applicant].self, from: data ?? .init())
  }

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
    let (data, response) = try await urlSession.data(for: host.appendingPathComponent("applicants/\(applicant.id)/listings")

    guard let response, response.statusCode == 200 else {
      throw BadResponse(response)
    }

    return try JSONDecoder().decode(type:[JobListing].self, from: data ?? .init())
  }

  init(
    urlSession: URLSession = .shared
    host: URL
  ) {
    self.urlSession = urlSession
    self.url = url
  }

  let urlSession: URLSession
  let host: URL
}

And then a fake one that just returns canned successful responses:

struct NetworkInterfaceHappyPathFake: NetworkInterfaceProtocol {
  func fetchJobListings() async throws -> [JobListing] {
    StubData.jobListings
  }

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    StubData.applicants[listing.id]!
  }

  func fetchJobListings(for applicant: Applicant) async throws {
    StubData.applicantListings[applicant.id]!
  }
}

Simple enough, right?

But wait! You start hearing that this isn’t the only way to implement this design. You can, in fact, build abstract types in Swift without using protocols at all! How could this be possible!?

We use what are called “protocol witnesses”. We replace the protocol with a struct, replace function declarations with closure members, and replace the concrete implementations with factories that assign the closures to the implementations provided by that concrete type. First the abstract type:

struct NetworkInterface {
  var fetchJobListings: () async throws -> [JobListing]

  var fetchApplicants: (_ listing: JobListing) async throws -> [Applicant]

  var fetchJobListingsForApplicant: (_ applicant: Applicant) async throws -> [JobListing]
}

Then the live implementation:

extension NetworkInterface {
  static func live(
    urlSession: URLSession = .shared
    host: URL
  ) -> Self {
    func fetchJobListings() async throws -> [JobListing] {
      let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings")

      guard let response, response.statusCode == 200 else {
        throw BadResponse(response)
      }

      return try JSONDecoder().decode(type: [JobListing].self, from: data ?? .init())
    }

    func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
      let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings/\(listing.id)/applicants")

      guard let response, response.statusCode == 200 else {
        throw BadResponse(response)
      }

      return try JSONDecoder().decode(type: [Applicant].self, from: data ?? .init())
    }

    func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
      let (data, response) = try await urlSession.data(for: host.appendingPathComponent("applicants/\(applicant.id)/listings")

      guard let response, response.statusCode == 200 else {
        throw BadResponse(response)
      }

      return try JSONDecoder().decode(type:[JobListing].self, from: data ?? .init())
    }

    return .init(
      fetchJobListings: fetchJobListings,
      fetchApplicants: fetchApplicants,
      fetchJobListingsForApplicant: fetchCandidates(for:)
    )
}

(If you haven’t seen this before, yes you can write “local functions” inside other functions, and they’re automatically closures with default implicit capture, which is how they have access to urlSession and host. If you need to explicitly capture anything you have to switch to writing them as closures, as in let fetchJobListings: () async throws -> [JobListing] = { [...] in ... }).

And the happy path fake:

extension NetworkInterface {
  var happyPathFake: Self {
    .init(
      fetchJobListings: { StubData.jobListings },
      fetchApplicants: { listing in StubData.applicants[listing.id]! },
      fetchJobListingsForApplicant: { applicant in StubData.applicantListings[applicant.id]! }
    )
  }
}

Take a moment to study those to understand that they are, in fact, equivalent. The only difference is that when you want to instantiate a live instance, instead of writing let network: NetworkInterfaceProtocol = NetworkInterfaceLive(url: prodUrl), we write let network: NetworkInterface = .live(url: prodUrl). And similarly when instantiating the happy path fake. Other than that (and the small caveat that you can’t have named function arguments), it’s equivalent.

And, in fact it is more powerful: I can, for example, mix and match the individual functions from different implementations (i.e. make an instance whose fetchJobListings is the happyPathFake one, but the other two functions are live). I can even change the implementation of one function after creating an instance, substituting new implementations inline in other code, like test code, and those functions will close over the context, so I can capture stuff like state defined on my test case file, to make a test double that, say, returns job listings that depends on how I’ve configured the test.

This technique is discussed by PointFree here. I don’t subscribe to their content, so I only see the free portion of this article, and similarly for other articles they link to from there. From this limited vantage point, it appears to me their position is that “protocol oriented programming”, a popular paradigm in the Swift community, is not a panacea, that there are situations where it is not the right tool, and the protocol witness approach can be a better and more powerful alternative. They specifically say that some things are harder to do with protocols than with protocol witnesses, and some things are not possible to do with protocols than can be done with protocol witnesses.

Now, the fundamental starting point of this discussion seems to be that these two options (the protocol with implementing structs, and the struct with settable closure members) are different implementations of the same design. That is, we’re attempting to model the same system, with the same requirements and behavior. And we’re not even debating two different conceptual models of the system. We agree there is an abstract type of network interface (and this, not somewhere else, is where the abstraction lies… this is important) and it has multiple concrete implementations. Rather, we are only comparing two mechanisms of bringing this conceptual model into reality.

As an example of what I’m talking about, here is two different models. This:

struct JobListing {
  let id: String
  let role: String
  let applicants: [Applicant]
  let candidates: [Candidate]
  ...
}

struct Applicant {
  let id: String
  let person: Person
  ...
}

struct Candidate {
  let id: String
  let person: Person
  ...
}

struct Person {
  let id: String
  let firstName: String
  let lastName: String
  ...
}

vs. this:

struct JobListing {
  let id: String
  let role: String
  let applicants: [Applicant]
  let candidates: [Candidate]
  ...
}

struct Applicant {
  let id: String
  let isCandidate: Bool
  let firstName: String
  let lastName: String
  ...
}

These are both attempts to conceptually model the same requirements, but they are different models (i.e. the former allows applicants and candidates to have different attributes, the latter does not). Contrast with the following, which is two implementations, with competing language features, of the same model. This:

struct JobListing {
  let id: String
  let role: String
  var applicants: [Applicant] { ... }
  var candidates: [Candidate] { ... }
  ...
}

vs. this:

struct JobListing {
  let id: String
  let role: String
  func getApplicants() -> [Applicant] { ... }
  func getCandidates() -> [Candidate] { ... }
  ...
}

These both model the domain in the exact same way. The difference is in whether we use the language feature of computed read-only variables vs. functions. That’s purely mechanical.

I believe PointFree are framing this choice of modeling our problem as a protocol with implementing structs, vs. a struct with closure members, as the latter: the same conceptual model but with different tools to construct the model. This is why the discussion focuses on what the language can and can’t do, not the exact nature of the requirements or system, since it is fundamentally about choosing language constructs, not correctly modeling things.

I think this framing is mistaken.

I rather consider the choice over these two implementations to be a discussion over two different conceptual models. This will become clear as I analyze the differences, and I will point out exactly where the differences have implications for the conceptual model of the system we’re building, which goes beyond mere selection of language mechanisms. In the process, we need to ask and satisfactorily answer:

  • What is the nature of this “extra power”, and what are the implications of being able to wield it?
  • What exactly are the things you “can’t” do (or can’t do as easily) with protocols, and why is it you can’t do them? Is it a language defect, something a future language feature might fix?
  • Does the protocol witness design actually eliminate protocols?
  • Why is this struct called a “protocol witness”? (that’s very significant and reveals a lot about what’s going on)

About That Extra Power

One, if not the, fundamental arguments to justify protocol witnesses is that it is “more powerful” than protocols.  Now, based on the part of the article I can see, I have a suspicion this is at least partially based on mistaken beliefs about what you can do with protocols. But there’s at least some truth to this, simply considering the examples they show (which I mentioned above in my own version of this): you can reconfigure individual pieces of functionality in the object, and even compose functionality together in different combinations, where in the protocol -> implementer approach you can’t (well, sort of… we’ll get there). With protocols, the behaviors always come as a set and can’t be mixed and matched, and they can’t be changed later.

This is, indeed, much more “powerful” in the sense you are less restricted in what you can do with these objects.

And that’s bad. Very bad.

“More powerful”, which we can also phrase as “more flexible”, always balances with “less safe”.  Being able to do more in code can very well mean, and usually does mean, you can do more wrong things.

After all, why are these restrictions in place to begin with?  Is it a language defect?  Have we just not figured out how to improve protocols to make them this flexible? Can you imagine a Swift update in which protocols enable you to do this swapping out of individual requirements after initializing a concrete implementing type?

No, it’s the opposite.  Unfettered flexibility is the “stone age” of software programming.  What’s the most flexible code, “powerful” in the sense of “you can implement more behaviors”, you could possibly write?

Assembly.

There, you can do lots of things higher level languages (where even BASIC or C is considered “high level”) won’t let you do.  Some examples are: perform addition on two values in memory that are execution instructions and store the result in another place that is later treated as an instruction, not decrement the stack before jumping to the return address, decrement the stack by an amount that’s not equal to the amount it was incremented originally, and have a for loop increment the index in the middle of an iteration instead of at the end.

These are all things you can’t do in higher level languages.  And thank God for that!  They’re all bugs.  That’s the point of higher level languages being more restricted: they stop you from writing incorrect code, which is the vast majority of code.

See, the main challenge of software engineering is not the inability to write code easily.  It’s the ability to easily write incorrect code.  The precise goal of raising the abstraction level with higher level languages is to restrict you from writing code that’s wrong.  The restrictions are not accidents or unsolved problems.  They are intentional guardrails installed to stop you from flying off the side of the mountain.

This is the point of strongly typed languages.  In JavaScript you can add an integer to a string.  You can’t do this in C.  Is C “missing” a capability?  Is JavaScript “more powerful” than C?  I guess in this sense yes.  But if adding an integer to a string is a programmer error, what is that extra power except a liability?

This is what the “footgun” analogy is about.  Some footguns are very very powerful.  They’re like fully automatic heat-seeking (or maybe foot-seeking?) assault footguns.  And that’s even worse than a single action revolver footgun because, after all, my goal is to not shoot myself in the foot.

While a looser type system or lower level language is “more powerful” at runtime, these languages are indeed less powerful at design time. Assembly is the most powerful in terms of what behavior you can create in the running program, but it is the least powerful in terms of what you can express, at design time, is definitely wrong and should be reported at design time as an error.

There’s no way to express in JavaScript that adding a network client to a list of usernames is nonsense.  There’s no way to express that calling .length on a DOM node is nonsense.  You can express this in Swift, in a way the compiler understands so that it prevents you from doing nonsensical things.  This is more powerful.

So more power at runtime is less power at design time, and vice versa. Computer code is just a sequence of instructions, and the vast vast majority of such sequences are useless or worse. Our goal is not to generate lots of those sequences quickly, it’s to sift through that incomprehensibly giant space of instruction sequences and filter out the garbage ones. And because of the halting problem, running the program to exercise every pathway is not a viable way of doing so.

Is this relevant to this discussion about protocol witnesses?  Absolutely.  All this is doing is turning Swift into JavaScript.  In JavaScript, there are no static classes with fixed functions.  “Methods” are just members of an object that can be called.  “Objects” are just string -> value dictionaries that can hold any values at any “key” (member name).

The only difference between this and the structs PointFree is showing us here is that JavaScript objects are even more powerful still: you can add or remove any functions, at any name, you want during runtime.  How can we make Swift do this?

@dynamicCallable
struct AnyClosure {
  // This will be much better with parameter packs
  init<R>(_ body: () -> R) {
    _call = { _ in body() }
  }

  init<T, R>(_ body: (T) -> R) {
    _call = { args in body(args[0] as! T) }
  }

  init<T1, T2, R>(_ body: (T1, T2) -> R) {
    _call = { args in body(args[0] as! T1, args[1] as! T2) }
  }

  init<T1, T2, T3, R>(_ body: (T1, T2, T3) -> R) {
    _call = { args in body(args[0] as! T1, args[1] as! T2, args[2] as! T3) }
  }

  ...

  @discardableResult
  func dynamicallyCall(withArguments args: [Any]) -> Any {
    _call(args)
  }

  private let _call: ([Any]) -> Any
}

@dynamicMemberLookup
struct NetworkInterface {
  private var methods: [String: AnyClosure]

  subscript(dynamicMember member: String) -> AnyClosure {
    get { methods[member]! }
    set { methods[member] = newValue }
  }
}

In a language that doesn’t have stuff like @dynamicCallable and @dynamicMemberLookup, you can still do this, but you have to settle for ugly syntax: network.fetchApplicants(listing.id) will have to be written as network.method("fetchApplicants").invoke([listing.id]).

With this, we can not only change the implementation of fetchJobListings or fetchApplicants, we can add more methods! Or delete one of those methods. Or change the parameters those methods take, or the type of their return value. Talk about being more powerful!

So that’s even better!  Well, if you consider this added “power” to be a good thing.  I don’t. What’s the point of adding a new method, or even worse changing the parameters of an existing one? It’s not like production code is going to call that new method, or send those new types of parameters in. Well, you might misspell fetchListings as fechListings or forget or reorder parameters, and now that’s a runtime error instead of a compile time error.

I like statically typed languages, and I like them because they restrict me from writing the bugs I can easily write in JavaScript, like calling a method that doesn’t exist, or changing the definition of sqrt to something that doesn’t return the square root of the input.

And this is very controversial.  I’ve met devs who strongly dislike statically typed languages and prefer JavaScript or Ruby because the static type system keeps stopping them from doing what they want to do.  I don’t want to be completely unfair to these devs: it is more work to design types that allow everything you need but also design bugs out of the system.  Rather, it’s more work at first, and then much much less work later.  It’s tempting to pick the “easier now and harder later” option because humans have time preference.

(Again to be fair to them, no static type system in existence today is expressive enough to do everything at compile time that dynamic languages can do at runtime. Macros, and more generally metaprogramming, will hopefully bridge the gap).

What bugs are no longer impossible to write when we use protocol witnesses?  Exercising any of these new capabilities that are just for tests in production code.  You can now swap an individual function out.  You should never do that in production code.  If you do it’s a bug.  If your response to this is “why would anyone ever do that?”, my counter-response is “LOL“.

Indeed this design, by being “more powerful” at runtime, is less powerful at compile time.  I simply can’t express that a flavor of the object exists where the definitions of the two methods can’t vary independently.  With the protocol I can still express that a flavor exists where they can vary independently: make the same witness struct but make it also conform to the protocol.  So I actually have more expressiveness at compile time with the protocol.  I can even say, for example, that one particular function or type only works with one concrete type (like a test that needs the happy path type, I can express that: func runTest(network: NetworkInterfaceHappyPathFake)), or that two parts of code must work with the same type (make it a generic parameter).

I can’t do any of this with protocol witnesses because the compiler has no idea about my types.  It only knows about the abstract type (represented by the witness struct), instead of knowing not only about all the types (the abstract type, as the protocol, and the live concrete type, and the happy path concrete type, etc.) but also their relationship (the latter are all subtypes of the abstract type, expressed by the conformance). So, as it turns out, and specifically because the protocol witness can do things the protocol design can’t do at runtime, the protocol design can do things at compile time the protocol witness design cannot.

“More” or “less” powerful depends on whether you’re looking at compile time or runtime, and one will be the opposite of the other.

These Are Different Models

As I said at the beginning, the very framing here is that these are alternative language mechanisms for the same model. The abstract type and concrete implementing types still exist in the protocol witness code. You just haven’t told the compiler about them, so it can’t enforce any rules related to them.

But whether or not you should be able to mix and match, and by extension swap out, individual functions in the NetworkInterface, is a matter of what system we’re modeling: what exactly the NetworkInterface concept represents, and what relationship, if any, its functions have to each other. Why, after all, are we even putting these three functions in the same type? Why did we decide the correct conceptual model of this system is for fetchJobListings and fetchApplicants(for:) to be instance methods on one type? Why didn’t we originally make three separate protocols, each of which defines only one of these functions?

Well, because they should vary together! Presumably the jobListing you pass into fetchApplicants(for:) is going to be, in fact needs to be, one you previously retrieved from fetchJobListings on the same NetworkInterface instance… or at least an instance of the same type of NetworkInterface. If you grabbed a jobListing from one implementation of NetworkInterface then asked another implementation of NetworkInterface what it’s applicants are, do you think it’s going to be able to tell you?

This means we really should try to express that a particular JobListing type is tied back to a particular NetworkInterface type, and that it is a programmer error that we ideally want to catch at compile time to send a JobListing retrieved from one type of NetworkInterface into another type of NetworkInterface. How would we do that? Definitely not with protocol witnesses. We not only need protocols, we need to exercise more of their capabilities:

protocol NetworkInterfaceProtocol {
  associatedtype JobListing
  associatedtype Applicant

  func fetchJobListings() async throws -> [JobListing]

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant]

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing]
}

This way, each NetworkInterface type has to specify its own JobListing and Applicant types, and (as long as we pick different types, which we should if we want strong typing) it will become a compile time error to try to pass one type of NetworkInterface‘s job listing into another type of NetworkInterface, which we know is not going to produce a sensible answer anyways (it might crash or throw an exception due to not finding a matching job listing, or even worse it might successfully return a wrong result because both backend systems happen to contain a job listing with the same id).

Obviously, then, it’s nonsense to mix and match the individual functions. The whole point of grouping these functions together is that they form a cohesive unit, and the implementation of one needs to “match” the implementation of another. Modeling this in a way where we are allowed to compose different individual functions is just plain wrong.

But if these three functions happened to be totally separate, like let’s say we have separate backends for different resources, they have no relationship to each other (no foreign keys from one to the other, for example), and it should be possible, and might eventually be a production use case, to mix and match different backends, then it would be just plain wrong to model all those functions as being a cohesive unit, incapable of being individually composed.

See, these are different models of a system. Which one is correct depends on what system we’re trying to build. This is not about language mechanics.

Even with the system as it is, where these functions clearly are a cohesive unit… why should NetworkInterface be a protocol? Why should we be able to define two interfaces that have entirely different implementations? Look at what’s defined in the Live implementation: we implement each one by doing an HTTP GET from a particular path added to a shared base endpoint (each one can’t have a separate base URL, they all have to go to the same backend system). Why would we want to replace this entire implementation? Are we going to have a backend that doesn’t use HTTP? If so, yes it makes sense this needs to be abstract. If not… well then what do we expect to vary?

The base URL? Because you have a Development, Staging and Production backend hosted at different URLs?

Well then just make that a parameter of a concrete type. If you want to be really fancy and make it a compile time error to send a Development JobListing into a Staging NetworkInterface, you can make NetworkInterface generic and use that to strongly type the response entities by their environment:

protocol Environment {
  static var baseURL: URL { get }
}

enum Environments {
  enum Development: Environment { static let host = ... } }
  enum Staging: Environment { static let host = ... } }
  enum Production: Environment { static let host = ... } }
}

struct JobListing<E: Environment> {
  ...
}

struct Applicant<E: Environment> {
 ...
}

struct NetworkInterface<E: Environment> {
  func fetchJobListings() async throws -> [JobListing<E>] {
    let (data, response) = try await urlSession.data(for: E.host.appendingPathComponent("listings")

    guard let response, response.statusCode == 200 else {
      throw BadResponse(response)
    }

    return try JSONDecoder().decode(type: [JobListing<E>].self, from: data ?? .init())
  }

  func fetchApplicants(for listing: JobListing<E>) async throws -> [Applicant<E>] {
    let (data, response) = try await urlSession.data(for: E.host.appendingPathComponent("listings/\(listing.id)/applicants")

    guard let response, response.statusCode == 200 else {
      throw BadResponse(response)
    }

    return try JSONDecoder().decode(type: [Applicant<E>].self, from: data ?? .init())
  }

  func fetchJobListings(for applicant: Applicant<E>) async throws -> [JobListing<E>] {
    let (data, response) = try await urlSession.data(for: E.host.appendingPathComponent("applicants/\(applicant.id)/listings")

    guard let response, response.statusCode == 200 else {
      throw BadResponse(response)
    }

    return try JSONDecoder().decode(type:[JobListing<E>].self, from: data ?? .init())
  }

  init(
    urlSession: URLSession = .shared
  ) {
    self.urlSession = urlSession
  }

  let urlSession: URLSession
}

So here, we use protocols, but in a different place: we’re expressing that the variation is not in the network interface itself. There’s only one network interface. The variation is the environment. Making NetworkInterface abstract is not correct because we don’t want that to vary. We’re not going to build a system that connects to anything other than one of these environments, who all have an HTTP backend with identical RESTful APIs. The web protocol, the resource paths, the shape of the responses, none of that varies. Only the environment varies. Not only can we not swap out individual function implementations, we can’t even swap out a network interface. There’s only one concrete type (parameterized by its environment).

In fact… why did we even think to make NetworkInterface abstract to begin with? We don’t even have multiple environments yet!

Ohh, right… testing.

The Interaction of Testing and Design

That’s a weird use case for this. We’re making things abstract specifically so we can break them… if we consider faking to be a breakage, which we should, as our customers certainly would if we accidentally shipped that to them. So then all these extra capabilities, like individually hot-swapping functions… sure, that creates network interfaces that are obviously broken, as any mix-and-matched one would have to be. But that’s the goal: we want to write a test where we can inject fake (a type of broken) behavior into specific parts of the code.

Testing is uniquely challenging in Swift, compared to other industry languages. In other languages the runtime system is dynamic enough that you can mess with objects at runtime by default. This is how you’re able to build mocking frameworks that can take any method on any class and rewrite it while the test is running. Back in Objective-C days we had OCMock. A major pain point in converting ObjC code with tests to Swift is that you can’t do this anymore.

Why is Swift uniquely difficult in this way (it is comparable to C++)? Because it is so much more strongly typed and compile time safe, which also affects how it is compiled. In other languages basically everything is dynamic dispatch, but in Swift a lot of stuff is static dispatch, so there is literally no place for tests to hook into and redirect that dispatch (at runtime at least). To allow a test to redirect something at runtime, you have to write Swift code specifically to abandon some of that compile time safety… or write Swift code that is compile time polymorphic instead of run time polymorphic, a.k.a. generics.

It’s very unfortunate, then, that we’ve introduced the ability to construct broken network interfaces into the production code just so we can do these things in tests. Wouldn’t it be much better if we could isolate this God mode cheat where we can break the invariants to just when the tests run? How might we do that?

Well, first let’s back up a moment here. What are we writing tests for? To prove the system works? To test-drive the features? It’s a popular idea in TDD circles that “testability” should dictate design. Now this evolved out of a belief that “testable design” is really just synonymous for “good design”… that a design that is untestable is untestable because it has design flaws. Testing is therefore doubly valuable because it additionally forces design improvements. Basically, testability reveals a bunch of places where you hardcoded stuff you shouldn’t have (like dependencies, which should be injected because that makes all your code far more reusable anyways).

But that concept can get carried way, to the point that your design becomes a slave to “testability”. You introduce abstractions, the capability for variation, customization, swapping out dependencies, all over the place just so you can finely probe the running system with test doubles. Even though you not only don’t need that variation, it would be fundamentally incorrect for those things to vary, we introduce a capability for variation just so we can construct intentionally broken (not shippable to production) configurations of our code just to run tests against them.

Again, this wasn’t really a concern in industry languages where TDD evolved in, because it’s not even possible to not have the capability for variation literally everywhere (people eventually found out how to mock even ostensibly static calls in Java). C++ devs might have known about it, and Swift brought this issue to the surface for a different audience.

There is a lot of debate over different testing strategies, including whether it’s a good idea in the first place for tests to “see” things customers would never be able to see, or for tests to run against anything other than the exact code that customers are going to use. The argument is simple: the more you screw with the configuration of code just to test it, the less accurate that test will be because no one in the wild is using that configuration. On the other hand, black box testing the exact production build with no special test capabilities or probes inserted is really hard and tends to produce brittle, slow, shallow tests that can’t even reliably put the system into a lot of the initial conditions we want to test.

So it’s really is worth asking ourselves: what exactly do we need to test that requires replacing implementations of NetworkInterface functions with test doubles? After all, this is the interface into a different system that we communicate with over the wire. Can’t we do the interception and substitution at the wire? Can’t we take full control over what responses NetworkInterface is going to produce by controlling the HTTP server at the base URL? Is that maybe a better way to test here, because then we don’t have to make NetworkInterface abstract, because arguably it shouldn’t be, there should not be a NetworkInterface that does anything other than make those specific HTTP calls?

You can do all the mixing, matching and hot swapping you want this way. As long as you can control your HTTP server in your tests, you’re good to go. If you run the server in the test process, you can supply closures that capture state in your test functions.

Okay so this is a pretty specific issue with this specific example. But then again, this is the specific example used to motivate the desire to mix and match and hot swap methods in our network interface. I think if we ignored the testing use case, it would become clear that this is a capability we very much do not want, and then protocol witnesses are plainly the wrong design specifically because they allow this.

But let’s say you really don’t want to spin up a local HTTP server to power your tests. I get it: it’s a pain in the a** to do that, and a heck of a lot easier to just hot-swap the functions. On the other hand, you aren’t exercising your production NetworkInterface, even though it would be nice for your tests to uncover problems in there too. And then it’s possible for your faked implementations to do things the real one simply wouldn’t be able to do. For example, the live implementation can throw a BadRequest error, whatever URLSession.data(for:) can throw, and whatever JSONDecoder.decode can throw. If you swap out a fake function that throws something else, and an explosion occurs… so what? Why does the rest of the code need to prepare for that eventuality even though it would never (and perhaps should never) happen?

Well, if NetworkInterface is a protocol, you can’t be sure that would never happen. After all, by having production code couple to a protocol, it’s coupling to implementations that can do anything. If NetworkInterface were concrete we’d know that isn’t possible, and we’d be wasting time ensuring production code deals with it. Correspondingly, we wouldn’t be able to write a test that throws something else. We could only control the response by controlling what the server returns, which can only trigger one of the errors that live implementation can throw… and we’ll be sure whatever scenario we created is one that can really happen and that we really need to deal with.

And so on… but anyways, you’re just not going to spin up an HTTP server, so can we somehow isolate these special hot-swapping capabilities to just the tests? Yes. To do so we still need to make NetworkInterface a protocol, which makes the production code potentially way more open-ended than we want it to be… but we can try to express that:

  • The entire production code should all use one implementation of NetworkInterface. That is, we shouldn’t be able to switch from one type to another in the middle of the app
  • The only implementation that should be available in production code is the live implementation

The second part is easy: we’re going to use the protocol model, the Live implementation will be in production code, and a Test implementation will be defined in the test suite. The Live implementation will look just like it did originally. The Test one will look like this:

struct NetworkInterfaceTest: NetworkInterfaceProtocol {
  var fetchJobListingsImp: () async throws -> [JobListing]
  func fetchJobListings() async throws -> [JobListing] {
    try await fetchJobListingsImp()
  }

  var fetchApplicantsImp: (_ listing: JobListing) async throws -> [Applicant]
  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    try await fetchApplicantsImp(listing)
  }

  var fetchJobListingsForApplicantImp: (_ applicant: Applicant) async throws -> [JobListing]
  func fetchJobListing(for applicant: Applicant) async throws -> [JobListing] {
    try await fetchJobListingsForApplicantImp(listing)
  }
}

extension NetworkInterfaceTest {
  var happyPathFake: Self {
    .init(
      fetchJobListingsImp: { StubData.jobListings },
      fetchApplicantsImp: { listing in StubData.applicants[listing.id]! },
      fetchJobListingsForApplicantImp: { applicant in StubData.applicantListings[applicant.id]! }
    )
  }
}

See, we’re still using the protocol witness approach, and we’re still building factories for creating specific common configurations, which we can always reconfigure or customize later. But we’re concentrating it in a specific implementation of the protocol. This expresses that in general a NetworkInterface has cohesion among its functions, and they therefore cannot be individually selected. But this individual configuration capability exists specifically in one implementation of NetworkInterface. By defining NetworkInterfaceTest in the test target instead of the prod target, we’re keeping this, and all its added capabilities, out of the production code.

For the first point, since NetworkInterface is a protocol, there’s nothing stopping you from creating new implementations and using them in specific places in production code. Maybe it’s enough to define only the Live one in prod code, but substituting a different (and definitely wrong) one at one specific place (like in a Model for one screen, or component on a screen, buried deep in the structure of the app) would be easy to miss because you’d have to go drill down into that specific place to see the mistake.

Is it not a requirement of the production code that everything uses the same type of network interface? It would always be incorrect to switch from one type to another for one part of the app. Even in tests, aren’t we going to swap in the fake server for everything? Can we somehow express this in the design, to make it a compiler error to mix multiple types? If we could, then picking the wrong type would affect the app everywhere, and that would probably be immediately obvious upon the most trivial testing.

The reason it would be possible to switch network types mid-way is because every UI model stores an instance of the protocol existential, like let network: NetworkInterfaceProtocol, which is really shorthand for let network: any NetworkInterfaceProtocol. That any box is able to store, well, any implementing type, and two different boxes can store two different types. How do we make them store the same type?

With generics.

Instead of this:

final class SomeComponentModel {
  ...

  let otherComponentModel: OtherComponentModel

  private let network: any NetworkInterfaceProtocol
}

final class OtherComponentModel {
  ...

  private let network: any NetworkInterfaceProtocol
}

We do this:

final class SomeComponentModel<Network: NetworkInterfaceProtocol> {
  ...

  let otherComponentModel: OtherComponentModel<Network>

  private let network: Network
}

final class OtherComponentModel<Network: NetworkInterfaceProtocol> {
  ...

  private let network: Network
}

See, the generic parameter links the two network members of the two component models together: they can still vary, we can make component models for any network interface type, but when we select one for SomeComponentModel, we thereby select the same one for OtherComponentModel. Do this throughout all the models in your app, and you express that the entire app structure works with a single type of network interface. You select the type for the entire app, not for each individual component model.

This is an example of “fail big or not at all”.  If you can’t eliminate an error from the design, try to make it a nuclear explosion in your face so you immediately catch and correct it.  The worst kinds of failures are subtle ones that fly under the radar. If your response to this is “just cover everything with tests”, well… I’ve yet to see any GUI app come anywhere close to doing that. Plus if you aren’t categorizing in your mind compilation errors as failed tests, and the type system you create as a test suite, you’re not getting the point of static typing.

Whether this is worth it to you, well that depends. How determined are you to prevent mistakes like creating new network interface types and using them in tucked away parts of the app (is this something you think is appreciably risky?), and how much does making all the types in your app generic bother you (maybe you don’t like the bracket syntax, or you have other aesthetic or design philosophy reasons to object to a proliferation of generics in a codebase)?

I have been steadily evolving for the past 3 years toward embracing generics, and I mean really embracing them: I have no problem with every single type in my app being generic, and having multiple type parameters (if you want to see code that works this way, just look at SwiftUI). I used to find the brackets, extra syntactic boilerplate, and cognitive load of working out constraints (where clauses) alarming or tedious. Then I got used to it, it became second nature to me, and now I see no reason not to. It leads to much more type safe code, and greatly expands the scope of rules I can tell the compiler about, that the compiler then enforces for me. I don’t necessarily think inventing a new network interface for an individual component is a likely bug to come up, but the cost of preventing it is essentially zero, and I additionally document through the design the requirement that the backend selection is app-wide, not per-component.

(The same evolution is happening in my C++ codebases: everything is becoming templates, especially once C++20 concepts showed up).

And this all involves using the two most powerful, expressive, and, in my opinion, important, parts of Swift: protocols and generics.

It’s Not a Choice Over Protocols

Is this “protocol oriented programming”? And if it is, does this mean I believe protocol oriented programming is a panacea? I don’t know, maybe. But the protocol witness design hasn’t removed protocols, it’s just moved them around. The issue isn’t whether to use protocols or not, it’s where they properly belong, which is determined by the correct conceptual model of your system, specifically in what should really be abstract.

Where are the protocols in the protocol witness version? After all, the keyword protocol is nowhere to be found in that code. How can I claim it’s still using protocols?

Because closures are protocols.

What else could the be? They’re abstract, aren’t they? I can’t write let wtf = (() async throws -> [JobListing]).init(). They express a variation: a closure variable holds a closure body, but it doesn’t specify which one. Even the underlying mechanisms are the same. When you call a closure, the compiler has to insert a dynamic dispatch mechanism. That means a witness table (there’s that word “witness”, we’ll get to that later), which lists out the ways a particular instance fulfills the requirements of a protocol.

This is more obvious if we think about how we would implement closures if the language didn’t directly support them. We’d use protocols:

protocol AsyncThrowingCallable0<R> {
  associatedtype R

  func callAsFunction() async throws -> R
}

protocol AsyncThrowingCallable1<T, R> {
  associatedtype T
  associatedtype R

  func callAsFunction(_ arg0: T) async throws -> R
}

struct NetworkInterface {
  var fetchJobListings: any AsyncThrowingCallable0<[JobListing]>

  var fetchApplicants: any AsyncThrowingCallable1<JobListing, [Applicant]>

  var fetchJobListingsForApplicant: any AsyncThrowingCallable1<Applicant, [JobListing]>
}

extension NetworkInterface {
  static func live(
    urlSession: URLSession = .shared
    host: URL
  ) -> Self {
    struct FetchJobListings: AsyncThrowingCallable0 {
      let urlSession: URLSession
      let host: URL

      func callAsFunction() async throws -> [JobListing] {
        let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings")

        guard let response, response.statusCode == 200 else {
          throw BadResponse(response)
        }

        return try JSONDecoder().decode(type: [JobListing].self, from: data ?? .init())
      }
    }

    struct FetchApplicants: AsyncThrowingCallable1 {
      let urlSession: URLSession
      let host: URL

      func callAsFunction(_ listing: JobListing) async throws -> [Applicant] {
        let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings/\(listing.id)/applicants")

        guard let response, response.statusCode == 200 else {
          throw BadResponse(response)
        }

        return try JSONDecoder().decode(type: [Applicant].self, from: data ?? .init())
      }
    }

    struct FetchJobListingsForApplicant: AsyncThrowingCallable1 {
      let urlSession: URLSession
      let host: URL

      func callAsFunction(_ applicant: Applicant) async throws -> [JobListing] {
        let (data, response) = try await urlSession.data(for: host.appendingPathComponent("applicants/\(applicant.id)/listings")

        guard let response, response.statusCode == 200 else {
          throw BadResponse(response)
        }

        return try JSONDecoder().decode(type:[JobListing].self, from: data ?? .init())
      }
    }

    return .init(
      fetchJobListings: FetchJobListings(urlSession: urlSession, host: host),
      fetchApplicants: FetchApplicants(urlSession: urlSession, host: host),
      fetchJobListingsForApplicant: FetchJobListingsForApplicant(urlSession: urlSession, host: host)
    )
}

This is something I think every Swift developer should see at least once, because it shows the underlying mechanism of closures and helps demystify them. We have to implement callability, which we do as a protocol requirement (even if we didn’t have callAsFunction to improve the syntax, we could name the function something like invoke and it still works, we just have to write out invoke to call a closure). We also have to implement capturing, which is fundamentally why these are protocols (whose implementations can be any struct with any amount of instance storage) and not just function pointers.

Now, am I just being pedantic? Can’t I just as well conceive of closures as being function pointers, instead of protocols? No, the specific reason a closure is not just a function pointer is because of capture. I could not keep urlSession and host around and accessible in the live implementation’s methods if they were just function pointers. And what exactly gets captured varies across the implementations.

The key capability of the protocol design is that each implementing type can have its own set of (possibly private) fields, giving each one a different size and layout in memory. The protocol witness itself can’t do this. It’s a struct and its only fields are the methods. Every instance is going to have the exact layout in memory. How, then, can we possibly give the live version more instance fields? By stuffing them inside the captures of the methods, which requires the methods to support variation in their memory layout. The protocoliness of closures is, in fact, crucial to the protocol witness approach working at all.

So, with this clear, we can plainly see that we aren’t choosing protocols vs. no protocols. Rather, we’re choosing one protocol with three requirements at the top vs. three protocols with one requirement (being callable) on the inside. It’s no different than any other modeling problem where you try to work out what the correct way to conceptualize the system you’re building. What parts of it are abstract? Do we have a single abstraction here, or three separate abstractions placed into a concrete aggregate?

If this is your way to avoid being “protocol oriented”, well… I have some bad news for you!

Since we’re on the subject, could we implement either one of these conceptual models (the single abstraction with multiple requirements or the multiple abstractions, each with a single requirement) without any protocols? That might seem plainly impossible. How can we model abstraction without using the mechanism of abstraction that Swift gives us? Well, you can do it, because of course abstraction itself has an implementation, and we can always do that by hand instead of using the language’s version of it.

I really, really hope no one actually suggests this would ever be a good idea. And I’m more nervous about that than you might think because I’ve seen a lot of developers who seem to have forgotten that dynamic dispatch exists and insist on writing their own dispatch code with procedural flow, usually by switching over enums. I hesitate to even show this because I might just be giving them ideas. But if you promise me you’ll take this as educational only and not go start replacing protocols in your code with what you’re about to see… let’s proceed.

This is, of course, how you would model this if you were using a language that simply didn’t have an abstract type system… like C. How would you implement this system in C? Well, that would be a syntactic translation of what you’re about to see in Swift:

enum NetworkInterfaceType {
  case live(urlSession: URLSession, host: URL)
  case happyPathFake
}

struct NetworkInterface {
  let type: NetworkInterfaceType

  func fetchJobListings() async throws -> [JobListing] {
    switch type {
      case let .live(urlSession, host):
        let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings")

        guard let response, response.statusCode == 200 else {
          throw BadResponse(response)
        }

        return try JSONDecoder().decode(type: [JobListing].self, from: data ?? .init())

      case .happyPathFake:
        return StubData.jobListings
    }
  }

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
  switch type {
      case let .live(urlSession, host):
        let (data, response) = try await urlSession.data(for: host.appendingPathComponent("listings/\(listing.id)/applicants")

        guard let response, response.statusCode == 200 else {
          throw BadResponse(response)
        }

        return try JSONDecoder().decode(type: [Applicant].self, from: data ?? .init())

      case .happyPathFake:
        return StubData.applicants[listing.id]!
    }    
  }

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
  switch type {
      case let .live(urlSession, host):
        let (data, response) = try await urlSession.data(for: host.appendingPathComponent("applicants/\(applicant.id)/listings")

        guard let response, response.statusCode == 200 else {
          throw BadResponse(response)
        }

        return try JSONDecoder().decode(type: [JobListing].self, from: data ?? .init())

      case .happyPathFake:
        return StubData.applicantListings[applicant.id]!
    }    
  }
}

For those curious: how would you do this in C, particularly the enum with associated values, something that does not translate directly to C? You would use a union of all the associated value tuples (structs) for each case, and have a plain enum for tracking which value is currently stored in the union (this is basically how enums with associated types are implemented under the hood in Swift).

How would you even add a new test double to this? You’d have to define a new enum case, and add the appropriate switch cases to each method. Yes, you’d have to do this for each and every “concrete implementation” you come up with. The code for every possible implementation of the network interface would all coexist in this giant struct, and in giant methods that cram all those different varying implementations next to each other.

How would you capture state from where you define these other implementations? Ohh… manually, by adding the captured values as associated values of that particular enum case, that you’d then have to pass in by hand. Every variation of state capture would need its own enum case!

Please, please please don’t start doing this, please!

Again, my anxiety here is well founded. I’ve seen plenty of Swift code where an enum is defined whose name ends with Type, it’s added as a member to another type X, and several methods on X are implemented by switching over the enum. If you’ve ever done this… I mean if you’ve ever written an enum whose name is WhateverType and made one a member of the type Whatever, then you’ve invented your own type system. After all, wouldn’t it make more sense to embed the enum inside the other type and remove the redundant prefix?

struct Whatever {
  enum Type {
    ...
  }

  let type: Type
  ...
}

Try it. See what the compiler tells you. Whatever already has an inner typealias named Type, which is the metatype: literally Whatever.Type, that Swift defines for every type you create.

You’re inventing your own type system!

Why you’re doing this instead of using the type system the language ships with… I just don’t know.

There are other ways you could do this that might be slightly less ridiculous than cramming all the bodies of all the implementations of the abstract type next to each other in a single source file, and even in single functions. You could, for example, use function pointers, and pass Any parameters in to handle captures. By that point you’re literally just implementing dynamic dispatch and abstract types.

To be clear, this implements the first design of a single protocol with three requirements. If we wanted to implement the protocol witness this way, we’d need three separate structs with their own Type enums, so they can vary independently.

So… yeah. Good thing we decided to use protocols. I don’t know about you, but I’m very happy we don’t write iOS apps in C.

I do see this as being peripherally related to the protocol witness stuff, particularly the conception of it as a choice over language mechanics, because that is also inventing your own type system. As I pointed out earlier, the abstract type and multiple concrete types still exist. The compiler just doesn’t know about it. You’re still typing things. You’re just doing it without making your conceptual “types” literally types as defined in Swift.

I don’t know why you’d want to invent your own type system, and I doubt there is ever a good reason to. Doing so has very surprising implications, it’s an expert level technique that rapidly gets complicated beyond only the most trivial use cases, and it only shuts off a large part of compile time verification and forces you to do type validation at runtime (and probably fatalError or something on validation failures). If you’re doing this to circumvent the rules of a static type system, like for example that you can’t replace the definition of a type’s function at runtime or construct instances that are stitched together from multiple different types (in other words, static types are static)… well you absolutely should not be doing that, the type system works the way it does for a reason and you should stop trying to break it.

What’s a “Witness” Anyways?

Speaking of inventing your own version of what Swift already gives you… why is this technique called a “protocol witness”? If you Google “Swift” and “witness” you’ll likely encounter discussions about how Swift is implemented, something involving a “witness table”. You may have even seen a mention of such a thing in certain crashes, either the debug message that gets printed or somewhere in the stack trace.

To understand that, let’s think about what happens when we declare a variable of type let network: any NetworkInterfaceProtocol. Now, today, you may or may not have to write any here. Whether you do is based on some rather esoteric history (albeit recent history) about Swift. Basically, if you were allowed to write this at all before Swift 5.7, you don’t have to write any, but you can. If something about the protocol prevented you from using it as a variable type before Swift 5.7, specifically before this proposal was implemented, then you have to write any.

I’m harping on this because it’s of critical importance here. This is the correct way to think about it: the any is always there, and always has been, wherever you use a protocol as a variable type. This just was, and still is in many places, implied by the compiler, so writing it out is optional. After all, the compiler can already tell that a protocol is being used as a variable type, so there’s no syntactic ambiguity by omitting it (similar to how you can omit the type of a variable if it gets initialized inline).

How else can you use a protocol beside as the type of a variable? To declare conformance (i.e. to say NetworkInterfaceLive conforms to NetworkInterfaceProtocol) and in a generic constraint. Those two places involve the protocol itself. That is completely different than the protocol name with any before it. If P is a protocol, then any P is an existential box that holds an instance of any concrete type that implements P.

What is an “existential box”? I don’t want to get too deep into the implementation details of Swift’s type system (I’m writing another article series for that), but just think of it this way: P is abstract, which literally means no variable can have a type P. But there has to be some concrete type, and it has to be static: the type of a variable var theBox: any P can’t change as you put different concrete implementations of P inside it. So the type can’t be whatever concrete type you put in it.

That’s why we have to have a special concrete type, any P, for holding literally any P. Imagine for a moment the compiler just didn’t let you do this. You just aren’t allowed to declare a variable whose type is a protocol. But you need to be able to store any instance that implements a protocol in a variable. What would you do? Let’s say we have the protocol:

protocol MyProtocol {
  var readOnlyMember: Int { get }
  var readWriteMember: String { get set }

  func method1() -> Int
  func method2(param: Int) -> String
}

Now, the point of trying to declare a variable var theBox: MyProtocol is so we can call the requirements, like theBox.readOnlyMember, or theBox.method1(). We need to create a type that lets us do this, but those calls actually dispatch to any implementing instance we want. Let’s try this:

struct AnyMyProtocol {
  var readOnlyMember: Int { readWriteMember_get() }
  var readWriteMember: String { 
    get { readWriteMember_get() }
    set { readWriteMember_set(newValue) }
  }

  func method1() -> Int { method1_imp() } 
  func method2(param: Int) -> String { method2_imp(param) }  

  init<P: AnyMyProtocol>(_ value: P) {
    readOnlyMember_get = { value.readOnlyMember }
   
    readWriteMember_get = { value.readWriteMember }
    readWriteMember_set = { newValue in value.readWriteMember = newValue }

    method1_imp = { value.method1() } 
    method2_imp = { param in value.method2(param: param) } 
  }

  private let readOnlyMember_get: () -> Int

  private let readWriteMember_get: () -> String
  private let readWriteMember_set: (String) -> Void

  private let method1_imp: () -> Int
  private let method2_imp: (Int) -> String
}

What’s happening here is we store individual closures for each of the requirements defined by the protocol (all getters and setters of vars and all funcs). We define a generic initializer that takes an instance of some concrete implementation of P, and we assign all these closures to forward the calls to this implementation.

This is called a type eraser, because that’s exactly what it’s doing. It’s dropping knowledge of the concrete type (whatever the generic parameter P was bound to when the init was called) but preserving the capabilities of the instance. That way, whoever is using the AnyMyProtocol doesn’t know the type of MyProtocol those calls are being forwarded to.

But hold on… this isn’t correct. If you tried compiling this code, you’ll see it failed. Specifically, we’re trying to assign readWriteVar on the value coming into the initializer. But value is a function parameter, and therefore read-only. We need to store our own mutable copy first, and make sure to send all our calls to that copy. We can do that by simply shadowing the variable coming in:

  init<P: AnyMyProtocol>(_ value: P) {
    var value = value

    readOnlyMember_get = { value.readOnlyMember }
   
    readWriteMember_get = { value.readWriteMember }
    readWriteMember_set = { newValue in value.readWriteMember = newValue }

    method1_imp = { value.method1() } 
    method2_imp = { param in value.method2(param: param) } 
  }

What exactly is happening here? Well, when the init is called, we create the local variable, which makes a copy of value. All those closures capture value by reference (because we didn’t explicitly add [value] in the capture list to capture a copy), so we are able to write back to it. Since those closures are escaping, Swift sees that this local variable is captured by reference in escaping closures, which means that variable has to escape too. So it actually allocates that variable on the heap, allowing it to live past the init call. It gets put in a reference counted box, retained by each closure, and the closures are then retained by the AnyMyProtocol instance being initialized. When this instance is discarded, all the closures are discarded, the reference count of this value instance goes to 0, and it gets deallocated.

In a rather convoluted way, this effectively sneaks value into the storage for the AnyMyProtocol instance. It’s not literally inside the instance, it just gets attached to it and has the same lifetime.

Now think about what happens here:

let box1 = AnyMyProtocol(SomeConcreteStruct())
var box2 = box1

box2.readWriteMember = "Uh oh..."

print(box1.readWriteMember)

What gets printed? This: "Uh oh...".

We assigned readWriteMember on box2, and it affected the same member on box1. Evidently AnyMyProtocol has reference semantics, even though the value it’s erasing, a SomeConcreteStruct, has value semantics. This is wrong. When we assign box2 to box1 it’s supposed to make a copy of the SomeConcreteStruct instance inside of box1. But above I explained that the actual boxed value is the var value inside the init, which is placed in a reference counted heap-allocated box to keep it alive as long as the closures that capture it are alive. This has to happen, this value must have reference semantics, because the closures have to share the value. When the readWriteMember_set closure is called and writes to value, that has to be “seen” by a subsequent call to the readWriteMember_get closure.

But while we need the value to be shared among the various closures in a single instance of AnyMyProtocol, we don’t want the value to be shared across instances. How do we fix this?

We have to put the erased value in the AnyMyProtocol instance as a member, and we need that member to be the one closures operate one, which means it needs to be passed into the closures:

struct AnyMyProtocol {
  var readOnlyMember: Int { readWriteMember_get(erased) }
  var readWriteMember: String { 
    get { readWriteMember_get(erased) }
    set { readWriteMember_set(&erased, newValue) }
  }

  func method1() -> Int { method1_imp(erased) } 
  func method2(param: Int) -> String { method2_imp(erased, param) }  

  init<P: AnyMyProtocol>(_ value: P) {
    erased = value

    readOnlyMember_get = { erased in (erased as! P).readOnlyMember }
   
    readWriteMember_get = { erased in (erased as! P).readWriteMember }
    readWriteMember_set = { erased, newValue in 
      var value = erased as! P
      value.readWriteMember = newValue
      erased = value
   }

    method1_imp = { erased in (erased as! P).method1() } 
    method2_imp = { erased, param in (erased as! P).method2(param: param) } 
  }

  private var erased: Any

  private let readOnlyMember_get: (Any) -> Int

  private let readWriteMember_get: (Any) -> String
  private let readWriteMember_set: (inout Any, String) -> Void

  private let method1_imp: (Any) -> Int
  private let method2_imp: (Any, Int) -> String
}

Here we see the appearance of Any. What’s that? It’s Swift’s type erasing box for literally anything. It is what implements the functionality of keep tracking of what’s inside the box and properly copying it when assigning one Any to another. The closures now have what is effectively the self parameter. The closures are going to be shared among copies of the AnyMyProtocol, we can’t change that. So if they’re shared, and we don’t want them to operate on a shared P instance, we have to pass in the particular P instance we want them to operate on.

In fact, these aren’t closures anymore because they aren’t capturing anything. And that’s fortunate, because we’re trying to solve the “Swift doesn’t let you use abstract types as variable types” hypothetical, which would ban closures too. By eliminating capture, these are now just plain old function pointers, which aren’t abstract types.

Now, we can collect these function pointers into a struct:

struct AnyMyProtocol {
  var readOnlyMember: Int { witnessTable.readWriteMember_get(erased) }
  var readWriteMember: String { 
    get { witnessTable.readWriteMember_get(erased) }
    set { witnessTable.readWriteMember_set(&erased, newValue) }
  }

  func method1() -> Int { witnessTable.method1_imp(erased) } 
  func method2(param: Int) -> String { witnessTable.method2_imp(erased, param) }  

  init<P: AnyMyProtocol>(_ value: P) {
    erased = value

    witnessTable = .init(
      readOnlyMember_get: { erased in (erased as! P).readOnlyMember },
      readWriteMember_get = { erased in (erased as! P).readWriteMember },
      readWriteMember_set = { erased, newValue in 
        var value = erased as! P
        value.readWriteMember = newValue
        erased = value,
      method1_imp = { erased in (erased as! P).method1() },
      method2_imp = { erased, param in (erased as! P).method2(param: param) }
     )
  }

  struct WitnessTable {
    let readOnlyMember_get: (Any) -> Int

    let readWriteMember_get: (Any) -> String
    let readWriteMember_set: (inout Any, String) -> Void

    let method1_imp: (Any) -> Int
    let method2_imp: (Any, Int) -> String
  }

  private let erased: Any
  private let witnessTable: WitnessTable
}

The specific WitnessTable instance being created doesn’t depend on anything except the type P, so we can move into an extension on MyProtocol:

extension MyProtocol {
  static var witnessTable: AnyMyProtocol.WitnessTable {
    .init(
      readOnlyMember_get: { erased in (erased as! Self).readOnlyMember },
      readWriteMember_get = { erased in (erased as! Self).readWriteMember },
      readWriteMember_set = { erased, newValue in 
        var value = erased as! Self
        value.readWriteMember = newValue
        erased = value,
      method1_imp = { erased in (erased as! Self).method1() },
      method2_imp = { erased, param in (erased as! Self).method2(param: param) }
    )
  }
}

Then the init is just this:

  init<P: AnyMyProtocol>(_ value: P) {
    erased = value
    witnessTable = P.witnessTable
  }

Does this idea of a table of function pointer members, one for each requirement of a protocol, sound familiar to you?

Hey! This is a protocol witness! “Witness” refers to the fact that the table “sees” the concrete P and its concrete implementations of all those requirements, recording the “proof”, so-to-speak, of those implementations in the form of the function pointers. When someone else comes along and asks, “hey, does you value implement this requirement?”, the witness answers, “yes! I saw that earlier. Here, look at this closure, this is what its implementation is”.

Well, this is exactly what the Swift compiler writes for you, for every protocol that you write. The only difference is that theirs is called any MyProtocol instead of AnyMyProtocol. The compiler creates a witness table for every protocol and uses it in its existential boxes to figure out where to jump to.

At any point an existential box will hold a pointer to a particular witness table, and when you call a method on it, the compiled code goes to the witness table, grabs the function pointer at the right index (depending on what requirement you’re invoking), and then jumps to that function pointer.

The box is, in fact, implementing dynamic dispatch, which always requires some type of runtime lookup mechanism. The members of the witness table are function pointers, which are just the addresses of the first line of the compiled code for the bodies. Calling one just jumps the execution to that address. Every function has a known compile time constant address, so if you want dynamic dispatch, you have to store a function pointer in a variable. That’s what the witness table is.

There are things the compiler can make its box do that we can’t make our box do, and vice versa. The compiler makes its box transparent with respect to casting: we can directly downcast an instance of any P to P1 (where P1 is a concrete implementer of P) and the compiler checks what it has in the box and, if it matches, pulls that out and gives it to us. We can’t make our own box do that, at least not transparently. On the other hand, the compiler never conforms its box to any protocols (not even the protocol being erased: any P does not conform to P, you may have seen compiler errors about this that, they used to be much worse messages like P as a type cannot conform to itself, which is pretty freaking confusing!). You can conform your box to whatever protocols you want.

If we wrote our own existential box for NetworkInterfaceProtocol, it would look like this:

struct AnyNetworkInterface: NetworkInterfaceProtocol {
  func fetchJobListings() async throws -> [JobListing] {
    try await fetchJobListings_imp()
  }

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    try await fetchApplicants_imp(listing)
  }

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
    try await fetchJobListingsForApplicant_imp(applicant)
  }

  init<Erasing: NetworkInterfaceProtocol>(erasing: Erasing) {
    fetchJobListings_imp = { try await erasing.fetchJobListings() } 
    fetchApplicants_imp = { listing in try await erasing.fetchApplicants(for: listing) } 
    fetchJobListingsForApplicant_imp = { applicant in try await erasing.fetchJobListings(for: applicant) } 
  }

  private let fetchJobListings_imp: () async throws -> [JobListings]
  private let fetchApplicants_imp: (JobListing) async throws -> [Applicant]
  private let fetchJobListingsForApplicant_imp: (Applicant) async throws -> [JobListings]
}

// Convenience function, so we can box an instance with `value.erase()` instead of `AnyNetworkInterface(erasing: value)`
extension NetworkInterfaceProtocol {
  func erase() -> AnyNetworkInterface {
    .init(erasing: self)
  }
}

Well this is almost exactly like the Test implementation I showed earlier, isn’t it!?

“Protocol witness” is a reference to the fact this is, for all intents and purposes, a type erasing box. The only difference is the one PointFree shows us is made to be configurable later. We can do that too:

struct ConfigurableAnyNetworkInterface: NetworkInterfaceProtocol {
  func fetchJobListings() async throws -> [JobListing] {
    try await fetchJobListings_imp()
  }

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    try await fetchApplicants_imp(listing)
  }

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
    try await fetchJobListingsForApplicant_imp(applicant)
  }

  init<Erasing: NetworkInterfaceProtocol>(erasing: Erasing) {
    fetchJobListings_imp = { try await erasing.fetchJobListings() } 
    fetchApplicants_imp= { listing in try await erasing.fetchApplicants(for: listing) } 
    fetchJobListingsForApplicant_imp = { applicant in try await erasing.fetchJobListings(for: applicant) } 
  }

  var fetchJobListings_imp: () async throws -> [JobListings]
  var fetchApplicants_imp: (JobListing) async throws -> [Applicant]
  var fetchJobListingsForApplicant_imp: (Applicant) async throws -> [JobListings]
}

extension NetworkInterfaceProtocol {
  func makeConfigurable() -> ConfigurableAnyNetworkInterface{
    .init(erasing: self)
  }
}

With this, we can do something like start off with the Live implementation, put it in a configurable box, then start customizing it:

var network = NetworkInterfaceLive(host: prodHost)
  .makeConfigurable()

network.fetchJobListings_imp = { 
  ...
}

What we’re really doing here is writing our own existential box. That’s what I mean when I say this technique is getting into the territory of creating our own versions of stuff the compiler already creates for us. It’s just a less absurd form of building our own type system with Type enums.

Now, there are reasons why you need to build your own type erasing box. Even Apple does this in several of their frameworks (AnySequence, AnyPublisher, AnyView, etc.). It usually comes down to making the box conform to the protocol it’s abstracting over (AnySequence conforms to Sequence, AnyPublisher conforms to Publisher, AnyView conforms to View, etc.). This is a language limitation, something we expect, or at least hope, will be alleviated in future versions (i.e. allowing extensions of the compiler-provided box: extension any Sequence: Sequence), and sometimes we just need to work around language limitations by doing stuff ourselves the compiler normally does.

(…well, not necessarily. Whether the type erasing box should ever conform to the protocol it abstracts over is not so obvious. Remember how we used a generic to ensure two component models use the same concrete network interface type? If any NetworkInterfaceProtocol automatically counted as a concrete network interface, you could pick that as the type parameter and then you’re able to mix and match, or switch mid-execution. Then what’s the point of making it generic? Maybe what we really need is a way to specify that a generic parameter can be either a concrete type or the existential).

However, writing a type erasing box that you can then start screwing with is not an example of this. This is not a missing language feature. Allowing methods of an any P to be hot-swapped or mix-and-matched would break the existential box. You’d never be sure, when you have an any P, if you have a well-formed instance conforming to P, and everyone has the keys to reach in and break it.

This is why I would only want to expose an implementation of NetworkInterfaceProtocol that allows such violations to tests, and call it Test to make it clear it’s only for use as a test double. Now that’s a fine approach. I’ve actually gone one step further and turned such a Test implementation into a Mock implementation by having it record invocations:

typealias Invocation<Params> = (time: Date, params: Params)

final class NetworkInterfaceMock: NetworkInterfaceProtocol {
  private(set) var fetchJobListings_invocations: [Invocation<()>] = []
  var fetchJobListings_setup: () async throws -> [JobListing]
  func fetchJobListings() async throws -> [JobListing] {
    fetchJobListings_invocations.append((.now, ())
    try await fetchJobListings_setup()
  }

  private(set) var fetchApplicants_invocations: [Invocation<JobListing>] = []
  var fetchApplicants_setup: (_ listing: JobListing) async throws -> [Applicant]
  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    fetchApplicants_invocations.append((.now, listing)
    try await fetchApplicants_setup(listing)
  }

  private(set) var fetchJobListingsForApplicant_invocations: [Invocation<Applicant>] = []
  var fetchJobListingsForApplicant_setup: (_ applicant: Applicant) async throws -> [JobListing]
  func fetchJobListing(for applicant: Applicant) async throws -> [JobListing] {
    fetchJobListingsForApplicant_invocations.append((.now, applicant)
    try await fetchJobListingsForApplicantImp(listing)
  }

  func reset() {
    fetchJobListings_invocations.removeAll()
    fetchApplicants_invocations.removeAll()
    fetchJobListingsForApplicant_invocations.removeAll()
  }
}

This kind of boilerplate is a perfect candidate for macros. Make an @Mock macro and you can produce a mock implementation, that records invocations and is fully configurable from the outside, with as a little as @Mock final class MockMyProtocol: MyProtocol {}. You can probably do the same with the type erasing boxes.

Remember I said earlier that Swift’s compile time safety shut off a lot of easy configurability in tests that all executed at runtime (i.e. rewriting methods)? Well, macros is the solution, where this same level of expressiveness is recovered at compile time.

What Can’t You Do with Protocols?

But let’s rewind a little bit. Do you actually need to create this kind of open-ended type whose behavior you can then change, which is a strange thing to be able to do to any type (changing the meaning of its methods) in order to cover the examples shown?

No. For example, in the case where we want a test to be able to swap in its own implementation of fetchJobListings, we don’t have to make any concrete NetworkInterfaceProtocol whose behavior can change ex-post facto. Instead, we can build transforms that take one type of network interface, and create a new type of network interface with new behavior. The key is that we stick to the usual paradigm of a static type having static behavior. We don’t make a particular instance, of course whose type doesn’t change, dynamic to this degree. We create a new instance of a new type:

struct NetworkInterfaceReplaceJobListings<Base: NetworkInterfaceProtocol>: NetworkInterfaceProtocol {
    func fetchJobListings() async throws -> [JobListing] {
    try await fetchJobListings_imp()
  }

  func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
    try await base.fetchApplicants(for: listing)
  }

  func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
    try await base.fetchJobListings(for: applicant)
  }

  init(
    base: Base,
    fetchJobListingsImp: @escaping () async throws -> [JobListings]
  ) {
    self.base = base
    self.fetchJobListingsImp = fetchJobListingsImp
  }

  private let base: Base
  private let fetchJobListingsImp: () async throws -> [JobListings]
}

extension NetworkInterfaceProtocol {
  func reimplementJobListings(`as` fetchJobListingsImp: @escaping () async throws -> [JobListings]) -> NetworkInterfaceReplaceJobListings<Self> {
    .init(base: self, fetchJobListingsImp: fetchJobListingsImp)
  }
}

...

let network = NetworkInterfaceHappyPathFake()
  .reimplementJobListings { 
    throw TestError()
  }

The key difference here is that the network interface with the swapped out implementation is a different type than the original one. This can interact in interesting ways with the generics system. For example, if you implemented your component models to be generics in order to constrain all component models in your app to always use the same network interface type, then this is ensuring that either the entire app uses the network interface with the swapped out implementation, or no one does.

This is more strongly typed. It expresses something I think is very reasonable: a network interface with a swapped out implementation of fetchJobListings is a different type of network interface. However, there’s still an element of dynamism. Each type we create a new NetworkInterfaceReplaceJobListings instance, we can supply a different reimplementation. Everything else is static, but the jobListings implementation is still instance-level varying. This is clear from the fact the type has a closure member. Closures are abstract, so that’s dynamic dispatch. Can we get rid of that exception and our classes fully static? Can we instead make it so that each specific reimplementation of jobListings produces a distinct type of NetworkInterface?

Yes, but it requires a lot of boilerplate, and we unfortunately lose automatic capture so we have to implement it ourselves. Let’s say in a test we’re calling reimplementJobListings inside a method either for a test, or for test setup:

final class SomeTests: XCTestCase {
  var jobListingsCallCount = 0

  func testJobListingsGetsCalledOnlyOnce() {
    let network = NetworkInterfaceHappyPathFake()
      .reimplementJobListings { [weak self] in
        self?.jobListingsCallCount += 1
        return []
      }

    ...

    XCTAssertEqual(jobListingsCallCount, 1)
  }
}

We can replace this with defining a local type of network interface:

final class SomeTests: XCTestCase {
  var jobListingsCallCount = 0

  func testJobListingsGetsCalledOnlyOnce() {
    struct NetworkInterfaceForThisTest: NetworkInterfaceProtocol {
      func fetchJobListings() async throws -> [JobListing] {
        parent?.jobListingsCallCount += 1
        return []
      }

      func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
        try await base.fetchApplicants(for: listing)
      }

      func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
        try await base.fetchJobListings(for: applicant)
      }

      init(
        parent: SomeTests?
      ) {
        self.parent = parent
      }

      private let base = NetworkInterfaceHappyPathFake()
      private weak var parent: SomeTests?
    }

    let network = NetworkInterfaceForThisTest(parent: self)

    ...

    XCTAssertEqual(jobListingsCallCount, 1)
  }
}

Here, we’re going all the way with “static types are static”, meaning a type’s behavior is statically bound to that type. If we want different behavior in a different test, we make a different type. But having to type all of this out, and deal with capturing (in this case weak self manually) is a lot of tedium. Especially in tests, I probably wouldn’t bother, and would bend the rules of a static type having fixed behavior to avoid all this boilerplate.

What I would love to be able to do, though, is be able to do this fully static approach, but avoid having to invent a throwaway name for this local type, and have it close over its context, using the same syntax as always to specify capture:

final class SomeTests: XCTestCase {
  var jobListingsCallCount = 0

  func testJobListingsGetsCalledOnlyOnce() {
    let network = NetworkInterfaceProtocol { [weak self] in
      func fetchJobListings() async throws -> [JobListing] {
        parent?.jobListingsCallCount += 1
        return []
      }

      func fetchApplicants(for listing: JobListing) async throws -> [Applicant] {
        try await base.fetchApplicants(for: listing)
      }

      func fetchJobListings(for applicant: Applicant) async throws -> [JobListing] {
        try await base.fetchJobListings(for: applicant)
      }

      private let base = NetworkInterfaceHappyPathFake()
    }

    ...

    XCTAssertEqual(jobListingsCallCount, 1)
  }
}

This isn’t a very odd language capability, either. Java and Typescript both support this very thing.

Another minor issue here is performance, which I’ll be very frank, I would be shocked if this ever actually matters for something like an iOS app. But it’s interesting to point it out.

The protocol witness pays various runtime costs, in terms of both memory and CPU usage, because it is fundamentally, and entirely, a runtime solution to the problem of swapping out implementations. First, what is the representation of the protocol witness NetworkInterface in memory? Well, it’s a struct, and it looks to be a pretty small one (just three members, which are closures), so it’s likely to be placed on the stack where it’s a local variable. However, the struct itself isn’t doing anything interesting. The real work happens inside the closure members. Those are all existential boxes for a closure, which as we saw above is a concrete type that holds all the captured state and implements a callAsFunction requirement. Depending on how much gets captured, the instances of those concrete types may or may not fit directly into their type erasing boxes. If they don’t, they’ll be allocated on the heap and the box will store a pointer to its instance. This will result in runtime costs of pointer indirection, heap allocation and cache invalidation.

When methods are called, the closure members act as a thunk to the body of the closure, so that’s going to be another runtime cost of pointer indirection.

Contrast that with the first approach shown above (which is really an example of the Proxy Pattern), where the static typing is much stronger. The type that we end up with is a NetworkInterfaceReplaceJobListings<NetworkInterfaceHappyPathFake>. Notice the way the proxy type retains information about the original type that it is proxying. In particular, it does not erase this source type. Furthermore, NetworkInterfaceHappyPathFake is a static type, not a factory that constructs particular instances.

The implication of this is that the network variable can never (even if it was made var) store another type of network interface. We can’t change the definitions of any of the functions on this variable at any point in its life. That means it is known at compile time what the precise behavior is, except for the closure provided as the reimplementation of fetchJobListings. The fact that, for example, the other two calls just call the happy path fake version, is known at compile time. It is known at compile time that the base member is a NetworkInterfaceHappyPathFake. The size of this member, and the closure member, is known at compile time. If it’s small enough it can be put on the stack. There is no runtime dispatch of any of the calls, except for the closure.

If we go to the fully static types where we define new ones locally, we eliminate the one remaining runtime dispatch of the closure, and literally everything is hardwired at compile time.

The cost is all paid at compile time. The compiler looks at that more complex nested/generic type and figures out, from that, how to wire everything up hardcoded. This the difference, in terms of runtime performance, between resolving the calls through runtime mechanisms as in the protocol witness, and resolving the calls through compile mechanisms of generics.

(Caveat: when you call generic code in Swift, supplying specific type parameters, the body of the generic code can be compiled into a dedicated copy for that type parameter, with everything hardwired at compile time, and there will be no runtime cost, but only if the compiler has access to that source code during compilation of your code that calls it, which is generally true only if you aren’t crossing module boundaries. If you do cross a module boundary, when the compiler compiled the module with the generic code, it compiled an “erased” copy of the generic code that replaces the generic parameter with an existential and dynamic-dispatches everything. That’s the only compiled code your module will be able to invoke, and you’ll end up paying runtime costs).

Again, I’m sure this will never matter in an iOS app. We used to write apps in Objective-C, where everything is dynamic dispatch (specifically message passing, the slowest type), on phones half the speed (or less) of what we write them on now. I rather think it’s interesting to point out the trivial improvement in runtime performance (and corresponding, probably also trivial, degradation of compile time performance) of the strongly typed implementation because it further illustrates that the behavior of the program is being worked out at compile time… and it therefore does more validation, and rejection of invalid code, at compile time.

These kinds of techniques where you start building up more sophisticated types, typically with some kind of type composition (through generic parameters), of protocols, with the goal of eliminating runtime value-level (existential) variation and try to express the variation on the type level, is where the power of protocols can really yield fruit, especially in terms of expanding your thinking about what they can do. It’s easy to just give up and say “this can’t be done with protocols or at the type level”, but you should always try. You might be surprised what you can do, and even if you revert to existentials later, you’ll probably learn something useful.

Conclusion

So, do I think you should ever employ this struct witness pattern?

Well, that depends on what it means exactly.

As a refactor of a design with protocols on the basis that it works around language limitations? No, that’s fundamentally confused: those are not language limitations, that’s called a static type system, and if you’re going to throw that away for dynamic typing at least frame it honestly and accurately. Then do your best to convince me dynamic typing is better than static typing (good luck).

What about if we realize those individual functions are where the abstractions should be, because it is correct modeling of the system we’re building to let them vary independently? Well, in that case, the question is: should those members be just closures, or should you define protocols with just one function as their requirements? For example, if you define fetchJobListings to simply be any () async throws -> [JobListing] closure, to me this communicates that any function that has that signature is acceptable. I could have two such functions, both defined as mere closures, but they mean different things and it’s a programmer error to assign one to another. If I introduce two protocols, each of which having a single function requirement, well first I can name that function, thereby indicating what the meaning of this function is. Second, it’s strongly typed: the compiler won’t let me use one where another is expected.

So even in this case, I would want to think carefully about whether closures are sufficient, or if I want to have stronger typing than this and instead define a protocol that implements callAsFunction. Being as biased toward strong typing as I am, it’s likely I’ll choose to write out protocols. That extra boilerplate? The names of those protocols, and possibly the names of their one function requirement? I want that. Terseness has never been my goal. If it were I’d name my variables things like x or y1.

As a hand-written type eraser, intending to be a replacement for the language-provided existential where I need more flexible behavior? Never, I would consider that to be breaking the existential by enabling it to circumvent and violate the static type system.

To implement test doubles? Yes I’d do something that’s effectively the same as a protocol witness, but I wouldn’t replace the protocol with this, I would add to the protocol based design by having this witness implement the protocol.

So, ultimately, as it is presented: no, I never would, and I would consider it to be broadly in the same category as the style of coding where you define your own TheThingType enums that appear as an instance member in a type TheThing, which is a bad style of Swift that tries to replace the language’s type system with a homegrown type system that, however good or even better (which I doubt it will be) it is, will never be verified by the compiler, and that’s a hard dealbreaker for me.

Where might you see me writing code that involves simple structs with a closure member where I then create a handful of different de-facto “types” by initializing the closure in a specific way for each one? In prototyping. Like I’m scaffolding out some code, it’s early and I’m not sure about the design, and because it’s less boilerplate, whipping up that struct is just a little bit faster than writing out the protocol and conforming type hierarchy. Once I’m more sure this abstract type is here to stay, I’m almost certainly going to refactor it to a protocol with the closure member becoming a proper function.

If I can tie together all my decisions regarding this into a single theme, it is: I completely, 100% favor compile time safety over runtime ease or being able to quickly write code without restriction. Because perhaps my central goal of design is to elevate as many programmer errors as possible into compilation failures, and because generally the way to do that is to use statically typed languages and develop a strong (meaning lots of fine-grained) type system, I immediately dislike the protocol witness approach because it degrades the type system that the compiler sees. My goal is not and has never been to avoid or minimize the boilerplate that defining more types entails.

If you’re interested in pursing this style of programming, where you are trying to reject as much invalid code as possible at compile time, my #1 advice, if you’re working in Swift, is to embrace generics and spend time honing your skills with protocols, especially the more advanced features like associated types. If there’s a single concrete goal to drive this, try your best to eliminate as many protocol existentials in your code base as possible (this will almost always involve replacing them with generics). As part of this, you have to treat closures as existentials (which, fundamentally, they are).

You will get frustrated at times, and probably overwhelmed. Run into the challenge, not away. You’ll be happy you did later.

In a follow-up article I will explore a more nontrivial conceptual model of an abstract type with concrete implementations, and what happens (specifically what breaks down, especially related to compile time safety) if you try to build it will protocol witnesses.
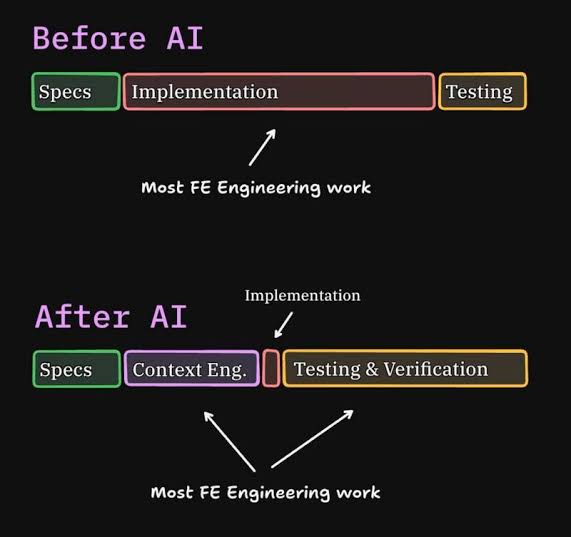
Testing Async Code

Introduction

By now, pretty much every major modern OOP language has gained async/await. Java is the odd man out (they have a very different way of handling lightweight concurrency).

So, you go on a rampage, async-ifying all the things, and basking in the warm rays of the much more readable and naturally flowing fruits of your labor. Everything is fine, everything is good.

Then you get to your tests.

And suddenly you’re having lots of problems.

What’s the issue, exactly? Well, it isn’t async code per se. In fact, usually the test frameworks that are used with each language support test methods that are themselves async. If you want to test an async method, simply make the test method async, call the async method you’re testing, and await the result. You end up with what is functionally the same test as if everything were synchronous.

But what if the async code you want to test isn’t awaitable from the test?

Async vs. Await

This is a good time to review the paradox that async and await are almost antonyms. Asynchrony allows for concurrency: by not synchronizing two events, other stuff is able to happen between the two events. But adding async to code just allows you to await it. “Waiting” means to synchronize with the result: don’t continue executing below the await until the result is ready. What exactly is “asynchronous” about that?

Let’s look at an example async method:

func doSomeStuff() async -> String {

  let inputs = Inputs(5, "hello!", getSomeMoreInputs())

  let intermediateResult = await processTheInputs()

  let anotherIntermediateResult = await checkTheResultForProblems()

  logTheResults(anotherIntermediateResult)

  await save(result: anotherIntermediateResult)

  return "All done!"
}

Asynchrony appears in three places (where the awaits are). And yet this code is utterly sequential. That’s the whole point of async-await language features. Writing this code with callbacks, while functionally equivalent, obscures the fact that this code all runs in a strict sequence, with the output of one step being used as the input to later steps. Async-await restores the natural return-value flow of code while also allowing it to be executed in several asynchronous chunks.

So then why bother making stuff async and awaiting it? Why not just make the functions like processTheInputs synchronous? After all, when you call a regular old function, the caller waits for the function to return a result. What’s different?

The answer is how the threads work. If the function were synchronous, one thread would execute this from beginning to end, and not do anything else in the process. Now if the functions like processTheInputs are just crunching a bunch of CPU instructions, this makes sense, because the thread keeps the CPU busy with something throughout the entire process. But if the function is asking some other thread, possibly in some other process or even on another machine, to do something for us, our thread has nothing to do, so it has to sit there and wait. You typically do that, ultimately, by using a condition variable: that tells the operating system this thread is waiting for something and not to bother giving it a slice of CPU time.

This doesn’t waste CPU resources (you aren’t busy waiting), but you do waste other resources, like memory for the thread’s stack. Using asynchrony lets multiple threads divide and conquer the work so that none of them have to sit idle. The await lets the thread go jump to other little chunks of scheduled work (anything between two awaits in any async function) while the result is prepared somewhere else.

Okay, but this is a rather esoteric implementation detail about utilizing resources more efficiently. The code is logically identical to the same method with the async and awaits stripped out… that is, the entirely synchronous flavor of it.

So then why does simply marking a method as async, and replacing blocking operations that force a thread to go dormant with awaits that allow the thread to move onto something else, and a (potentially) different thread to eventually resume the work, suddenly make testing a problem?

It doesn’t. Just add async to the test method, and add await to the function call. Now the test is logically equivalent to the version where everything is synchronous.

The problem is when we introduce concurrency.

The Problem

How do we call async code? Well, if we’re already in an async method, we can just await it. If we’re not in an async method, what do we do?

It depends on the language, but in some way or another, you start a background task. Here, “background” means concurrency: something that happens “in the background”, meaning it hums along without interfering with whatever else you want to do in the mean time. In .NET, this means either calling an async function that returns a Task but not awaiting it (which causes the part of the task before the first suspension to run synchronously), or calling Task.Run(...) (which causes the entire part of the task to run concurrently). In Swift, it means calling Task {...}. In Kotlin, it means calling launch { ... }. In Javascript, similar to .NET, you call an async function that returns a Promise but don’t await it, or construct a new Promise that awaits the async function then resolves itself (and, of course, don’t await this Promise).

That’s where the trouble happens.

This is how you kick off async code from a sync method. The sync method continues along, while the async code executes concurrently. The sync method does not wait for the async code to finish. The sync code can, and often will, finish before the async code does. We can also kick off concurrent async work in an async method, the exact same way. In this case we’re allowed to await the result of this concurrent task. If we do, then the outer async function will only complete after that concurrent work completes, and so awaiting the outer function in a test will ensure both streams of work are finished. But if the outer function only spawns the inner task and doesn’t await it, the same problem exists: the outer task can complete before the inner task does.

Let’s look at an example. You create a ViewModel for a screen in your app. As soon as it gets created, in the init, it spawns a concurrent task to download data from your server. When the response comes in, it is saved to a variable that the UI can read to build up what it will display to the user. Before it’s ready, we show a spinner:

@MainActor
final class MyViewModel: ObservableObject {
  @Published
  var results: [String]?

  init() {
    Task {
      let (data, response) = try await urlSession.data(for: dataRequest)

      try await MainActor.run {
        self.results = try JSONDecoder().decode([String].self, from: data)
      }
    }
  }
}

struct MyView: View {
  @ObservedObject var viewModel: MyViewModel = .init()

  var body: some View {
    if let results = model.result {
      ForEach(results, id: \.self) { result in 
        Text(result)
      }
    } else {
      ProgressView()
    }
  }
}

You want to test that the view model loads the results from the server and stores them in the right place:

final class MyViewModelTests: XCTestCase {
  func testLoadData() {
    let mockResults = setupMockServerResponse()

    let viewModel = MyViewModel()

    XCTAssertEqual(viewModel.results, mockResults)
  }
}

You run this test, and it passes… sometimes. Sometimes it fails, complaining that viewModel.results is nil. It’s actually kind of surprising that it ever passes. The mock server response you set up can be fetched almost instantaneously, it doesn’t have to actually call out to a remote server, so the Task you spin off the init completes in a few microseconds. It also takes a few microseconds for the thread running testLoadData to get from the let viewModel = ... line to the XCTAssertEqual line. The two threads are racing against each other: if the Task inside the init wins, the test passes. If not, it fails, and viewModel.results will be nil because that’s the initial value and it didn’t get set by the Task yet.

Do we fix this by making things async? Let’s do this:

@MainActor
final class MyViewModel: ObservableObject {
  @Published
  var results: [String]?

  init() async throws {
    let (data, response) = try await urlSession.data(for: dataRequest)

    try await MainActor.run {
      self.results = try JSONDecoder().decode([String].self, from: data)
    }
  }
}

...

final class MyViewModelTests: XCTestCase {
  func testLoadData() async throws {
    let mockResults = setupMockServerResponse()

    let viewModel = try await MyViewModel()

    XCTAssertEqual(viewModel.results, mockResults)
  }
}

Now it passes every time, and it’s clear why: it’s now the init itself that awaits the work to set the results. And the test is able to (in fact it must) await the init, so we’re sure this all completes before we can get past the let viewModel = ... line.

But the view no longer compiles. We’re supposed to be able to create a MyView(), which creates the default view model without us specifying it. But that init is now async. We would have to make an init() async throws for MyView as well. But MyView is part of the body of another view somewhere, and that can’t be async and so can’t await this init.

Plus, this defeats the purpose of the ProgressView. In fact, since results is set in the init, we can make it a non-optional let, never assigning it to nil. Then the View will always have results and never need to show a spinner. That’s not what we want. Even if we push the “show a spinner until the results are ready” logic outside of MyView, we have to solve that problem somewhere.

This is a problem of concurrency. We want the spinner to show on screen concurrent with the results being fetched. The problem isn’t the init being async per se, it’s that the init awaits the results being fetched. We can keep the async on the init but we need to make the fetch concurrent again:

@MainActor
final class MyViewModel: ObservableObject {
  @Published
  var results: [String]?

  init() async throws {
    Task {
      let (data, response) = try await urlSession.data(for: dataRequest)

      try await MainActor.run {
        self.results = try JSONDecoder().decode([String].self, from: data)
      }
    }
  }
}

...

final class MyViewModelTests: XCTestCase {
  func testLoadData() async throws {
    let mockResults = setupMockServerResponse()

    let viewModel = try await MyViewModel()

    XCTAssertEqual(viewModel.results, mockResults)
  }
}

Now we’re back to the original problem. The async on the init isn’t helping. Sure we await that in the test, but the thing we actually need to wait for is concurrent again, and we get the same flaky result as before.

This really has nothing to do with the async-await language feature per se. The exact same problem would have arisen had we achieved our desired result in a more old school way:

@MainActor
final class MyViewModel: ObservableObject {
  @Published
  var results: [String]?

  init() {
    DispatchQueue.global().async { // This really isn't necessary, but it makes this version more directly analogous to the async-await one
            
      URLSession.shared.dataTask(with: .init(url: .init(string: "")!)) { data, response, _ in
        guard let data, let response else {
          return
        }
                
        DispatchQueue.main.async {
          self.results = try? JSONDecoder().decode([String].self, from: data)
        }
      }
    }
  }
}

There’s still no way for the test to wait for that work thrown onto a background DispatchQueue to finish, or for the work to store the result thrown back onto the main DispatchQueue to finish either.

So what do we do?

The Hacky “Solution”

Well, the most common way to deal with this is ye old random delay.

We need to wait for the spun off task to finish, and the method we’re calling can finish slightly earlier. So after the method we call finishes, we just wait. How long? Well, for a… bit. Who knows. Half a second? A tenth of a second? It depends on the nature of the task too. If the task tends to take a couple seconds, we need to wait a couple seconds.

final class MyViewModelTests: XCTestCase {
  func testLoadData() async throws {
    let mockResults = setupMockServerResponse()

    let viewModel = MyViewModel()

    try await Task.sleep(0.2) // That's probably long enough!

    XCTAssertEqual(viewModel.results, mockResults)
  }
}

(Note that Task.yield() is just another flavor of this, it’s just causing the execution to pause for some indeterminate brief amount of time)

To be clear, this “solves” the problem no matter what mechanism of concurrency we decided to use: async-await, dispatch queues, run loops, threads… doesn’t matter.

Whatever the delay is, you typically discover it by just running the test and seeing what kind of delay makes it usually pass. And that works… until random fluctuations in the machine running the tests make it not work, and you have to bump the delay up slightly.

That, ladies and gentlemen, is how you get brittle tests.

Is This a Solution?

The problem is that by adding a delay and then going ahead with our assertions as though the task completed in time, we’re encoding into our tests a requirement that the task complete within the time we chose. The time we chose was utterly random and tuned to make the test pass, so it’s certainly not a valid requirement. You don’t want tests that inadvertently enforce nonexistent requirements.

I’ve heard some interesting takes on this. Well, let’s think about the requirements. Really, there is a requirement that mentions a time window. After all, the product owner wouldn’t be happy if this task completed 30 minutes after the sync method (the “when” of the scenario) got triggered. The solution, according to this perspective, is to sit down with the product owner, work out the nonfunctional requirements regarding timing constraints (that this ought to finish in no more than some amount of time), and voilà: there’s your delay amount, and now your tests are enforcing real requirements, not made up ones.

But hold on… why must there be a nonfunctional requirement about timing? This is about a very technical detail in code that concerns how threads execute work on the machine, and whether it’s possible for the test method to know exactly when some task that got spun off has finished. Why does this implementation detail imply that a NFR about timing exists? Do timing NFRs exist for synchronous code? After all, nothing a computer does is instantaneous. If this were true, then all requirements, being fundamentally about state changes in a computer system, would have to mention something about the allowed time constraints for how long this state change can take.

Try asking the product owner what the max allowed time should be. Really, ask him. I’ll tell you what his answer will be 99% of the time:

“Uhh, I don’t know… I mean, as short as it can be?”

Exactly. NFRs are about tuning a system and deciding when to stop optimizing. Sure, we can make the server respond in <10ms, but it will take a month of aggressive optimization. Not worth it? Then you’ll get <100ms. The reason to state the NFR is to determine how much effort needs to be spent obtaining realistic but nontrivial performance.

In the examples we’re talking about with async methods, there’s no question of optimization. What would that even mean? Let’s say the product owner decides the results should be ready in no more than 10 seconds. Okay, first of all, that means this test has to wait 10 seconds every time it runs! The results will actually be ready in a few microseconds, but instead every test run costs 10 seconds just to take this supposed NFR into account. It would be great if the test could detect that the results came in sooner that the maximum time and go ahead and complete early. But if we could solve that problem, we’d solve the original problem too (the test knowing when the results came in).

Even worse, what do we do with that information? The product owner wants the results in 10ms, but the response is large and it takes longer for the fastest iPhone to JSON decode it. What do we do with this requirement? Invent a faster iPhone?

Fine, then the product owner will have to take the limitations of the system into account when he picks the NFR. Well now we’re just back to “it should be as fast as it reasonably can”. So, like, make the call as early as possible, then store the results as soon as they come in.

The Real Requirements

The requirement, in terms of timing, is quite simply, that the task get started immediately, and that it finish as soon as it can, which means that the task only performs what it needs to, and nothing else.

These are the requirements we should be expressing in our tests. We shouldn’t be saying “X should finish in <10 s”, we should be saying “X should start now, and X should only do A, B and C, and nothing else”.

The second part, that code should only do something, and not do anything else, is tricky because it’s open-ended. How do you test that code only does certain things? Generally you can’t, and don’t try to. But that’s not the thing that’s likely to “break”, or what a test in a TDD process needs to prove got implemented.

The first part… that’s what our tests should be looking for… not that this concurrent task finishes within a certain time, but that it is started immediately (synchronously!). We of course need to test that the task does whatever it needs to do. That’s a separate test. So, really, what starts off as one test:

Given some results on the server
When we create a view model
Then the view model’s results should be the server’s results

Ends up as two tests:

When we create the view model
Then the “fetch results” task should be started with the view model

Given some results on the server
And the “fetch results” task is running with the view model
When the “fetch results” finishes
Then the view model’s results should be the server’s results

I should rather say this ended up as two requirements. Writing two tests that correspond exactly to these two tests is a more advanced topic that I will talk about another time so it doesn’t distract too much from the issue here.

For now let’s just try to write a test that indeed tests both of these requirements together, but still confirms that the task does start and eventually finish, doing what it is supposed to do in the process, without having to put in a delay.

Solution 1: Scheduler Abstraction

The fundamental problem is that a async task is spun off concurrently, and the test doesn’t have access to it. How does that happen? By initializing a Task. This is, effectively, how you schedule some work to run concurrently. By writing Task.init(...), we are hardcoding this schedule call to the “real” scheduling of creating a Task. If we can abstract this call, then we can substitute test schedulers that allow us more capabilities, like being able to see what was scheduled and await all of it.

Let’s look at the interface for Task.init:

struct Task<Success, Failure: Error> {

}

extension Task where Failure == Never {

  @discardableResult
  init(
    priority: TaskPriority? = nil, 
    operation: @Sendable @escaping () async -> Success
  )
}

extension Task where Failure == Error {

  @discardableResult
  init(
    priority: TaskPriority? = nil, 
    operation: @Sendable @escaping () async throws -> Success
  )
}

There are actually some hidden attributes that you can see if you look at source code for this interface. I managed to catch Xcode admitting to me once that these attributes are there, but I can’t remember how I did it and can no longer reproduce it. So really this is the interface:

extension Task where Failure == Never {

  @discardableResult
  @_alwaysEmitIntoClient
  init(
    priority: TaskPriority? = nil, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async -> Success
  )
}

extension Task where Failure == Error {

  @discardableResult
  @_alwaysEmitIntoClient
  init(
    priority: TaskPriority? = nil, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async throws -> Success
  )
}

Okay, so let’s write an abstract TaskScheduler type that presents this same interface. Since protocols don’t support default parameters we need to deal with that in an extension:

protocol TaskScheduler {
  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    priority: TaskPriority?, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async -> Success
  ) -> Task<Success, Never>

  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    priority: TaskPriority?, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async throws -> Success
  ) -> Task<Success, Error>
}

extension TaskScheduler {
  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async -> Success
  ) -> Task<Success, Never> {
    schedule(priority: nil, operation: operation)
  }

  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async throws -> Success
  ) -> Task<Success, Error> {
    schedule(priority: nil, operation: operation)
  }
}

Now we can write a DefaultTaskScheduler that just creates the Task and nothing else:

struct DefaultTaskScheduler: TaskScheduler {
  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    priority: TaskPriority?, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async -> Success
  ) -> Task<Success, Never> {
    .init(priority: priority, operation: operation)
  }

  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    priority: TaskPriority?, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async throws -> Success
  ) -> Task<Success, Error> {
    .init(priority: priority, operation: operation)
  }
}

And we can introduce this abstraction into MyViewModel:

@MainActor
final class MyViewModel: ObservableObject {
  @Published
  var results: [String]?

  init(taskScheduler: some TaskScheduler = DefaultTaskScheduler()) {
    taskScheduler.schedule {
      let (data, response) = try await urlSession.data(for: dataRequest)

      self.results = try JSONDecoder().decode([String].self, from: data)
    }
  }
}

Now in tests, we can write a RecordingTaskScheduler decorator that records all tasks scheduled on some other decorator, and lets us await them all later. In order to do that, we need to be able to store tasks with any Success and Failure type. Then we need to be able to await them all. How do we await a Task? By awaiting its value:

extension Task {
  public var value: Success {
    get async throws
  }
}

extension Task where Failure == Never {
  public var value: Success {
    get async
  }
}

In order to store all running Tasks of any success type, throwing and non-throwing, and to be able to await their values, we need a protocol that covers all those cases:

protocol TaskProtocol {
  associatedtype Success

  public var value: Success {
    get async throws
  }
}

extension Task: TaskProtocol {}

Now we can use this in RecordingTaskScheduler:

final class RecordingTaskScheduler<Scheduler: TaskScheduler>: TaskScheduler {
  private(set) var runningTasks: [any TaskProtocol] = []

  func awaitAll() async throws -> {
    // Be careful here.  While tasks are running, they may schedule more tasks themselves.  So instead of looping over runningTasks, we need to keep repeatedly pull off the next one if it's there.
    while !running tasks.isEmpty {
      let task = runningTasks.removeFirst()
      _ = try await task.value
    }
  }

  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    priority: TaskPriority?, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async -> Success
  ) -> Task<Success, Never> {
    let task = scheduler.schedule(priority: priority, operation: operation)
    runningTasks.append(task)
    return task
  }

  @discardableResult
  @_alwaysEmitIntoClient
  func schedule<Success>(
    priority: TaskPriority?, 
    @_inheritActorContext @_implicitSelfCapture operation: __owned @Sendable @escaping () async throws -> Success
  ) -> Task<Success, Error> {
    let task = scheduler.schedule(priority: priority, operation: operation)
    runningTasks.append(task)
    return task
  }

  init(scheduler: Scheduler) {
    self.scheduler = scheduler
  }

  let scheduler: Scheduler
}

extension TaskScheduler {
  var recorded: RecordingTaskScheduler<Self> {
    .init(scheduler: self)
  }
}

You probably want to make that runningTasks state thread safe.

Now we can use this in the test:

final class MyViewModelTests: XCTestCase {
  func testLoadData() async throws {
    let mockResults = setupMockServerResponse()

    let taskScheduler = DefaultTaskScheduler().recorded
    let viewModel = MyViewModel(taskScheduler: taskScheduler)

    try await taskScheduler.awaitAll()

    XCTAssertEqual(viewModel.results, mockResults)
  }
}

We’ve replaced the sleep for an arbitrary time with a precise await for all scheduled tasks to complete. Much better!

Now, there are other ways to schedule concurrent work in Swift. Initializing a new Task is unstructured concurrency: creating a new top-level task that runs independently of any other Task, even if it was spawned an async function being run by another Task. The other ways to spawn concurrent work are the structured concurrency APIs: async let and with(Throwing)TaskGroup. Do we need to worry about these causing problems in tests?

No, we don’t. The consequence of the concurrency being structured is that these tasks spawned inside another Task are owned by the outer Task (they are “child tasks” of that “parent task”). This primarily means parent tasks cannot complete until all of their child tasks complete. It doesn’t matter if you explicitly await these child tasks or not. The outer task will implicitly await for all that concurrent work at the very end (before the return) if you didn’t explicitly await it earlier than that. Thus, as long as the top-level Task that owns all these child tasks is awaitable in the tests, then doing so will await all those concurrent child tasks as well.

It’s only the unstructured part of concurrency we need to worry about. That is handled by Task.init, and our TaskScheduler abstraction covers it.

(It’s becoming popular to claim that “unstructured concurrency is bad” and that you should replace all instances of it with structured concurrency, but this doesn’t make sense. Structured concurrency might very well be called structured awaiting. When you actually don’t want one thing to await another, i.e. genuine concurrency, unstructured concurrency is exactly what you need. The view model where we made init async throws is an example: it’s not correct to use async let to kick off the fetch work, because that causes init to await that child task, and destroys the very concurrency we’re seeking to create.)

Things look pretty similar in other platforms/frameworks, with some small caveats. In Kotlin, the way to spawn concurrent work is by calling CoroutineScope.launch. There’s a global one available, but many times you need to launch coroutines from other scope. This is nice because this is already basically the abstraction we need. Just make it configurable in tests, and make a decorator for CoroutineScope that additionally records the launched coroutines and lets you await them all. You might even be able to do this by installing a spy with mockk.

In .NET, the equivalent to Task.init in Swift is Task.Run:

void SpawnATask() {
  Task.Run(async () => { await DoSomeWork(); });
}

Task DoSomeWork() async {
  ...
}

Task.Run is really Task.Factory.StartNew with parameters set to typical defaults. Whichever one you need, you can wrap it in a TaskScheduler interface. Let’s assume Task.Run is good enough for our needs:

interface ITaskScheduler {
  Task Schedule(Func<Task> work);
  Task<TResult> Schedule<TResult>(Func<TResult> work);
  Task<TResult> Schedule<TResult>(Func<Task<TResult>> work);
}

struct DefaultTaskScheduler: ITaskScheduler {
  Task Schedule(Func<Task> work) {
    Task.Run(work);
  }

  Task<TResult> Schedule<TResult>(Func<TResult> work) {
    Task.Run(work);
  }

  Task<TResult> Schedule<TResult>(Func<Task<TResult>> work) {
    Task.Run(work);
  }
}

Then we replace naked Task.Run with this abstraction:

void SpawnATask(ITaskScheduler scheduler) {
  scheduler.Schedule(async () => { await DoSomeWork(); });
}

And similarly we can make a RecordingTaskScheduler to allow tests to await all scheduled work:

sealed class RecordingTaskScheduler: ITaskScheduler {
  public IImmutableQueue<Task> RunningTasks { get; private set; } = ImmutableQueue.Empty;

  Task AwaitAll() async {
    while !RunningTasks.IsEmpty {
      Task task = RunningTasks.Dequeue();
      await task;
    }
  }

  Task Schedule(Func<Task> work) {
    var task = _scheduler.schedule(work);
    RunningTasks = RunningTasks.Enqueue(task);
    return task;
  }

  Task<TResult> Schedule<TResult>(Func<TResult> work) {
    var task = _scheduler.schedule(work);
    RunningTasks = RunningTasks.Enqueue(task);
    return task;
  }

  Task<TResult> Schedule<TResult>(Func<Task<TResult>> work) {
    var task = _scheduler.schedule(work);
    RunningTasks = RunningTasks.Enqueue(task);
    return task;
  }

  RecordingTaskScheduler(ITaskScheduler scheduler) {
    _scheduler = scheduler;
  }

  static RecordingTaskScheduler Recorded(this ITaskScheduler scheduler) {
    new(scheduler);
  }

  private ITaskScheduler _scheduler;
}

Because in C#, generic classes are generally created as subclasses of a non-generic flavor (Task<TResult> is a subclass of Task), we don’t have to do any extra work to abstract over tasks of all result types.

There’s a shark in the water, though.

Async/await works a little differently in C# than in Swift. Kotlin is Swiftlike, while Typescript and C++ are C#-like in this regard.

In C# (and Typescript and C++), there aren’t really two types of functions (sync and async). The async keyword is just a request to the compiler to rewrite your function to deal with the awaits and return a special type, like Task or Promise (you have to write your own in C++). And correspondingly, an async function can’t just return anything, it has to return one of these special types. But that’s all that’s different. Specifically, you can call async functions from anywhere in these languages. What you can’t do in non-async functions is await. You can call that async function from a non-async function, you just can’t await the result, which is always going to be some awaitable type like Task or Promise.

Long story short, you can do this:

void SpawnATask() {
  DoSomeWork();
}

Task DoSomeWork() async {
  ...
}

There’s a slight difference in how this executes, compared to wrapping it in Task.Run, but I certainly hope you aren’t writing code that depends in any way on that difference. So you should be able to wrap it in Task.Run, and then change that to scheduler.Schedule.

But before you make that change, this is a sneaky little ninja lurking around in your codebase. It’s really easy to miss. If you’re running a test, it’s failing clearly due to not waiting long enough, and you’re going crazy because you searched for every last Task.Run (or Task. in general) in your code base, the culprit can be one of these crypto task constructors that you’d never even notice is spawning concurrent work. Just keep that in mind. Again, it should be fine to wrap it in scheduler.Schedule.

This isn’t a thing in Swift/Kotlin because they do async/await differently. In those languages there are two types of functions, and you simply aren’t allowed to call async functions from non-async ones. You have to explicitly call something like Task.init to jump from one to another.

A Not So Good Solution

This is not a new problem. I showed earlier that we can handle the concurrency with DispatchQueue. Similarly, and I’ve done this plenty of times, you would write an abstraction that captures work scheduled on global queues so the test can synchronize with it…

…well, no that’s not exactly what I did. I did something a little different. First I made a protocol so that I can customize what happens when I dispatch something to a queue:

protocol DispatchQueueProtocol {
  func async(
    group: DispatchGroup?, 
    qos: DispatchQoS, 
    flags: DispatchWorkItemFlags, 
    execute work: @escaping @convention(block) () -> Void
  )
}

extension DispatchQueueProtocol {
  // Deal with default parameters
  func async(
    group: DispatchGroup? = nil, 
    qos: DispatchQoS = .unspecified, 
    flags: DispatchWorkItemFlags = [], 
    execute work: @escaping @convention(block) () -> Void
  ) {
    // Beware of missing conformance and infinite loops!
    self.async(
      group: group,
      qos: qos,
      flags: flags,
      execute: work
    )
  }
}

extension DispatchQueue: DispatchQueueProtocol {}

Just as with the scheduler, the view model takes a dispatch queue as an init parameter:

final class MyViewModel: ObservableObject {
  @Published
  var results: [String]?

  init(
    backgroundQueue: some DispatchQueueProtocol = DispatchQueue.global(),
    mainQueue: some DispatchQueueProtocol = DispatchQueue.main
  ) {
    backgroundQueue.async {
            
      URLSession.shared.dataTask(with: .init(url: .init(string: "")!)) { data, response, _ in
        guard let data, let response else {
          return
        }
                
        mainQueue.async {
          self.results = try? JSONDecoder().decode([String].self, from: data)
        }
      }
    }
  }
}

Then I defined a test queue that didn’t actually queue anything, it just ran it outright:

struct ImmediateDispatchQueue: DispatchQueueProtocol {
  func async(
    group: DispatchGroup?, 
    qos: DispatchQoS, 
    flags: DispatchWorkItemFlags, 
    execute work: @escaping @convention(block) () -> Void
  ) {
    work()
  }
}

And if I supply this queue for both queue parameters in the test, then it doesn’t need to wait for anything. I have, in fact, removed concurrency from the code entirely. That certainly solves the problem the test was having!

This is often the go-to solution for these kinds of problems: if tests are intermittently failing because of race conditions, just remove concurrency from the code while it is being tested. How would you do this with the async-await version? You need to be able to take control of the “executor”: the underlying object that’s responsible for running the synchronous slices of async functions between the awaits. The default executor is comparable to DispatchQueue.global, it uses a shared thread pool to run everything. You would replace this with something like an ImmediateExecutor, which just runs the slice in-line. That causes “async” functions to become synchronous.

Substituting your own executor is possible in C# and Kotlin. It’s not in Swift. They made one step in this direction in 5.9, but they’re still working on it.

However, even if it was possible, I don’t think it’s a good idea.

Changing the underlying execution model from asynchronous to synchronous significantly changes what you’re testing. Your test is running something that is quite different than what happens in prod code. For example, by making everything synchronous and running in a single thread, everything becomes thread safe by default (not necessarily reentrant). If there are any thread safety issues with the “real” version that runs concurrently, your test will be blind to that. On the opposite side, you might encounter deadlocks by running everything synchronously that don’t happen when things run concurrently.

It’s just not as accurate as a test as I’d like. I want to exercise that concurrent execution.

That’s why I prefer to not mess with how things execute, and just record what work has been scheduled so that the test can wait on it. This is a little more convoluted to get working in the DispatchQueue version, but we can do it:

final class RecordingDispatchQueue<Queue: DispatchQueueProtocol>: DispatchQueueProtocol {
  private(set) var runningTasks: [DispatchGroup] = []

  func waitForAll(onComplete: @escaping () -> Void) {
    let outerGroup = DispatchGroup() 
    while let innerGroup = runningTasks.first {
      runningTasks.removeFirst()
      outerGroup.enter()
      innerGroup.notify(queue: .global(), execute: outerGroup.leave)
    }
    
    outerGroup.notify(queue: .global(), execute: onComplete)
  }

  func async(
    group: DispatchGroup?, 
    qos: DispatchQoS, 
    flags: DispatchWorkItemFlags, 
    execute work: @escaping @convention(block) () -> Void
  ) {
    let group = DispatchGroup()
    group.enter()

    queue.async {
      work()
      group.leave()
    }

    runningTasks.append(group)
  }

  init(queue: Queue) {
    self.queue = queue
  }

  private let queue: Queue
}

extension DispatchQueueProtocol {
  var recorded: RecordingDispatchQueue<Self> {
    .init(queue: self)
  }
}

Then in the tests:

final class MyViewModelTests: XCTestCase {
  func testLoadData() {
    let mockResults = setupMockServerResponse()

    let backgroundQueue = DispatchQueue.global().recorded
    let mainQueue = DispatchQueue.main.recorded

    let viewModel = MyViewModel(
      backgroundQueue: backgroundQueue,
      mainQueue: mainQueue
    )

    let backgroundWorkComplete = self.expectation(description: "backgroundWorkComplete")
    let mainWorkComplete = self.expectation(description: "mainWorkComplete")

    backgroundQueue.waitForAll(onComplete: backgroundWorkComplete.fulfill)
    mainQueue.waitForAll(onComplete: mainWorkComplete.fulfill)

    waitForExpectations(timeout: 5.0, handler: nil)

    XCTAssertEqual(viewModel.results, mockResults)
  }
}

A lot less pretty than async-await, but functionally equivalent.

Solution 2: Rethink the Problem

Abstracting task scheduling gives us a way to add a hook for tests to record scheduled work and wait for all of it to complete before making its assertions. Instead of just randomly waiting and hoping it’s long enough for everything to finish, we expose the things we’re waiting for so we can known when they’re done. This solves the problem we had of the test needing to know how long to wait… but are we thinking about this correctly?

Why does the test need to be aware that tasks are being spawned and concurrent work is happening? Does the production code that uses the object we’re testing need to know all of that? It didn’t look that way. After all we started with working production code where no scheduling abstraction was present, the default scheduling mechanism (like Task.init) was hardcoded inside the private implementation details of MyViewModel, and yet… everything worked. Specifically, the object interacting with the MyViewModel, MyView, didn’t know and didn’t care about any of this.

Why, then, do the tests need to care? After all, why in general do tests need to know about private implementation details? And it is (or at least was, before we exposed the scheduler parameter) a totally private implementation detail than any asynchronous scheduling was happening at all.

What were we trying to test? We wanted to test, basically, that our view shows a spinner until results become ready, that those results will eventually become ready, and that they will be displayed once they are ready. We don’t want to involve the view in the test so we don’t literally look for spinners or text rows, instead we test that the view model instructs the view appropriately. The key is asking ourselves: why is this “we don’t know exactly when the results are ready” problem not a problem for the view? How does the view get notified that results are ready?

Aha!

The view model’s results are an @Published. It is publishing changes to its results to the outside world. See, we’ve already solved the problem we have in tests. We had to, because it’s a problem for production code too. It’s perhaps obscured a bit inside the utility types in SwiftUI, but the view is notified of updates by being bound to an ObservableObject, that has a objectWillChange publisher that fires any time any of its @Published members are about to change (specifically in willSet). This triggers an evaluation of the view’s body in the next main run loop cycle, where it reads from viewModel.results.

So, we just need to simulate this in the test:

final class MyViewModelTests: XCTestCase {
  @MainActor
  func testLoadData() async throws {
    let mockResults = setupMockServerResponse()

    let viewModel = MyViewModel()

    let updates = viewModel
      .objectWillChange
      .prepend(Just()) // We want to inspect the view model immediately in case the change already occurred before we start observing
      .receive(on: RunLoop.main) // We want to inspect the view model after updating on the next main run loop cycle, just like the view does

    for await _ in updates.values {
      guard let results = viewModel.results else {
        continue
      }

      XCTAssertEqual(viewModel.results, mockResults)
      break
    }
  }
}

Now this test is faithfully testing what the view does, and how a manual tester would react to it: the view model’s results are reevaluated each time the view model announces it updated, and we wait until results appear. Then we check that they equal the results we expect.

With this, a stalling test is now a concern. If the prod code is broken, the results may never get set, and then this will wait forever. So we should throw it in some sort of timeout check. Usually test frameworks come with timeouts already. Unfortunately XCTestCase only has a resolution of 1 minute. It would be nice to specify something like 5 seconds, so we can write our own withTimeout function (I won’t show the implementation here):

final class MyViewModelTests: XCTestCase {
  @MainActor
  func testLoadData() async throws {
    let mockResults = setupMockServerResponse()

    let viewModel = MyViewModel()

    let updates = viewModel
      .objectWillChange
      .prepend(Just()) // We want to inspect the view model immediately in case the change already occurred before we start observing
      .receive(on: RunLoop.main) // We want to inspect the view model after updating on the next main run loop cycle, just like the view does
 
    try await withTimeout(seconds: 5.0) {
      for await _ in updates.values {
        guard let results = viewModel.results else {
          continue
        }

        XCTAssertEqual(viewModel.results, mockResults)
        break
      }
    }
  }
}

The mindset here is to think about why anyone cares that this concurrent work is started to begin with. The only reason why anyone else would care is that they have access to some kind of state or notification that is changed or triggered by the concurrent task. Whatever that is, it’s obviously public (otherwise no one else could couple to it, and we’re back to the original question), so have your test observe that instead of trying to hook into scheduling of concurrent work.

In this example, it was fairly obvious what the observable side effect of the task running was. It may not always be obvious, but it has to exist somewhere. Otherwise you’re trying to test a process that no one can possibly notice actually happened, in which case why is it a requirement (why are you even running that task)? Whether this is setting some shared observable state, triggering some kind of event that can be subscribed to, or sending a message out to an external system, all of those can be asserted on in tests. You shouldn’t need to be concerned about tasks finishing, that’s an implementation detail.

Conclusion

We found a way to solve the immediate problem of a test not knowing how long to wait for asynchronous work to complete. As always, introducing an abstraction is all that’s needed to be able to insert a test hook that provides the missing information.

But the more important lesson is that inserting probes like this into objects to test them raises questions: why would you need to probe an object in a way production code can’t to test the way that object behaves from the perspective of the production objects that interact with it (that is, after all, all that matters)? I’m not necessarily saying there’s never a good answer for this. At the very least it may replace a more faithful (in terms of recreating what users do) but extremely convoluted, slow and unreliable test with a much more straightforward, fast and reliable one that “cheats” slightly (is the risk of the convolutedness, skipping runs because it’s slow and ignoring its results because it’s unreliable more or less than the risk of producing invalid results by cheating?).

But you should always ask this question, and settle for probing the internals of behavior only after you have exhaustively concluded that it really is necessary, and for good reason. In the case of testing concurrent tasks, the point of waiting for tasks to “complete” is that the tasks did something, and it’s this side effect that you care about. You should assert on the side effect, which is the only real meaningful test that code executed (and it’s all that matters).

In general, if you write concurrent code, you will already solve the notification problem for the sake of production code. You don’t need to insert more hooks to observe the status of jobs in tests. The only reason the status of that job could matter is because it affects something that is already visible, and it is possible to listen to and be immediately notified of when that change happens. Whether it’s an @Published, an Observable/Publisher, a notification, event, C# delegate, or whatever else, you have surely already introduced one of these things into your code after introducing a concurrent task. Either that, or you’re calling out to an external system, and that can be mocked.

Just find that observable state that the job is affecting, and then you have something to listen to in tests. Introducing the scheduling interface is a way to quickly cover areas with tests and get reliable passing, but you should always revisit this and figure out what the proper replacement is.

On Code Readability

Introduction

I have many times encountered the statement from developers that “90% of time is spent reading code”, and therefore readability is a very important quality of code. So important, in fact, that it can overtake other qualities. This is almost always used to justify less abstract code. Highly abstracted code can be “hard to read”, so much so that it’s positive qualities (less duplication, more scalable and maintainable, etc.) may be invalidated by the fact it is just so hard to read. More “straightforward” code, perhaps with the lower level details spelled out explicitly in line may suffer problems of maintainability, but since we spend most of our time reading it, not making changes to it, the less abstract but easier to read code may still be better.

Since you hear this exact phrase (the 90% line), it’s obviously coming from some influential source. That would be Uncle Bob’s book, Clean Code: A Handbook of Agile Software Craftsmanship:

Indeed, the ratio of time spent reading versus writing is well over 10 to 1. We are constantly reading old code as part of the effort to write new code. …[Therefore,] making it easy to read makes it easier to write.

Now, he’s saying improving readability improves modifiability. But these discussions end up becoming about readability over modifiability. I’ll dig into why that matters.

Excuses for poorly abstracted code are abundant, particularly in “agile” communities. The first one I encountered was spoken by the first scrum master I ever had. Basically, since agile development is about rapid iteration, thinking design-wise more than two weeks ahead is wasteful, and you instead just want to focus on getting a barely working design out quickly, to complete the iteration before starting the next one.

Then, I heard more excuses later, ranging from YAGNI to “junior developers can’t understand this” to arguments about emergent design and “up-front design is bad” (the implication being that writing highly abstract code always counts as upfront design). There are a lot of misconceptions around this topic, especially the idea that building up a runway of library tools (i.e. abstractions) that can be quickly and easily composed into new features somehow hurts your ability to quickly implement new features with short turnaround (in other words, agility), but that’s not what I want to talk about here.

I just want to talk about this argument that “code should be easy to read”, implying that some other quality of it should be sacrificed. The reason I bring this other stuff up is to put it in context: developers are constantly looking for excuses to write less abstract code, so the “readability” argument isn’t unique at all. It’s just another of many avenues to reach the same conclusion. You should view these arguments with a bit of suspicion, as all of these unrelated premises land at the same place. Perhaps the conclusion was foregone, and people are working backward from it to various starting points.

(The simple, banal, reason developers look for excuses to not write abstract code is because abstracting is a form of low time preference: investing into the future instead of blowing all your money today, or running your credit card up. Investment requires delaying gratification, which is unpleasant here and now. It’s the same reason everyone wants to be fit but no one wants to go to the gym.)

For transparency’s sake, I’m the one who thinks abstraction, lots of it, is literally the only way any of us can begin to comprehend modern software. If you don’t believe me, remove all the abstractions and read the compiled code in assembly. This is why whenever I see a principle like YAGNI or readability used to conclude “un-abstracted code is better, actually”, I become extremely suspicious of the principle. At best it’s being completely misunderstood. Sometimes on closer inspection the principles turn out to be nonsensical.

I think that’s the case with “readability”. It doesn’t make sense as a principle of good software design.

Readability Is Largely Subjective

Let’s start by assuming the statement, “90% of time is spent reading code” is correct (I’m not sure how this could ever be measured… it feels accurate enough, but giving it a number like it was scientifically measured is just making it sound more authoritative), and let’s assume that this straightforwardly implies readability is 10 times more important than other qualities of the code.

I’m going to say something, the exact same thing, in two different ways. The only difference will be the phrasing. But the meaning of these two sentences are exactly equivalent:

  1. This code is hard to read
  2. I have a hard time reading this code

A skill I think everyone should learn is to pick on the habit of people using existential phrasing (sentences where the verb is “is”) to take themselves out of the picture. People will share their opinions, but instead of saying “I like Led Zeppelin more than the Beatles”, they say, “Led Zeppelin is better than the Beatles”. See the difference? By removing themselves as the subject, they are declaring their subjective judgements are objective traits of the things they are judging.

It’s not that you find this code hard to read, which is a description you and your reading abilities, it’s that the code is just hard to read, like it’s an innate quality of the code itself.

The implication is that all developers will always agree on which two versions of code is more readable. Hopefully I don’t have to emphasize or prove with examples that this is nowhere close to the truth. This is what leads to advice from developers that’s basically tautological: “you should write code that’s easy to read”. Who’s intentionally writing code that’s hard to read? This is like telling someone, “you should be less lazy”, as if anyone gets up in the morning and yells, “WOO, bring on the laziness!” Yeah, I know being lazy is bad, do you have any techniques for overcoming it, or just empty platitudes?

With the “readability” argument, developers are claiming, whether they realize it or not, that certain developers are consciously eschewing readability in favor of something else, like the DRY principle. Maybe some of them do, but that’s rather presumptuous. Why do you assume those developers don’t actually find the DRY code easier to read and understand? Maybe for them, having to see nearly identical blocks of code in multiple places, realizing the only difference is the name of a local variable, and reverse engineering in their head that it’s the same code and it’s doing something, and after looking at it for a moment they see it’s doing X, makes code harder to read than seeing a single line that’s a call to the function doX(someLocalVariable). Maybe they introduced the abstraction because, in their opinion, that improves readability.

Are you assuming they consciously rejected readability in favor of something else simply because you find it harder to read? Why are you assuming if you find it harder to read, everyone else must too?

Example 1: I have a book in my hand that’s written in Spanish. Embarrassing as this is, I’m not a polyglot. I only speak and read English. The Spanish classes I took in college didn’t take. How hard is it for me to read the Spanish book? Well, straight up impossible. I just can’t read it, at all. A native Spanish speaker, on the other hand, might find it quite easy to read. Or, if I bothered to learn the language, I could read it too.

Example 2: I spend more time than I’d like to admit in public reading physics textbooks. For me, an undergrad or grad level textbook on classical mechanics is an easy read. I haven’t read fiction since middle school. Any moderately sophisticated adult fiction book would probably leave me lost trying to figure out the metaphors and recall tiny plot hints that were dropped chapters ago that explain what I’m reading now. Maybe I’d figure it out, but I wouldn’t call it easy. Contrast this with, well, normal people, and I’m sure it’s the exact opposite: they breeze through the fiction, picking up on all the literary devices, and can’t get through the introductory math section of the physics textbook.

Now, some of this is difference in personality. I’m the kind of person who gets and likes math, and doesn’t really care about fictional stories, some people are the opposite. But a lot of it is practice. I find physics literature easy to read because I’ve spent a lot of time practicing. That grad level textbook was not easy the first time I read it, not even close. But it got easier each time I read it. The next one I read was easier because I already had experience. I would probably get better at reading fiction if I ever practiced it.

You see my point, right?

You can’t read highly abstracted code because you aren’t used to reading it.

It’s not an innate quality of the code. It’s a quality of you. The code doesn’t read itself.

I am not implying there are no objective qualities of code that would affect anyone’s ability to read it. The author could have scrambled the words into a random order. Yeah, that makes it harder to read for everyone. This is irrelevant because no one does this. No one sets out to write something that’s hard to read. If you suggest a change that everyone agrees, including its author, makes it easier to read, it’s going to be accepted with no resistance (the author probably just didn’t think of it), and “more readable code is good” didn’t help reveal that change (it’s an empty tautology). If the suggested change is controversial, it’s quite likely some people think the change degrades readability.

This is why “readability” can’t be a guideline for development teams. Either team members are going to disagree on which code is actually more readable, or they agree code is hard to read but can’t think of how to make it better. Telling them “make it more readable” doesn’t help in either case.

This applies not just to the level of abstraction, but the style and tools. Someone who’s never heard of ReactiveX would probably be totally bewildered by code written by someone who thinks “everything is an Observable“. But it’s easy to read for the author, and to anyone else who has years of experience reading that style of code.

My point is not that there’s no such thing as bad code. Of course not. It’s just that whether code is high or low quality has nothing to do with whether any particular developer is good at reading it or not.

We have the fortune of not having to learn to read assembly code. Coders in the 1960s, or even 90s, weren’t so lucky. Super Mario World was written in assembly. The authors were probably so good at reading assembly their brains would recognize control flow structures like loops and subroutines. They didn’t just see unrelated blocks of code, they saw Mario jumping around and hitting scenery and launching fireballs.

You’ll find highly abstracted code easy to read if you spend more time reading it, as long as you don’t approach it with a cynical attitude of “this is stupid, I shouldn’t have to put up with code like this”. Again, I’m not saying you have to like that code. It may be the worst code you’ve ever read. And you can still make it easy to read.

It’s somewhat ironic that I’ve spent enough of my career reading code I think was pretty poorly designed when I have to work on “legacy” apps, that I’ve gotten pretty damn good at reading bad code. It’s bad, but there’s a lot of it out there so it’s necessary for my job to be good at reading it.

How to Read Abstracted Code

I’m aware of a few differences in the way I read code compared to how I think developers, who especially don’t like highly abstracted code, read it. They are probably relevant to why I have an easier time reading such code.

The absolute biggest one is: I don’t feel a need to “click into” an implementation, or class, or other abstraction and read its implementation details simply because I encountered a use of it in code. If I ever do feel that urge, it immediately turns into an urge to rename something. The name should make it self-evident enough what role it’s playing in the code that’s calling it.

I should not need to open up a coffee machine and look at how all its gears and pumps are hooked together to know that it’s a coffee machine, and pressing the “brew” button is going to make coffee come out of it. But if it’s just an unlabeled machine with a blank button it, okay maybe I’d want to open it up to figure out what the hell it is. I could also just press the button and see what happens (for code, that means find the test that calls this method or instantiates this class, and if doesn’t exist, write it). Once I figure out what it is, I make sure to label it properly, so no one has to do that again.

The theme here is: when you organize a large codebase into modules, and you’re still clicking from one module to another while reading, or even worse stepping from one module to another during debugging, you’re doing it wrong. Want to challenge yourself? Put your library modules in different repos and consume them in your app through a package manager, in binary format. No source code available. You shouldn’t need a library’s source code while you’re working on the app that uses the library, and vice versa. This will also more or less force you to test the library with tests for the library instead of testing it indirectly through testing the app.

This is the single biggest complaint I’ve gotten from code I wrote for large applications with dozens of very similar screens. No, I’m not f**cking copy-pasting it 25 times. That’s a maintenance nightmare. But the complaint is, “I have to click through dozens of files just to get through a single behavior”. No, you don’t have to, you just do. Have you considered not clicking through? Have you done some self-reflection on what drives your need to dig through implementation details of implementation details to understand something? You usually can’t do that once you hit the platform SDKs. It’s not like there isn’t implementation details inside those classes, it’s just not publicly accessible. If you can stop there, why can’t you stop on abstractions in your source code?

The answer might be, “because they’re bad abstractions”. They’re badly named, or worse yet leaky, un-cohesive, slice an actual abstraction into pieces and scatter it around multiple files, combine two unrelated functionalities and select one with a parameter, etc. Yes, developers can absolutely do a bad job of abstracting. The solution is not to destroy the abstractions, it’s to fix them. This is why you need to ask yourself why you want to click into everything. There may be a good answer, and it may lead to an improvement in the code that’s a lot better than just inlining implementations everywhere.

Clicking into stuff isn’t always bad. But you need to treat it as a context switch. You unload everything from your brain you were reading before you clicked in. It’s irrelevant now. How you got to a method or class or whatever should have nothing to do with what that method or class is doing. If the meaning isn’t clear from just looking at the method or class, it needs a better name, or it’s a bad abstraction if it really requires context from the call site to understand.

How did I learn to read code like this? Practicing. The most reliable way to get better at X is to practice X. Do you want running a marathon to be easy? Then run some marathons. The first few will be really, really hard. They’ll get easier. Want to learn to play a musical instrument? Pick up the instrument and start playing it. It will be really hard at first. It will get easier.

Just because you can get better at reading a certain style of code doesn’t mean you should. I’m sure it’s a waste of time for any of us to get as good at reading assembly as the Super Mario World programmers were. It’s not a waste of time to get good at reading highly abstract code. Change it as soon as you can if you want, but you’ll only get faster at that if it’s easy to read.

Does Optimizing for Readability Even Make Sense?

Why cite the actual number for how much time we spend reading code? It’s 90%, apparently. The reason is because we humans really like simple relationships. Ideally, linear and proportional ones. We like to believe that if we can measure the proportions of time allocation on different activities, we can straightforwardly calculate the weights for different optimizations. If we spend X1% amount of time doing Y1, and X2% of time doing Y2, then optimizing Y2 will be X2/X1 times as important as optimizing Y1. We love these kinds of simple calculations.

This is why I never hesitate to remind people that physics problems become literally impossible to solve analytically as soon as you introduce… wait for it… three bodies. The number of problems in the world that are actually solvable with these kinds of basic algebra techniques are miniscule. We are heavily biased toward simplifying real problems down until they become solvable like this, destroying in the process any relevance the now toy model of the problem has to the real problem.

There are a lot of unspoken assumptions between the statement “we spend 90% of our time reading code and 10% of the time modifying it” and “optimizing readability is 10x more important than optimizing modifiability”, or even that optimizing readability is important at all. I’m going to try to bring out some of them, and we’re going to find they aren’t justifiable.

First, let’s clarify what exactly we’re trying to “optimize”, overall. Hopefully, as professional developers, we’re not merely trying to optimize for our own comfort. Of course making our jobs more pleasant is good for the profession, because we’re more eager to do our jobs, and we’re people who work to live, not faceless cogs in a corporate machine. But they’re still jobs (not, as Red Foreman says, “Super Happy Fun Time”). At the end of the day we’re being paid to deliver software.

It doesn’t matter if we spend 99.99999% of our time reading code.

We aren’t paid to read code.

We are literally paid to modify code. The only reason the reading is valuable at all is because it is a necessary precondition to the eventual modification.

Thus, optimizing for being happy during the 90% of our jobs when we aren’t actually producing deliverables is extremely dubious.

This is literally in Uncle Bob’s quote: that the reason improving readability is important is insofar as it improves writability. He was not pitting the two against each other.

But this problem is being framed as a “readability vs. modifiability” problem (some sort of tradeoff). Any adjustment of code that makes it simultaneously easier to read but harder to modify is absolutely detrimental to productivity, because the only actually productive phase is during modification. The only possible way readability could help productivity is because improving readability improves modifiability.

If you find it way easier to read less abstracted code, but directly at the expense of making it more complicated to modify it appropriately, how is this improving productivity? I totally get that it’s making your day more pleasant, since you’re spending 90% of that day reading instead of modifying the code. But is that what we’re optimizing for? You not tearing your hair out because you hate your job so much? I’m not being totally facetious. It is important for productivity that you not want to go postal every time you open your IDE. But this can’t come at the expense of you getting stuff done. You need a way to be happier and more productive.

A way to do that is get used to reading the code that’s driving you crazy. Over time it won’t drive you crazy. At worst you’ll start finding it funny.

Honestly I don’t think readability and modifiability are in competition very often, if ever. I think it’s a false dilemma, as I explained above, born out of developers being presumptuous that all other developers share their opinion about what code is easiest to read. Developers assume the person who wrote the code they’re staring at and finding hard to read was written by someone who agrees it’s hard to read but believed readability and some other quality (which is going to be some aspect of modifiability) were in competition, and he let the other quality win. I think it’s way more likely the author believes his version of the code is both easier to read and easier to modify, and the current reader simply disagrees with him about that.

Is It Good We Read Code This Much?

Another unspoken assumption here is that the ratio of reading to modifying is constant. Not just constant, but specifically independent of the ease of reading and modifying code. No matter how much the ease of either of these activities change, the assumption is made that the reading/modifying ratio will stay at 10/1. I mentioned above that, this number was probably pulled out of someone’s nether regions, and is completely meaningless (87.3% of all statistics are made up on the spot). Given that we’re just making up numbers, the only thing we could do if we wanted to model how this made up number is coupled to the other variables we’re thinking about modifying is to make up more facts about how this coupling works. But that’s still better than just assuming there’s no coupling at all.

It seems pretty natural to me that there should be some rather strong coupling between the reading/modifying allocation ratio and how easy/pleasant both of these activities are. I would assume that making code much, much easier to modify is likely to lower the read/modify time ratio. Now that’s interesting. Remember again that, if we apply productivity multipliers to both activities, modifying gets a full 100% (actually that’s too simple, sometimes it can be negative, more on that below), and reading gets a big fat goose egg (again, not implying you can optimize reading out of the equation, it’s indirectly productive). In terms of productivity then, anything that decreases the read/modify time ratio is literally increasing the amount of actual productive time. That cannot be ignored. It could also disproportionately reduce the rate of productivity during modification (“velocity”), so this doesn’t necessarily imply increased productivity.

So, perhaps it’s true that today developers typically spend 90% of their time reading code, and only 10% of the time modifying it. And maybe that’s a problem. Maybe that’s because most of the code bases we’re working on today are huge piles of ten-year-old spaghetti following a design that could barely scale to a 9 month old app, and we can’t help but stare at in disbelief for hours before finally mustering up the courage to edit one line and see if it actually accomplishes what we’re trying to do. Maybe we’re in this situation because so much code out there is a total maintenance nightmare, we can’t figure out how to do a 10 minute modification without rereading a chunk of code for an hour and half first. Maybe if we all wrote code with ease of modifiability as the primary goal, we wouldn’t need to preamble the next modification with such a massive amount of preparatory study.

Or maybe not. Maybe this is just how it goes, and it’s unreasonable to think it could be any different. But there’s a wide range of options here. It could be that spending any less than 90% of time reading code is just unreasonable, or it could mean that spending less than 50% of time reading code is unreasonable, but we’ve got a solid 40% of potential improvement to work with. Or somewhere in between.

A large amount of my time is spent neither reading nor writing code but simply thinking about the problem. I really believe this is the most crucial phase of my job. Software engineering is more creative than formulaic, it’s much more like architecture than construction. The most valuable moments for the businesses I work for are random epiphanies I have in the middle of a meal when I realize a certain design is perfectly suited for the new requirements, and this is followed by a three day bender where I’m almost exclusively writing code. The time allocation for this is kind of nonsensical because it is often just background while I’m doing other stuff.

Does time allocation really even matter for productivity? Recall that if you’re optimizing a software algorithm, when you find that 90% of time is spent on one part, your goal is to reduce that number.

Quality vs. Quantity

Readability is subjective. But there are objective qualities of writing that virtually everyone will subjectively agree makes it harder to read.

What’s easier for me to read? A press release or a Top Secret classified document? Okay, sure, the former is easier to read, by simple virtue of it being available to me. That’s not an accident. I’m not supposed to read the classified document.

Now, imagine your friend complains that a novel is hard to read. You inquire further, and determine she is frustrated that the novel doesn’t come with the author’s notes and early drafts added as an appendix. She exclaims, “how can I know what the author meant here if he’s not going to share his notes with me!?”

Okay… if you’re having trouble reading a novel because you can’t read the author’s notes about it, there’s something wrong with the way you’re approaching reading the novel. That extra stuff is intentionally not part of the book.

Now imagine your other friend is complaining a novel is hard to read. You inquire further, and find he is jumping around, reading all the odd chapters and then reading all the even chapters. He reads Chapter 1, then 3, then 5, and so on, then circles back and reads Chapter 2, then 4, etc.

After lamenting to yourself how you managed to find all of these friends, you ask him in bewilderment why he isn’t just reading the damn thing in order. The order is very intentional. Maybe the novel isn’t chronological, that’s very important to its structure, but your friend thinks all stories should be presented in chronological order and is jumping around trying to reorganize it in that way.

If your teammate wrote code you find hard to read, it’s quite possible your teammate finds it easy to read. It’s also possible that however you’re trying to read it, the author made that harder on purpose.

Reading code is only indirectly productive, and insofar as it aids in future modification, which is directly productive. It is also the case that not all modification is productive. Correct modification is productive. Incorrect modification (introducing bugs) is counterproductive. That’s even worse than reading, which is merely (directly) unproductive.

Another tendency I see among some developers is to be focused on how overall easy it is to make changes to code. This is definitely a big part of the arguments I hear in favor of non-compiled (basically not strongly typed) languages. Having to create types is hard, it makes every little change harder.

And changing is what we get paid for, so making changing code harder is bad, right?

F*** no it isn’t.

It isn’t if most changes are actually harmful.

It’s way, way easier to break code than it is to fix it or correctly add or modify functionality. Thus, most changes to code are actually harmful.

If you’re into XP, you love automated tests, right? TDD all the way right!? All a test does is stop you from modifying code. It does nothing but make editing production code harder. That’s why some developers hate test suites.

In my experience, high quality code is high quality not so much because it makes correct modification easier (this is the #2 aspect of high quality code) but because it makes incorrect modification harder (this is the #1 aspect). Thus, when I hear developers complaining that working on this code base, given its design, is too hard, I’m suspicious that they’re complaining their bugs are being found as they’re being typed instead of later by QA or customers.

Is it “easier” to read the internal details of a library class that are exposed to you than it is to read those that are encapsulated? Well, yeah. But that doesn’t mean you should expose everything as public to make it “easier” to find. Hiding stuff is a fundamental tool of improving software quality.

If “easier to read” means less abstraction, and all the implementation details spelled out right there so you don’t have to click around to find them, then this literally means less encapsulation. Less intentional hiding of stuff you might want to read but you damn well shouldn’t be because all reading it is going to do is make you want to couple to it.

Some parts of code need to be easy to read and understood by certain people in certain roles. Other parts of code, those people in those roles have no business reading it and doing so is likely to just confuse them or give them dangerous ideas. This is directly relevant to the way “readability” is often connected directly to abstraction.

Abstraction introduces boundaries, and intentionally moves one thing (an implementation detail) away from another thing (an invocation of the thing being implemented elsewhere) specifically because it is not helpful to read both at the same time. Doing so only feeds confusing and misleading ideas that they are relevant to each other, that they should be colocated, are likely to change together, that they form a cohesive unit, and have no independent meaning.

Highly abstract code does intentionally make certain approaches to reading code harder, as a direct corollary to it making certain approaches to modifying code harder. Properly abstracted code makes the modifications, plus the reading that likely precedes those modifications, that are not helpful and degrade the code quality, harder. This is a feature, not a bug.

The structure may be stopping you from even reading the code in a way that leads up to you making a damaging modification, especially if the main problem you’re having is that you’d have to punch through a bunch of encapsulation boundaries to do whatever it is you’re trying to do.

Conclusion

The overall thesis here is simple: readability has no simple relation to code quality. Readability has a large subjective component, and to the extent authors intentionally frustrate certain approaches to reading code, there can be valid reasons for doing so.

Even examples I try to come up with that I think are as objectively more readable as can be, like naming a variable thisSpecificThing instead of x, I know someone is gonna say, “no x is better because it’s more concise, the more concise the easier it is to read”. I can’t argue with that. I can’t tell someone they don’t like reading something they like reading. If I want to convince him to please name his variables descriptively, “more readable” isn’t a way to do it.

If you have trouble reading highly abstract code, you just need to practice reading it, which will help you understand why it discourages certain reading strategies. It’s also really helpful to practice writing it. If you always tell yourself you don’t have time or it’s not agile enough, when will you ever get this practice?

There’s nothing intrinsically unreadable about even extremely DRY’d heavily templated and layered code. It may even be excessive or inappropriate abstraction (I don’t like saying “excessive”, what matters is quality, not quantity), but even that code can be easy to read if you just practice doing so. Then you’ll get really good at improving it.

The rules of thumb for achieving high code quality need to be objective, not subjective. Examples of subjective (or at best tautological, they’re all fancy synonyms for “good”) qualities are:

  • Readable
  • “Clean” (what does this mean? You wiped your code down with Lysol?)
  • Simple
  • Understandable

Examples of qualities that are objective but so vague that they aren’t functional rules of thumb on their own (they are rather guiding principles for producing the rules of thumb) are:

  • Scalable
  • Maintainable
  • Agile
  • Modular
  • Reusable
  • Resilient
  • Stable

Examples of objective rules of thumb are (you may agree or disagree if these are good rules, I’m just giving examples of rules that are objective):

  • Everything is private by default
  • Use value semantics until you need reference semantics
  • Always couple to the highest possible level of abstraction (start with types at the top of the hierarchy, and cast down only once needed)
  • Law of Demeter (never access a dependency’s dependencies directly)
  • Use inheritance for polymorphism, use composition for sharing code
  • Make all required dependencies of a class constructor parameters (don’t allow constructed but nonfunctional instances)
  • Use a single source of truth for state, and only introduce caching when performance measurements prove it necessary
  • Don’t use dynamic dispatch for build-time variations
  • Use dynamic dispatch over procedural control flow
  • View should only react to model changes and never modify themselves directly

You see the difference right? Good or bad, these rules actually tell you something concrete. It’s a matter of fact whether you are following them or not, rather than subjective preferences.

The first category, in my opinion, is useless. The second category is useful only as a means of generating statements in the last category. It’s the last category that should go in the style guide of your README.

Being in the first category, I think developers should stop talking about readability. I mean, if they just want to complain, confiding with their fellow team members how frustrating their job can be, that’s fine. But citing “improve readability” as any kind of functional advice or guiding principle… it’s not. And if you have trouble reading code, reframe that as an opportunity for you to grow. After all, we’re software engineers, our job is to be good at reading and understanding code.